diff --git a/.github/actions/setup-greptimedb-cluster/with-remote-wal-logical-prune.yaml b/.github/actions/setup-greptimedb-cluster/with-remote-wal-logical-prune.yaml
index 60c23def6e2..3b25e80a8f2 100644
--- a/.github/actions/setup-greptimedb-cluster/with-remote-wal-logical-prune.yaml
+++ b/.github/actions/setup-greptimedb-cluster/with-remote-wal-logical-prune.yaml
@@ -3,6 +3,7 @@ logging:
format: "json"
filters:
- log_store=debug
+ - rskafka=debug
meta:
configData: |-
[runtime]
diff --git a/.github/actions/setup-greptimedb-cluster/with-remote-wal.yaml b/.github/actions/setup-greptimedb-cluster/with-remote-wal.yaml
index ec595b9e9b8..6a15b25b422 100644
--- a/.github/actions/setup-greptimedb-cluster/with-remote-wal.yaml
+++ b/.github/actions/setup-greptimedb-cluster/with-remote-wal.yaml
@@ -3,6 +3,7 @@ logging:
format: "json"
filters:
- log_store=debug
+ - rskafka=debug
meta:
configData: |-
[runtime]
diff --git a/.github/actions/setup-kafka-cluster/action.yml b/.github/actions/setup-kafka-cluster/action.yml
index fca420da709..3c30ca285e3 100644
--- a/.github/actions/setup-kafka-cluster/action.yml
+++ b/.github/actions/setup-kafka-cluster/action.yml
@@ -16,8 +16,8 @@ runs:
helm upgrade \
--install kafka oci://registry-1.docker.io/bitnamicharts/kafka \
--set controller.replicaCount=${{ inputs.controller-replicas }} \
- --set controller.resources.requests.cpu=50m \
- --set controller.resources.requests.memory=128Mi \
+ --set controller.resources.requests.cpu=500m \
+ --set controller.resources.requests.memory=512Mi \
--set controller.resources.limits.cpu=2000m \
--set controller.resources.limits.memory=2Gi \
--set listeners.controller.protocol=PLAINTEXT \
diff --git a/.github/scripts/query-regression-run.py b/.github/scripts/query-regression-run.py
index b89857be81f..62d11f44203 100644
--- a/.github/scripts/query-regression-run.py
+++ b/.github/scripts/query-regression-run.py
@@ -26,6 +26,10 @@ from pathlib import Path
DEFAULT_CASES = [
"tests/perf/query_cases/smoke_direct_sst/case.toml",
+ "tests/perf/query_cases/prom_remote_write_seeded_random/case.toml",
+ "tests/perf/query_cases/prom_remote_write_run_heavy/case.toml",
+ "tests/perf/query_cases/prom_remote_write_mixed_every/case.toml",
+ "tests/perf/query_cases/prom_remote_write_integer_counter/case.toml",
"tests/perf/query_cases/promql_pushdown_7913/case.toml",
"tests/perf/query_cases/sql_topk_order_by/case.toml",
"tests/perf/query_cases/sql_aggregate_order_by/case.toml",
@@ -106,8 +110,6 @@ def run_case(args: argparse.Namespace, case_path: Path, work_dir: Path) -> int:
str(candidate_bin),
"--fixture-generator",
str(fixture_generator),
- "--remote-write-generator",
- str(args.remote_write_generator),
"--work-dir",
str(work_dir),
"--http-timeout",
@@ -160,11 +162,6 @@ def main() -> int:
parser.add_argument("--work-dir", default=Path("query-regression-work"), type=Path)
parser.add_argument("--http-timeout", default=os.environ.get("HTTP_TIMEOUT", "300"))
parser.add_argument("--allow-large-fixture", default=os.environ.get("ALLOW_LARGE_FIXTURE", "false"))
- parser.add_argument(
- "--remote-write-generator",
- type=Path,
- default=configured_path(os.environ.get("REMOTE_WRITE_GENERATOR")),
- )
parser.add_argument(
"--summary-script",
type=Path,
@@ -177,9 +174,6 @@ def main() -> int:
parser.add_argument("--candidate-ref", default=os.environ.get("CANDIDATE_REF", ""))
parser.add_argument("--github-output", default=os.environ.get("GITHUB_OUTPUT"))
args = parser.parse_args()
- if args.remote_write_generator is None:
- args.remote_write_generator = args.candidate_src / "target" / profile_dir(args.cargo_profile) / "prom_remote_write_fixture"
-
try:
cases = split_cases(args.cases or [os.environ.get("CASE_PATHS", "all")])
except ValueError as err:
diff --git a/.github/workflows/query-regression.yml b/.github/workflows/query-regression.yml
index a898be6ad29..619442e2f95 100644
--- a/.github/workflows/query-regression.yml
+++ b/.github/workflows/query-regression.yml
@@ -119,10 +119,15 @@ jobs:
git reset --hard FETCH_HEAD
git clean -ffdx
+ - name: Test query regression runner lifecycle
+ working-directory: src
+ run: uv run --no-project python tests/perf/test_query_regression_runner_compaction_toctou.py
+
- name: Build candidate greptime and fixture generators
working-directory: src
run: |
- cargo build --profile "${CARGO_PROFILE}" -p cmd --bin greptime --bin query_perf_fixture --bin prom_remote_write_fixture
+ cargo build --profile "${CARGO_PROFILE}" -p cmd --bin greptime
+ cargo build --profile "${CARGO_PROFILE}" -p cmd --bin query_perf_fixture --features dev-tools
target_dir="${CARGO_PROFILE}"
if [[ "${CARGO_PROFILE}" == "dev" ]]; then
target_dir="debug"
@@ -132,8 +137,6 @@ jobs:
"${GITHUB_WORKSPACE}/query-regression-bins/candidate/greptime"
cp "${CARGO_TARGET_DIR}/${target_dir}/query_perf_fixture" \
"${GITHUB_WORKSPACE}/query-regression-bins/candidate/query_perf_fixture"
- cp "${CARGO_TARGET_DIR}/${target_dir}/prom_remote_write_fixture" \
- "${GITHUB_WORKSPACE}/query-regression-bins/candidate/prom_remote_write_fixture"
- name: Run query regression
id: run
@@ -146,7 +149,6 @@ jobs:
BASE_BIN: ${{ github.workspace }}/query-regression-bins/base/greptime
CANDIDATE_BIN: ${{ github.workspace }}/query-regression-bins/candidate/greptime
FIXTURE_GENERATOR: ${{ github.workspace }}/query-regression-bins/candidate/query_perf_fixture
- REMOTE_WRITE_GENERATOR: ${{ github.workspace }}/query-regression-bins/candidate/prom_remote_write_fixture
run: >-
uv run --no-project python src/.github/scripts/query-regression-run.py
--base-src src
@@ -171,9 +173,13 @@ jobs:
with:
name: query-regression-report
path: |
- query-regression-work/**
+ query-regression-work/**/query-regression-report.json
+ query-regression-work/**/base/report.json
+ query-regression-work/**/candidate/report.json
+ query-regression-work/**/logs/**
query-regression-summary.md
if-no-files-found: warn
+ retention-days: 7
- name: Upload trusted comment artifact
if: ${{ always() && github.event_name == 'pull_request' }}
diff --git a/Cargo.lock b/Cargo.lock
index e00e30e28a6..75ba5ce410b 100644
--- a/Cargo.lock
+++ b/Cargo.lock
@@ -11038,9 +11038,9 @@ dependencies = [
[[package]]
name = "promql-parser"
-version = "0.7.3"
+version = "0.10.0"
source = "registry+https://github.com/rust-lang/crates.io-index"
-checksum = "f514ab521bb2b4ce26aca29bf133498b2a2651b785d03a262bbf5772329c279f"
+checksum = "9e8c90c956be4237a93be6f2298302b56974ef862ab11e0f98869d1f27c69f88"
dependencies = [
"cfgrammar",
"chrono",
@@ -11183,7 +11183,7 @@ source = "registry+https://github.com/rust-lang/crates.io-index"
checksum = "8a56d757972c98b346a9b766e3f02746cde6dd1cd1d1d563472929fdd74bec4d"
dependencies = [
"anyhow",
- "itertools 0.11.0",
+ "itertools 0.14.0",
"proc-macro2",
"quote",
"syn 2.0.117",
@@ -11196,7 +11196,7 @@ source = "registry+https://github.com/rust-lang/crates.io-index"
checksum = "9120690fafc389a67ba3803df527d0ec9cbbc9cc45e4cc20b332996dfb672425"
dependencies = [
"anyhow",
- "itertools 0.11.0",
+ "itertools 0.14.0",
"proc-macro2",
"quote",
"syn 2.0.117",
diff --git a/Cargo.toml b/Cargo.toml
index 5ee60c450e8..fd878c7c0a1 100644
--- a/Cargo.toml
+++ b/Cargo.toml
@@ -198,7 +198,7 @@ paste = "1.0"
pin-project = "1.0"
pretty_assertions = "1.4.0"
prometheus = { version = "0.14", features = ["process"] }
-promql-parser = { version = "0.7.3", features = ["ser"] }
+promql-parser = { version = "0.10.0", features = ["ser"] }
prost = { version = "0.14", features = ["no-recursion-limit"] }
prost-types = "0.14"
raft-engine = { version = "0.4.1", default-features = false }
diff --git a/README.md b/README.md
index 3ba52bc5266..99c78814609 100644
--- a/README.md
+++ b/README.md
@@ -209,7 +209,13 @@ Read the [v1.0 highlights](https://greptime.com/blogs/2025-11-05-greptimedb-v1-h
If GreptimeDB is useful to you, please star the repo.
-[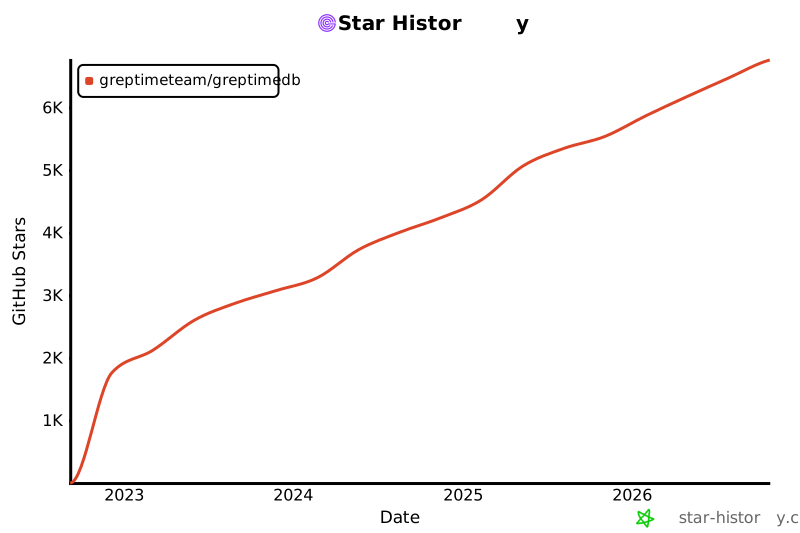](https://www.star-history.com/#GreptimeTeam/GreptimeDB&Date)
+
+
+
+
+  +
+
 diff --git a/src/cmd/Cargo.toml b/src/cmd/Cargo.toml
index a8adfa01a48..b06da6e517a 100644
--- a/src/cmd/Cargo.toml
+++ b/src/cmd/Cargo.toml
@@ -12,10 +12,7 @@ path = "src/bin/greptime.rs"
[[bin]]
name = "query_perf_fixture"
path = "src/bin/query_perf_fixture.rs"
-
-[[bin]]
-name = "prom_remote_write_fixture"
-path = "src/bin/prom_remote_write_fixture.rs"
+required-features = ["dev-tools"]
[features]
default = [
@@ -25,7 +22,7 @@ default = [
"meta-srv/mysql_kvbackend",
]
enterprise = ["common-meta/enterprise", "frontend/enterprise", "meta-srv/enterprise"]
-# Developer-only tools (benchmarks, diagnostics) gating the `datanode parquetbench` subcommand.
+# Developer-only helper binary gate for `query_perf_fixture`.
# Kept out of `default` so normal/release builds don't compile them.
dev-tools = []
tokio-console = ["common-telemetry/tokio-console"]
diff --git a/src/cmd/src/bin/greptime.rs b/src/cmd/src/bin/greptime.rs
index e0f326908a2..957e227355a 100644
--- a/src/cmd/src/bin/greptime.rs
+++ b/src/cmd/src/bin/greptime.rs
@@ -117,7 +117,6 @@ async fn start(cli: Command) -> Result<()> {
}
datanode::SubCommand::Objbench(ref bench) => bench.run().await,
datanode::SubCommand::Scanbench(ref bench) => bench.run().await,
- #[cfg(feature = "dev-tools")]
datanode::SubCommand::Parquetbench(ref bench) => bench.run().await,
},
SubCommand::Flownode(cmd) => {
diff --git a/src/cmd/src/bin/prom_remote_write_fixture.rs b/src/cmd/src/bin/prom_remote_write_fixture.rs
deleted file mode 100644
index 0bfdf954823..00000000000
--- a/src/cmd/src/bin/prom_remote_write_fixture.rs
+++ /dev/null
@@ -1,144 +0,0 @@
-// Copyright 2023 Greptime Team
-//
-// Licensed under the Apache License, Version 2.0 (the "License");
-// you may not use this file except in compliance with the License.
-// You may obtain a copy of the License at
-//
-// http://www.apache.org/licenses/LICENSE-2.0
-//
-// Unless required by applicable law or agreed to in writing, software
-// distributed under the License is distributed on an "AS IS" BASIS,
-// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
-// See the License for the specific language governing permissions and
-// limitations under the License.
-
-#![allow(clippy::print_stdout)]
-
-use std::time::{Duration, Instant};
-
-use api::prom_store::remote::{Label, Sample, TimeSeries, WriteRequest};
-use clap::Parser;
-use prost::Message;
-use serde_json::json;
-use servers::prom_store::snappy_compress;
-
-#[derive(Debug, Parser)]
-#[command(about = "Generate a deterministic Prometheus remote-write fixture")]
-struct Args {
- #[arg(long, default_value = "http://127.0.0.1:4000/v1/prometheus/write")]
- endpoint: String,
- #[arg(long, default_value = "public")]
- database: String,
- #[arg(long)]
- metric: String,
- #[arg(long, default_value = "greptime_physical_table")]
- physical_table: String,
- #[arg(long, default_value_t = 8)]
- series_count: u64,
- #[arg(long, default_value_t = 30)]
- samples_per_series: u64,
- #[arg(long, default_value_t = 1_704_067_200_000)]
- start_unix_millis: i64,
- #[arg(long, default_value_t = 15_000)]
- step_millis: i64,
- #[arg(long, alias = "batch-size", default_value_t = 8)]
- chunk_series_count: u64,
- #[arg(long, default_value_t = 60)]
- timeout_seconds: u64,
-}
-
-#[tokio::main]
-async fn main() -> Result<(), Box> {
- let args = Args::parse();
- let started = Instant::now();
- let client = reqwest::Client::builder()
- .timeout(Duration::from_secs(args.timeout_seconds))
- .build()?;
- let mut batches = 0_u64;
- let mut rows = 0_u64;
- let mut http_statuses = Vec::new();
-
- let chunk = args.chunk_series_count.max(1);
- for first in (0..args.series_count).step_by(chunk as usize) {
- let last = (first + chunk).min(args.series_count);
- let timeseries = (first..last)
- .map(|series_idx| make_series(&args, series_idx))
- .collect::>();
- rows += timeseries
- .iter()
- .map(|ts| ts.samples.len() as u64)
- .sum::();
- let body = snappy_compress(
- &WriteRequest {
- timeseries,
- ..Default::default()
- }
- .encode_to_vec(),
- )?;
- let response = client
- .post(&args.endpoint)
- .header("Content-Encoding", "snappy")
- .body(body)
- .send()
- .await?;
- let status = response.status();
- http_statuses.push(status.as_u16());
- if !status.is_success() {
- let body_text = response.text().await.unwrap_or_default();
- return Err(format!("remote-write failed with status {status}: {body_text}").into());
- }
- batches += 1;
- }
-
- println!(
- "{}",
- json!({
- "status": "ok",
- "endpoint": args.endpoint,
- "database": args.database,
- "metric": args.metric,
- "physical_table": args.physical_table,
- "series_count": args.series_count,
- "samples_per_series": args.samples_per_series,
- "rows": rows,
- "samples_written": rows,
- "batches": batches,
- "elapsed_seconds": started.elapsed().as_secs_f64(),
- "http_statuses": http_statuses,
- })
- );
- Ok(())
-}
-
-fn make_series(args: &Args, series_idx: u64) -> TimeSeries {
- let mut labels = vec![
- label("__name__", &args.metric),
- label("x_greptime_database", &args.database),
- label("x_greptime_physical_table", &args.physical_table),
- label("host", &format!("host{:04}", series_idx % 1024)),
- label("instance", &format!("instance{:06}", series_idx)),
- ];
- labels.sort_unstable_by(|left, right| left.name.cmp(&right.name));
- let samples = (0..args.samples_per_series)
- .map(|sample_idx| Sample {
- value: deterministic_value(series_idx, sample_idx),
- timestamp: args.start_unix_millis + (sample_idx as i64 * args.step_millis),
- })
- .collect();
- TimeSeries {
- labels,
- samples,
- ..Default::default()
- }
-}
-
-fn label(name: &str, value: &str) -> Label {
- Label {
- name: name.to_string(),
- value: value.to_string(),
- }
-}
-
-fn deterministic_value(series_idx: u64, sample_idx: u64) -> f64 {
- ((series_idx % 97) as f64) + (sample_idx as f64 * 0.125)
-}
diff --git a/src/cmd/src/bin/query_perf_fixture.rs b/src/cmd/src/bin/query_perf_fixture.rs
index dfc3a664a03..d0e185038fa 100644
--- a/src/cmd/src/bin/query_perf_fixture.rs
+++ b/src/cmd/src/bin/query_perf_fixture.rs
@@ -14,656 +14,10 @@
#![allow(clippy::print_stderr, clippy::print_stdout)]
-//! Generic direct-readable-SST fixture generator for query performance labs.
-//!
-//! This is a bounded MVP: it reads one table/one region case TOML, builds
-//! synthetic region metadata, writes real Mito readable SST parquet files, and
-//! emits a manifest checkpoint plus validation metadata. The first case uses
-//! `sst_format = "flat"`; primary-key output is also accepted for early lab use
-//! because the writer can convert the same flat input batch to primary-key SSTs.
-//!
-//! TODO(query-perf): add multi-region generation and seed-manifest/catalog DB
-//! integration so the generated fixture can be mounted directly by a full
-//! GreptimeDB open/query path without manual metadata wiring.
-
-use std::collections::HashMap;
-use std::fs;
-use std::io::{BufWriter, Write};
-use std::num::{NonZeroU64, NonZeroUsize};
-use std::path::{Path, PathBuf};
-use std::sync::Arc;
-
-use api::v1::{OpType, SemanticType};
-use async_trait::async_trait;
-use clap::Parser;
-use datatypes::arrow::array::{
- ArrayRef, BinaryDictionaryBuilder, Float64Array, RecordBatch, StringDictionaryBuilder,
- TimestampMillisecondArray, TimestampNanosecondArray, UInt8Array, UInt64Array,
-};
-use datatypes::arrow::datatypes::UInt32Type;
-use datatypes::prelude::ConcreteDataType;
-use datatypes::schema::{ColumnSchema, SkippingIndexOptions};
-use mito_codec::row_converter::{DensePrimaryKeyCodec, PrimaryKeyCodecExt, SortField};
-use mito2::access_layer::{FilePathProvider, Metrics, WriteType};
-use mito2::config::IndexConfig;
-use mito2::manifest::action::{RegionCheckpoint, RegionManifest, RemovedFilesRecord};
-use mito2::read::FlatSource;
-use mito2::sst::file::{FileMeta, RegionFileId};
-use mito2::sst::index::{Indexer, IndexerBuilder};
-use mito2::sst::parquet::writer::ParquetWriter;
-use mito2::sst::parquet::{SstInfo, WriteOptions};
-use mito2::sst::{
- DEFAULT_WRITE_BUFFER_SIZE, FlatSchemaOptions, FormatType, to_flat_sst_arrow_schema,
-};
-use object_store::ObjectStore;
-use object_store::services::Fs as FsBuilder;
-use serde::Deserialize;
-use store_api::codec::PrimaryKeyEncoding;
-use store_api::metadata::{ColumnMetadata, RegionMetadata, RegionMetadataRef};
-use store_api::path_utils::region_name;
-use store_api::region_request::PathType;
-use store_api::storage::{FileId, RegionId};
-
-#[derive(Parser, Debug)]
-#[command(name = "query_perf_fixture")]
-#[command(about = "Generate direct-readable SST fixtures for query performance cases")]
-struct Args {
- /// TOML case file, for example tests/perf/query_cases/.../case.toml.
- #[arg(long, value_name = "PATH")]
- case: PathBuf,
-
- /// Output directory (creates object-store/, manifest/, files.jsonl, summary.json).
- #[arg(long, value_name = "DIR")]
- out_dir: PathBuf,
-
- /// Region ID to synthesize. Defaults to table id 1024, region 0.
- #[arg(long, default_value = "4398046511104")]
- region_id: u64,
-
- /// Table directory relative to object-store root. Defaults to data/{database}/{table}/.
- #[arg(long, value_name = "DIR")]
- table_dir: Option,
-
- /// Table name to generate when the case contains multiple [[tables]].
- #[arg(long, value_name = "NAME")]
- table: Option,
-
- /// Manifest/checkpoint version.
- #[arg(long, default_value = "1000000")]
- checkpoint_version: u64,
-
- /// Safety flag when sst_count exceeds 1000.
- #[arg(long)]
- allow_large: bool,
-
- /// Print plan only.
- #[arg(long)]
- dry_run: bool,
-}
-
-#[derive(Debug, Deserialize)]
-struct CaseFile {
- scenario: Scenario,
-}
-
-#[derive(Debug, Deserialize)]
-#[serde(tag = "kind")]
-enum Scenario {
- #[serde(rename = "direct_readable_sst")]
- DirectReadableSst(DirectReadableSstScenario),
-}
-
-#[derive(Debug, Deserialize)]
-struct DirectReadableSstScenario {
- #[serde(default)]
- seed: Option,
- tables: Vec,
- layout: LayoutConfig,
-}
-
-impl Scenario {
- fn kind(&self) -> &'static str {
- match self {
- Scenario::DirectReadableSst(_) => "direct_readable_sst",
- }
- }
-
- fn direct_readable_sst(&self) -> &DirectReadableSstScenario {
- match self {
- Scenario::DirectReadableSst(scenario) => scenario,
- }
- }
-}
-
-#[derive(Debug, Deserialize)]
-struct TableConfig {
- database: String,
- name: String,
- engine: String,
- #[serde(default)]
- append_mode: Option,
- #[serde(default)]
- sst_format: Option,
- primary_key: Vec,
- time_index: String,
- columns: Vec,
-}
-
-#[derive(Debug, Deserialize)]
-struct ColumnConfig {
- name: String,
- #[serde(rename = "type")]
- ty: String,
- semantic: String,
- distribution: Option,
-}
-
-#[derive(Debug, Deserialize)]
-#[serde(tag = "kind")]
-enum Distribution {
- #[serde(rename = "cardinality")]
- Cardinality {
- values: NonZeroUsize,
- prefix: String,
- },
- #[serde(rename = "deterministic_wave")]
- DeterministicWave { min: f64, max: f64 },
-}
-
-#[derive(Debug, Deserialize)]
-struct LayoutConfig {
- regions: usize,
- sst_count: usize,
- rows_per_sst: usize,
- row_group_size: usize,
- series_count: NonZeroUsize,
- start_unix_nanos: i64,
- step_nanos: i64,
- time_range_layout: String,
- series_layout: String,
-}
-
-struct NoopIndexBuilder;
-
-#[async_trait]
-impl IndexerBuilder for NoopIndexBuilder {
- async fn build(&self, _file_id: FileId, _index_version: u64) -> Indexer {
- Indexer::default()
- }
-}
-
-#[derive(Clone)]
-struct FixedPathProvider {
- table_dir: String,
-}
-
-impl FilePathProvider for FixedPathProvider {
- fn build_index_file_path(&self, file_id: RegionFileId) -> String {
- mito2::sst::location::index_file_path_legacy(&self.table_dir, file_id, PathType::Bare)
- }
- fn build_index_file_path_with_version(
- &self,
- index_id: mito2::sst::file::RegionIndexId,
- ) -> String {
- mito2::sst::location::index_file_path(&self.table_dir, index_id, PathType::Bare)
- }
- fn build_sst_file_path(&self, file_id: RegionFileId) -> String {
- mito2::sst::location::sst_file_path(&self.table_dir, file_id, PathType::Bare)
- }
-}
-
-fn semantic_type(s: &str) -> SemanticType {
- match s.to_ascii_lowercase().as_str() {
- "tag" => SemanticType::Tag,
- "field" => SemanticType::Field,
- "timestamp" => SemanticType::Timestamp,
- other => panic!("unsupported semantic {other}"),
- }
-}
-
-fn concrete_type(ty: &str) -> ConcreteDataType {
- match ty.to_ascii_uppercase().as_str() {
- "STRING" => ConcreteDataType::string_datatype(),
- "DOUBLE" => ConcreteDataType::float64_datatype(),
- "UINT64" => ConcreteDataType::uint64_datatype(),
- "TIMESTAMP(9)" => ConcreteDataType::timestamp_nanosecond_datatype(),
- "TIMESTAMP(3)" => ConcreteDataType::timestamp_millisecond_datatype(),
- other => panic!("unsupported column type {other}"),
- }
-}
-
-fn build_region_metadata(table: &TableConfig, region_id: RegionId) -> RegionMetadata {
- let mut builder = store_api::metadata::RegionMetadataBuilder::new(region_id);
- for (idx, col) in table.columns.iter().enumerate() {
- let mut schema = ColumnSchema::new(
- &col.name,
- concrete_type(&col.ty),
- col.semantic != "timestamp",
- );
- if col.semantic == "tag" {
- schema = schema.with_inverted_index(true);
- }
- if col.semantic == "tag" || col.semantic == "field" {
- schema = schema
- .with_skipping_options(SkippingIndexOptions {
- granularity: 1,
- ..Default::default()
- })
- .expect("valid skipping index options for query perf fixture");
- }
- if col.name == table.time_index {
- schema = schema.with_time_index(true);
- }
- builder.push_column_metadata(ColumnMetadata {
- column_schema: schema,
- semantic_type: semantic_type(&col.semantic),
- column_id: idx as u32,
- });
- }
- let pk_ids = table
- .primary_key
- .iter()
- .map(|name| {
- table
- .columns
- .iter()
- .position(|c| c.name == *name)
- .unwrap_or_else(|| panic!("primary key column {name} not found")) as u32
- })
- .collect();
- builder.primary_key(pk_ids);
- builder.primary_key_encoding(PrimaryKeyEncoding::Dense);
- builder
- .build()
- .expect("region metadata should be valid for fixture table config")
-}
-
-fn encode_dense_primary_key(table: &TableConfig, values: &HashMap) -> Vec {
- let fields = table
- .primary_key
- .iter()
- .enumerate()
- .map(|(idx, _)| {
- (
- idx as u32,
- SortField::new(ConcreteDataType::string_datatype()),
- )
- })
- .collect();
- let converter = DensePrimaryKeyCodec::with_fields(fields);
- converter
- .encode(
- table
- .primary_key
- .iter()
- .map(|name| datatypes::value::ValueRef::String(values[name].as_str())),
- )
- .expect("dense primary key encoding should match fixture primary key fields")
-}
-
-fn tag_value(col: &ColumnConfig, series: usize) -> String {
- match col
- .distribution
- .as_ref()
- .expect("tag distribution is required")
- {
- Distribution::Cardinality { values, prefix } => {
- format!("{}{}", prefix, series % values.get())
- }
- _ => panic!("tag column {} requires cardinality distribution", col.name),
- }
-}
-
-fn series_for_row(layout: &LayoutConfig, sst_idx: usize, base_row: usize, row: usize) -> usize {
- match layout.series_layout.as_str() {
- "round_robin" | "timestamp_major" => (base_row + row) % layout.series_count.get(),
- "per_sst" => sst_idx % layout.series_count.get(),
- other => panic!("unsupported series_layout {other}"),
- }
-}
-
-fn timestamp_for_row(layout: &LayoutConfig, base_row: usize, row: usize) -> i64 {
- let logical_row = base_row + row;
- let timestamp_step = if layout.series_layout == "timestamp_major" {
- logical_row / layout.series_count.get()
- } else {
- logical_row
- };
-
- layout.start_unix_nanos + (timestamp_step as i64 * layout.step_nanos)
-}
-
-fn wave_value(min: f64, max: f64, row: usize) -> f64 {
- let span = max - min;
- let phase = (row % 1024) as f64 / 1023.0;
- min + span * (0.5 - 0.5 * (std::f64::consts::TAU * phase).cos())
-}
-
-fn generate_record_batch(
- table: &TableConfig,
- metadata: &RegionMetadataRef,
- layout: &LayoutConfig,
- sst_idx: usize,
- sequence: u64,
-) -> RecordBatch {
- let flat_schema = to_flat_sst_arrow_schema(metadata, &FlatSchemaOptions::default());
- let rows = layout.rows_per_sst;
- let mut columns = Vec::new();
- let base_row = sst_idx * rows;
-
- for col in &table.columns {
- match (col.semantic.as_str(), col.ty.to_ascii_uppercase().as_str()) {
- ("tag", "STRING") => {
- let mut b = StringDictionaryBuilder::::new();
- for row in 0..rows {
- let series = series_for_row(layout, sst_idx, base_row, row);
- let value = tag_value(col, series);
- b.append_value(value);
- }
- columns.push(Arc::new(b.finish()) as ArrayRef);
- }
- ("field", "DOUBLE") => {
- let (min, max) = match col.distribution.as_ref() {
- Some(Distribution::DeterministicWave { min, max }) => (*min, *max),
- _ => (0.0, 1.0),
- };
- columns.push(Arc::new(Float64Array::from(
- (0..rows)
- .map(|r| wave_value(min, max, base_row + r))
- .collect::>(),
- )) as ArrayRef);
- }
- ("field", "UINT64") => columns.push(Arc::new(UInt64Array::from(
- (0..rows).map(|r| (base_row + r) as u64).collect::>(),
- )) as ArrayRef),
- ("timestamp", "TIMESTAMP(9)") => columns.push(Arc::new(TimestampNanosecondArray::from(
- (0..rows)
- .map(|r| timestamp_for_row(layout, base_row, r))
- .collect::>(),
- )) as ArrayRef),
- ("timestamp", "TIMESTAMP(3)") => {
- columns.push(Arc::new(TimestampMillisecondArray::from(
- (0..rows)
- .map(|r| timestamp_for_row(layout, base_row, r) / 1_000_000)
- .collect::>(),
- )) as ArrayRef)
- }
- other => panic!("unsupported column combination {other:?}"),
- }
- }
-
- let mut pk_builder = BinaryDictionaryBuilder::::new();
- for row in 0..rows {
- let series = series_for_row(layout, sst_idx, base_row, row);
- let values = table
- .columns
- .iter()
- .filter(|c| c.semantic == "tag")
- .map(|c| (c.name.clone(), tag_value(c, series)))
- .collect();
- pk_builder
- .append(encode_dense_primary_key(table, &values))
- .expect("append generated dense primary key to Arrow dictionary builder");
- }
- columns.push(Arc::new(pk_builder.finish()));
- columns.push(Arc::new(UInt64Array::from_value(sequence, rows)));
- columns.push(Arc::new(UInt8Array::from_value(OpType::Put as u8, rows)));
- RecordBatch::try_new(flat_schema, columns)
- .expect("generated fixture columns should match flat SST Arrow schema")
-}
-
-fn file_meta_from_sst_info(
- info: &SstInfo,
- region_id: RegionId,
- file_id: FileId,
- sequence: u64,
-) -> FileMeta {
- FileMeta {
- region_id,
- file_id,
- time_range: info.time_range,
- level: 0,
- file_size: info.file_size,
- max_row_group_uncompressed_size: info.max_row_group_uncompressed_size,
- available_indexes: Default::default(),
- indexes: Default::default(),
- index_file_size: 0,
- index_version: 0,
- num_rows: info.num_rows as u64,
- num_row_groups: info.num_row_groups,
- sequence: NonZeroU64::new(sequence),
- partition_expr: None,
- num_series: info.num_series,
- primary_key_min: None,
- primary_key_max: None,
- }
-}
-
-fn deterministic_file_id(seed: u64, index: usize) -> FileId {
- let seed_hi = ((seed >> 16) & 0xffff) as u16;
- let seed_lo = (seed & 0xffff) as u16;
- FileId::parse_str(&format!(
- "00000000-0000-{seed_hi:04x}-{seed_lo:04x}-{index:012x}"
- ))
- .expect("deterministic file id must be a valid UUID")
-}
-
-fn remap_sst_file(
- object_store_dir: &Path,
- table_dir: &str,
- region_id: RegionId,
- old_file_id: FileId,
- new_file_id: FileId,
-) {
- if old_file_id == new_file_id {
- return;
- }
- let old_path = object_store_dir.join(mito2::sst::location::sst_file_path(
- table_dir,
- RegionFileId::new(region_id, old_file_id),
- PathType::Bare,
- ));
- let new_path = object_store_dir.join(mito2::sst::location::sst_file_path(
- table_dir,
- RegionFileId::new(region_id, new_file_id),
- PathType::Bare,
- ));
- if let Some(parent) = new_path.parent() {
- fs::create_dir_all(parent).expect("failed to create remapped SST parent directory");
- }
- fs::rename(&old_path, &new_path).unwrap_or_else(|err| {
- panic!(
- "failed to remap SST file {} -> {}: {err}",
- old_path.display(),
- new_path.display()
- )
- });
-}
-
-fn case_name_from_path(path: &Path) -> String {
- path.parent()
- .and_then(Path::file_name)
- .and_then(|name| name.to_str())
- .unwrap_or("query_perf_case")
- .to_string()
-}
+#[path = "query_perf_fixture/mod.rs"]
+mod query_perf_fixture;
#[tokio::main]
async fn main() {
- let args = Args::parse();
- let case_text = fs::read_to_string(&args.case).expect("failed to read query perf case TOML");
- let case: CaseFile = toml::from_str(&case_text).expect("failed to parse query perf case TOML");
- let case_name = case_name_from_path(&args.case);
- let scenario = case.scenario.direct_readable_sst();
- if scenario.tables.is_empty() || scenario.layout.regions != 1 {
- panic!("fixture generator supports one or more tables and exactly one region per table");
- }
- if scenario.layout.time_range_layout != "non_overlapping_per_sst" {
- panic!("MVP supports time_range_layout=non_overlapping_per_sst");
- }
- if scenario.layout.series_layout == "timestamp_major"
- && !scenario
- .layout
- .rows_per_sst
- .is_multiple_of(scenario.layout.series_count.get())
- {
- panic!(
- "series_layout=timestamp_major requires rows_per_sst to be divisible by series_count"
- );
- }
- if scenario.layout.sst_count > 1000 && !args.allow_large {
- panic!("sst_count exceeds 1000; pass --allow-large");
- }
- let seed = scenario.seed.unwrap_or(0);
- let table_index = match args.table.as_deref() {
- Some(name) => scenario
- .tables
- .iter()
- .position(|table| table.name == name)
- .unwrap_or_else(|| panic!("--table {name} was not found in case {case_name}")),
- None if scenario.tables.len() == 1 => 0,
- None => panic!(
- "case {} contains {} tables; pass --table to choose one",
- case_name,
- scenario.tables.len()
- ),
- };
- let table = &scenario.tables[table_index];
- if table.engine != "mito" {
- panic!("MVP supports engine=mito");
- }
- let region_id = RegionId::from(args.region_id);
- let table_dir = args
- .table_dir
- .unwrap_or_else(|| format!("data/{}/{}/", table.database, table.name));
- if Path::new(&table_dir).is_absolute() {
- panic!("--table-dir must be relative");
- }
- if table_dir.trim_end_matches('/').rsplit('/').next()
- == Some(region_name(region_id.table_id(), region_id.region_sequence()).as_str())
- {
- panic!("--table-dir must be table-level directory");
- }
- let region_dir =
- mito2::sst::location::region_dir_from_table_dir(&table_dir, region_id, PathType::Bare);
- let format = match table.sst_format.as_deref().unwrap_or("flat") {
- "flat" => FormatType::Flat,
- "primary_key" | "primary-key" => FormatType::PrimaryKey,
- other => panic!("unsupported sst_format {other}"),
- };
- println!(
- "query_perf_fixture case={} scenario={} table={}.{} ssts={} rows_per_sst={} format={format:?}",
- case_name,
- case.scenario.kind(),
- table.database,
- table.name,
- scenario.layout.sst_count,
- scenario.layout.rows_per_sst
- );
- println!(
- "out_dir={} table_dir={} region_dir={}",
- args.out_dir.display(),
- table_dir,
- region_dir
- );
- if args.dry_run {
- return;
- }
-
- let obj_store_dir = args.out_dir.join("object-store");
- let manifest_dir = args.out_dir.join("manifest");
- fs::create_dir_all(&obj_store_dir).expect("failed to create fixture object-store directory");
- fs::create_dir_all(&manifest_dir).expect("failed to create fixture manifest directory");
- let ostorage = ObjectStore::new(FsBuilder::default().root(&obj_store_dir.to_string_lossy()))
- .expect("failed to create filesystem object store for fixture output")
- .finish();
- let metadata: RegionMetadataRef = Arc::new(build_region_metadata(table, region_id));
- let mut files = HashMap::with_capacity(scenario.layout.sst_count);
- let mut next_file_index = 1;
- for i in 0..scenario.layout.sst_count {
- let sequence = 1000 + i as u64;
- let batch = generate_record_batch(table, &metadata, &scenario.layout, i, sequence);
- let source =
- FlatSource::new_iter(batch.schema(), Box::new(vec![batch].into_iter().map(Ok)));
- let mut metrics = Metrics::new(WriteType::Flush);
- let mut writer = ParquetWriter::new_with_object_store(
- ostorage.clone(),
- metadata.clone(),
- IndexConfig::default(),
- NoopIndexBuilder,
- FixedPathProvider {
- table_dir: table_dir.clone(),
- },
- &mut metrics,
- )
- .await;
- let opts = WriteOptions {
- write_buffer_size: DEFAULT_WRITE_BUFFER_SIZE,
- row_group_size: scenario.layout.row_group_size,
- max_file_size: None,
- };
- let infos = match format {
- FormatType::Flat => writer.write_all_flat(source, Some(sequence), &opts).await,
- FormatType::PrimaryKey => {
- writer
- .write_all_flat_as_primary_key(source, Some(sequence), &opts)
- .await
- }
- }
- .expect("failed to write fixture SST through Mito parquet writer");
- for info in infos {
- let file_id = deterministic_file_id(
- seed.wrapping_add((table_index as u64) << 16),
- next_file_index,
- );
- next_file_index += 1;
- remap_sst_file(&obj_store_dir, &table_dir, region_id, info.file_id, file_id);
- files.insert(
- file_id,
- file_meta_from_sst_info(&info, region_id, file_id, sequence),
- );
- }
- }
- let overall_seq = files
- .values()
- .filter_map(|m| m.sequence)
- .map(|s| s.get())
- .max()
- .unwrap_or(0);
- let manifest = RegionManifest {
- metadata,
- files,
- removed_files: RemovedFilesRecord::default(),
- flushed_entry_id: overall_seq,
- flushed_sequence: overall_seq,
- committed_sequence: Some(overall_seq),
- manifest_version: args.checkpoint_version,
- truncated_entry_id: None,
- compaction_time_window: None,
- sst_format: format,
- append_mode: table.append_mode,
- };
- let checkpoint = RegionCheckpoint {
- last_version: args.checkpoint_version,
- compacted_actions: manifest.files.len(),
- checkpoint: Some(manifest.clone()),
- };
- let checkpoint_bytes = checkpoint
- .encode()
- .expect("failed to encode fixture region checkpoint");
- let checkpoint_path = manifest_dir.join(format!("{:020}.checkpoint", args.checkpoint_version));
- fs::write(&checkpoint_path, &checkpoint_bytes).expect("failed to write checkpoint file");
- fs::write(manifest_dir.join("_last_checkpoint"), serde_json::to_vec_pretty(&serde_json::json!({ "size": checkpoint_bytes.len(), "version": args.checkpoint_version, "checksum": null, "extend_metadata": {} })).expect("failed to serialize _last_checkpoint metadata")).expect("failed to write _last_checkpoint file");
- let files_jsonl_path = args.out_dir.join("files.jsonl");
- let mut jsonl = BufWriter::new(
- fs::File::create(&files_jsonl_path).expect("failed to create fixture files.jsonl"),
- );
- let mut entries: Vec<_> = manifest.files.iter().collect();
- entries.sort_by_key(|(id, _)| id.to_string());
- for (file_id, meta) in entries {
- writeln!(jsonl, "{}", serde_json::to_string(&serde_json::json!({ "file_id": file_id.to_string(), "region_id": meta.region_id.as_u64(), "object_path": mito2::sst::location::sst_file_path(&table_dir, RegionFileId::new(meta.region_id, *file_id), PathType::Bare), "time_range_start": meta.time_range.0.value(), "time_range_end": meta.time_range.1.value(), "num_rows": meta.num_rows, "num_row_groups": meta.num_row_groups, "file_size": meta.file_size, "num_series": meta.num_series, "sequence": meta.sequence.map(|s| s.get()) })).expect("failed to serialize fixture SST metadata JSONL entry")).expect("failed to write fixture SST metadata JSONL entry");
- }
- jsonl.flush().expect("failed to flush fixture files.jsonl");
- fs::write(args.out_dir.join("summary.json"), serde_json::to_vec_pretty(&serde_json::json!({ "case": case_name, "seed": seed, "table_index": table_index, "table": table.name, "database": table.database, "region_id": region_id.as_u64(), "table_dir": table_dir, "region_dir": region_dir, "sst_format": format!("{format:?}"), "sst_count": scenario.layout.sst_count, "rows_per_sst": scenario.layout.rows_per_sst, "row_group_size": scenario.layout.row_group_size, "total_rows": scenario.layout.sst_count * scenario.layout.rows_per_sst, "checkpoint_path": checkpoint_path, "files_jsonl_path": files_jsonl_path, "readback_validated": false, "metadata_source": "synthetic" })).expect("failed to serialize fixture summary")).expect("failed to write fixture summary.json");
- println!("Done. wrote {} SST file entries", manifest.files.len());
+ query_perf_fixture::run().await;
}
diff --git a/src/cmd/src/bin/query_perf_fixture/case.rs b/src/cmd/src/bin/query_perf_fixture/case.rs
new file mode 100644
index 00000000000..7dce735d7b9
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/case.rs
@@ -0,0 +1,470 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+use std::collections::HashMap;
+use std::num::NonZeroUsize;
+
+use clap::ValueEnum;
+use serde::{Deserialize, Serialize};
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct CaseFile {
+ pub(super) scenario: Scenario,
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+#[serde(tag = "kind")]
+pub(super) enum Scenario {
+ #[serde(rename = "direct_readable_sst")]
+ DirectReadableSst(DirectReadableSstScenario),
+ #[serde(rename = "prom_remote_write_then_query")]
+ PromRemoteWriteThenQuery(PromRemoteWriteThenQueryScenario),
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct DirectReadableSstScenario {
+ #[serde(default)]
+ pub(super) seed: Option,
+ pub(super) tables: Vec,
+ pub(super) layout: LayoutConfig,
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct PromRemoteWriteThenQueryScenario {
+ #[serde(default)]
+ pub(super) queries: Vec,
+ pub(super) remote_write: PromRemoteWritePlan,
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct PromRemoteWritePlan {
+ #[serde(default = "default_database")]
+ pub(super) database: String,
+ #[serde(alias = "metric_name")]
+ pub(super) metric: String,
+ #[serde(default = "default_physical_table")]
+ pub(super) physical_table: String,
+ #[serde(default = "default_series_count")]
+ pub(super) series_count: u64,
+ #[serde(default = "default_samples_per_series")]
+ pub(super) samples_per_series: u64,
+ #[serde(default = "default_start_unix_millis")]
+ pub(super) start_unix_millis: i64,
+ #[serde(default = "default_step_millis")]
+ pub(super) step_millis: i64,
+ #[serde(default = "default_chunk_series_count", alias = "batch_size")]
+ pub(super) chunk_series_count: u64,
+ #[serde(default = "default_timeout_seconds")]
+ pub(super) timeout_seconds: u64,
+ #[serde(default)]
+ pub(super) sample_chunk_size: Option,
+ #[serde(default = "default_flush_every_sample_chunks")]
+ pub(super) flush_every_sample_chunks: u64,
+ #[serde(default = "default_visibility_timeout_seconds")]
+ pub(super) visibility_timeout_seconds: u64,
+ #[serde(default)]
+ pub(super) prom_store: PromStoreConfig,
+ #[serde(default)]
+ pub(super) value: ValueConfig,
+ #[serde(default)]
+ pub(super) storage: Option,
+ #[serde(default)]
+ pub(super) read_bench: Option,
+}
+
+pub(super) fn default_database() -> String {
+ "public".to_string()
+}
+pub(super) fn default_physical_table() -> String {
+ "greptime_physical_table".to_string()
+}
+pub(super) fn default_series_count() -> u64 {
+ 8
+}
+pub(super) fn default_samples_per_series() -> u64 {
+ 30
+}
+pub(super) fn default_start_unix_millis() -> i64 {
+ 1_704_067_200_000
+}
+pub(super) fn default_step_millis() -> i64 {
+ 15_000
+}
+pub(super) fn default_chunk_series_count() -> u64 {
+ 8
+}
+pub(super) fn default_timeout_seconds() -> u64 {
+ 60
+}
+pub(super) fn default_flush_every_sample_chunks() -> u64 {
+ 1
+}
+pub(super) fn default_visibility_timeout_seconds() -> u64 {
+ 30
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct PromStoreConfig {
+ #[serde(default = "default_pending_rows_flush_interval")]
+ pub(super) pending_rows_flush_interval: String,
+ #[serde(default = "default_max_batch_rows")]
+ pub(super) max_batch_rows: u64,
+ #[serde(default = "default_max_concurrent_flushes")]
+ pub(super) max_concurrent_flushes: u64,
+ #[serde(default = "default_worker_channel_capacity")]
+ pub(super) worker_channel_capacity: u64,
+ #[serde(default = "default_max_inflight_requests")]
+ pub(super) max_inflight_requests: u64,
+}
+
+impl Default for PromStoreConfig {
+ fn default() -> Self {
+ Self {
+ pending_rows_flush_interval: default_pending_rows_flush_interval(),
+ max_batch_rows: default_max_batch_rows(),
+ max_concurrent_flushes: default_max_concurrent_flushes(),
+ worker_channel_capacity: default_worker_channel_capacity(),
+ max_inflight_requests: default_max_inflight_requests(),
+ }
+ }
+}
+
+pub(super) fn default_pending_rows_flush_interval() -> String {
+ "1s".to_string()
+}
+pub(super) fn default_max_batch_rows() -> u64 {
+ 100000
+}
+pub(super) fn default_max_concurrent_flushes() -> u64 {
+ 256
+}
+pub(super) fn default_worker_channel_capacity() -> u64 {
+ 65526
+}
+pub(super) fn default_max_inflight_requests() -> u64 {
+ 3000
+}
+
+#[derive(Debug, Clone, Copy, Deserialize, Serialize, ValueEnum, Eq, PartialEq)]
+#[serde(rename_all = "snake_case")]
+#[value(rename_all = "snake_case")]
+pub(super) enum ValuePattern {
+ Linear,
+ Constant,
+ Modulo,
+ Unique,
+ SeededRandom,
+ RunLength,
+ QuantizedSignal,
+ SignalWithSporadicStalls,
+ MixedSignalRepeated,
+}
+
+impl std::fmt::Display for ValuePattern {
+ fn fmt(&self, f: &mut std::fmt::Formatter<'_>) -> std::fmt::Result {
+ write!(
+ f,
+ "{}",
+ serde_json::to_value(self).unwrap().as_str().unwrap()
+ )
+ }
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct ValueConfig {
+ #[serde(default = "default_value_pattern")]
+ pub(super) pattern: ValuePattern,
+ #[serde(default)]
+ pub(super) base: f64,
+ #[serde(default = "default_value_step")]
+ pub(super) step: f64,
+ #[serde(default = "default_value_cardinality")]
+ pub(super) cardinality: u64,
+ #[serde(default)]
+ pub(super) seed: u64,
+ #[serde(default = "default_value_run_length")]
+ pub(super) run_length: u64,
+ #[serde(default = "default_value_stall_every")]
+ pub(super) stall_every: u64,
+ #[serde(default = "default_value_stall_length")]
+ pub(super) stall_length: u64,
+ #[serde(default = "default_value_mixed_every")]
+ pub(super) mixed_every: u64,
+}
+impl Default for ValueConfig {
+ fn default() -> Self {
+ Self {
+ pattern: default_value_pattern(),
+ base: 0.0,
+ step: default_value_step(),
+ cardinality: default_value_cardinality(),
+ seed: 0,
+ run_length: default_value_run_length(),
+ stall_every: default_value_stall_every(),
+ stall_length: default_value_stall_length(),
+ mixed_every: default_value_mixed_every(),
+ }
+ }
+}
+pub(super) fn default_value_pattern() -> ValuePattern {
+ ValuePattern::Linear
+}
+pub(super) fn default_value_step() -> f64 {
+ 0.125
+}
+pub(super) fn default_value_cardinality() -> u64 {
+ 97
+}
+pub(super) fn default_value_run_length() -> u64 {
+ 8
+}
+pub(super) fn default_value_stall_every() -> u64 {
+ 100
+}
+pub(super) fn default_value_stall_length() -> u64 {
+ 16
+}
+pub(super) fn default_value_mixed_every() -> u64 {
+ 5
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct StorageConfig {
+ #[serde(default = "default_true")]
+ pub(super) inspect: bool,
+ #[serde(default = "default_storage_column")]
+ pub(super) column: String,
+ #[serde(default)]
+ pub(super) root_suffix: Option,
+ #[serde(default)]
+ pub(super) include_metadata_files: bool,
+ #[serde(default = "default_min_files")]
+ pub(super) min_files: u64,
+ #[serde(default = "default_min_files")]
+ pub(super) min_files_with_column: u64,
+ #[serde(default)]
+ pub(super) require_encodings: Vec,
+ #[serde(default)]
+ pub(super) forbid_encodings: Vec,
+ #[serde(default)]
+ pub(super) max_total_file_size_bytes: Option,
+ #[serde(default)]
+ pub(super) max_column_compressed_size_bytes: Option,
+ #[serde(default)]
+ pub(super) max_column_uncompressed_size_bytes: Option,
+ #[serde(default)]
+ pub(super) max_candidate_total_file_size_regression_pct: Option,
+ #[serde(default)]
+ pub(super) max_candidate_column_compressed_size_regression_pct: Option,
+ #[serde(default)]
+ pub(super) max_candidate_column_uncompressed_size_regression_pct: Option,
+ #[serde(skip_deserializing, default)]
+ pub(super) planned_thresholds: Vec,
+}
+
+#[derive(Debug, Serialize)]
+pub(super) struct StorageThresholdPlan {
+ pub(super) threshold: String,
+ pub(super) status: String,
+ pub(super) value: serde_json::Value,
+}
+
+impl StorageConfig {
+ pub(super) fn populate_planned_thresholds(&mut self) {
+ let mut planned = Vec::new();
+ planned.push(StorageThresholdPlan::new("min_files", self.min_files));
+ planned.push(StorageThresholdPlan::new(
+ "min_files_with_column",
+ self.min_files_with_column,
+ ));
+ if !self.require_encodings.is_empty() {
+ planned.push(StorageThresholdPlan::new(
+ "require_encodings",
+ &self.require_encodings,
+ ));
+ }
+ if !self.forbid_encodings.is_empty() {
+ planned.push(StorageThresholdPlan::new(
+ "forbid_encodings",
+ &self.forbid_encodings,
+ ));
+ }
+ macro_rules! push_optional {
+ ($name:literal, $value:expr) => {
+ if let Some(value) = $value {
+ planned.push(StorageThresholdPlan::new($name, value));
+ }
+ };
+ }
+ push_optional!("max_total_file_size_bytes", self.max_total_file_size_bytes);
+ push_optional!(
+ "max_column_compressed_size_bytes",
+ self.max_column_compressed_size_bytes
+ );
+ push_optional!(
+ "max_column_uncompressed_size_bytes",
+ self.max_column_uncompressed_size_bytes
+ );
+ push_optional!(
+ "max_candidate_total_file_size_regression_pct",
+ self.max_candidate_total_file_size_regression_pct
+ );
+ push_optional!(
+ "max_candidate_column_compressed_size_regression_pct",
+ self.max_candidate_column_compressed_size_regression_pct
+ );
+ push_optional!(
+ "max_candidate_column_uncompressed_size_regression_pct",
+ self.max_candidate_column_uncompressed_size_regression_pct
+ );
+ self.planned_thresholds = planned;
+ }
+}
+
+impl StorageThresholdPlan {
+ fn new(threshold: &str, value: T) -> Self {
+ Self {
+ threshold: threshold.to_string(),
+ status: "planned".to_string(),
+ value: serde_json::to_value(value).expect("storage threshold value must serialize"),
+ }
+ }
+}
+pub(super) fn default_true() -> bool {
+ true
+}
+pub(super) fn default_storage_column() -> String {
+ "greptime_value".to_string()
+}
+pub(super) fn default_min_files() -> u64 {
+ 1
+}
+
+#[derive(Debug, Deserialize, Serialize, Clone)]
+pub(super) struct ReadBenchConfig {
+ #[serde(default = "default_true")]
+ pub(super) enabled: bool,
+ #[serde(default = "default_true")]
+ pub(super) parquetbench: bool,
+ #[serde(default = "default_true")]
+ pub(super) scanbench: bool,
+ #[serde(default = "default_iterations")]
+ pub(super) iterations: u64,
+ #[serde(default)]
+ pub(super) projection: Vec,
+ #[serde(default = "default_parquet_reader")]
+ pub(super) parquet_reader: String,
+ #[serde(default = "default_scan_scanner")]
+ pub(super) scan_scanner: String,
+ #[serde(default = "default_parallelism")]
+ pub(super) parallelism: u64,
+ #[serde(default)]
+ pub(super) max_files: Option,
+ #[serde(flatten)]
+ pub(super) thresholds: HashMap,
+}
+
+impl Default for ReadBenchConfig {
+ fn default() -> Self {
+ Self {
+ enabled: true,
+ parquetbench: true,
+ scanbench: true,
+ iterations: default_iterations(),
+ projection: vec![],
+ parquet_reader: default_parquet_reader(),
+ scan_scanner: default_scan_scanner(),
+ parallelism: default_parallelism(),
+ max_files: None,
+ thresholds: HashMap::new(),
+ }
+ }
+}
+
+pub(super) fn default_iterations() -> u64 {
+ 7
+}
+pub(super) fn default_parquet_reader() -> String {
+ "direct".to_string()
+}
+pub(super) fn default_scan_scanner() -> String {
+ "seq".to_string()
+}
+pub(super) fn default_parallelism() -> u64 {
+ 1
+}
+
+impl Scenario {
+ pub(super) fn kind(&self) -> &'static str {
+ match self {
+ Scenario::DirectReadableSst(_) => "direct_readable_sst",
+ Scenario::PromRemoteWriteThenQuery(_) => "prom_remote_write_then_query",
+ }
+ }
+
+ pub(super) fn direct_readable_sst(&self) -> &DirectReadableSstScenario {
+ match self {
+ Scenario::DirectReadableSst(scenario) => scenario,
+ _ => panic!("scenario is not direct_readable_sst"),
+ }
+ }
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct TableConfig {
+ pub(super) database: String,
+ pub(super) name: String,
+ pub(super) engine: String,
+ #[serde(default)]
+ pub(super) append_mode: Option,
+ #[serde(default)]
+ pub(super) sst_format: Option,
+ pub(super) primary_key: Vec,
+ pub(super) time_index: String,
+ pub(super) columns: Vec,
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct ColumnConfig {
+ pub(super) name: String,
+ #[serde(rename = "type")]
+ pub(super) ty: String,
+ pub(super) semantic: String,
+ pub(super) distribution: Option,
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+#[serde(tag = "kind")]
+pub(super) enum Distribution {
+ #[serde(rename = "cardinality")]
+ Cardinality {
+ values: NonZeroUsize,
+ prefix: String,
+ },
+ #[serde(rename = "deterministic_wave")]
+ DeterministicWave { min: f64, max: f64 },
+}
+
+#[derive(Debug, Deserialize, Serialize)]
+pub(super) struct LayoutConfig {
+ pub(super) regions: usize,
+ pub(super) sst_count: usize,
+ pub(super) rows_per_sst: usize,
+ pub(super) row_group_size: usize,
+ pub(super) series_count: NonZeroUsize,
+ pub(super) start_unix_nanos: i64,
+ pub(super) step_nanos: i64,
+ pub(super) time_range_layout: String,
+ pub(super) series_layout: String,
+}
diff --git a/src/cmd/src/bin/query_perf_fixture/direct_sst.rs b/src/cmd/src/bin/query_perf_fixture/direct_sst.rs
new file mode 100644
index 00000000000..0f2e3b34876
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/direct_sst.rs
@@ -0,0 +1,529 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+use std::collections::HashMap;
+use std::fs::{self};
+use std::io::{BufWriter, Write};
+use std::num::NonZeroU64;
+use std::path::Path;
+use std::sync::Arc;
+
+use api::v1::{OpType, SemanticType};
+use async_trait::async_trait;
+use datatypes::arrow::array::{
+ ArrayRef, BinaryDictionaryBuilder, Float64Array, RecordBatch, StringDictionaryBuilder,
+ TimestampMillisecondArray, TimestampNanosecondArray, UInt8Array, UInt64Array,
+};
+use datatypes::arrow::datatypes::UInt32Type;
+use datatypes::prelude::ConcreteDataType;
+use datatypes::schema::{ColumnSchema, SkippingIndexOptions};
+use mito_codec::row_converter::{DensePrimaryKeyCodec, PrimaryKeyCodecExt, SortField};
+use mito2::access_layer::{FilePathProvider, Metrics, WriteType};
+use mito2::config::IndexConfig;
+use mito2::manifest::action::{RegionCheckpoint, RegionManifest, RemovedFilesRecord};
+use mito2::read::FlatSource;
+use mito2::sst::file::{FileMeta, RegionFileId};
+use mito2::sst::index::{Indexer, IndexerBuilder};
+use mito2::sst::parquet::writer::ParquetWriter;
+use mito2::sst::parquet::{SstInfo, WriteOptions};
+use mito2::sst::{
+ DEFAULT_WRITE_BUFFER_SIZE, FlatSchemaOptions, FormatType, to_flat_sst_arrow_schema,
+};
+use object_store::ObjectStore;
+use object_store::services::Fs as FsBuilder;
+use store_api::codec::PrimaryKeyEncoding;
+use store_api::metadata::{ColumnMetadata, RegionMetadata, RegionMetadataRef};
+use store_api::path_utils::region_name;
+use store_api::region_request::PathType;
+use store_api::storage::{FileId, RegionId};
+
+use crate::query_perf_fixture::DirectArgs;
+use crate::query_perf_fixture::case::*;
+use crate::query_perf_fixture::util::case_name_from_path;
+
+struct NoopIndexBuilder;
+
+#[async_trait]
+impl IndexerBuilder for NoopIndexBuilder {
+ async fn build(&self, _file_id: FileId, _index_version: u64) -> Indexer {
+ Indexer::default()
+ }
+}
+
+#[derive(Clone)]
+struct FixedPathProvider {
+ table_dir: String,
+}
+
+impl FilePathProvider for FixedPathProvider {
+ fn build_index_file_path(&self, file_id: RegionFileId) -> String {
+ mito2::sst::location::index_file_path_legacy(&self.table_dir, file_id, PathType::Bare)
+ }
+ fn build_index_file_path_with_version(
+ &self,
+ index_id: mito2::sst::file::RegionIndexId,
+ ) -> String {
+ mito2::sst::location::index_file_path(&self.table_dir, index_id, PathType::Bare)
+ }
+ fn build_sst_file_path(&self, file_id: RegionFileId) -> String {
+ mito2::sst::location::sst_file_path(&self.table_dir, file_id, PathType::Bare)
+ }
+}
+
+fn semantic_type(s: &str) -> SemanticType {
+ match s.to_ascii_lowercase().as_str() {
+ "tag" => SemanticType::Tag,
+ "field" => SemanticType::Field,
+ "timestamp" => SemanticType::Timestamp,
+ other => panic!("unsupported semantic {other}"),
+ }
+}
+
+fn concrete_type(ty: &str) -> ConcreteDataType {
+ match ty.to_ascii_uppercase().as_str() {
+ "STRING" => ConcreteDataType::string_datatype(),
+ "DOUBLE" => ConcreteDataType::float64_datatype(),
+ "UINT64" => ConcreteDataType::uint64_datatype(),
+ "TIMESTAMP(9)" => ConcreteDataType::timestamp_nanosecond_datatype(),
+ "TIMESTAMP(3)" => ConcreteDataType::timestamp_millisecond_datatype(),
+ other => panic!("unsupported column type {other}"),
+ }
+}
+
+fn build_region_metadata(table: &TableConfig, region_id: RegionId) -> RegionMetadata {
+ let mut builder = store_api::metadata::RegionMetadataBuilder::new(region_id);
+ for (idx, col) in table.columns.iter().enumerate() {
+ let mut schema = ColumnSchema::new(
+ &col.name,
+ concrete_type(&col.ty),
+ col.semantic != "timestamp",
+ );
+ if col.semantic == "tag" {
+ schema = schema.with_inverted_index(true);
+ }
+ if col.semantic == "tag" || col.semantic == "field" {
+ schema = schema
+ .with_skipping_options(SkippingIndexOptions {
+ granularity: 1,
+ ..Default::default()
+ })
+ .expect("valid skipping index options for query perf fixture");
+ }
+ if col.name == table.time_index {
+ schema = schema.with_time_index(true);
+ }
+ builder.push_column_metadata(ColumnMetadata {
+ column_schema: schema,
+ semantic_type: semantic_type(&col.semantic),
+ column_id: idx as u32,
+ });
+ }
+ let pk_ids = table
+ .primary_key
+ .iter()
+ .map(|name| {
+ table
+ .columns
+ .iter()
+ .position(|c| c.name == *name)
+ .unwrap_or_else(|| panic!("primary key column {name} not found")) as u32
+ })
+ .collect();
+ builder.primary_key(pk_ids);
+ builder.primary_key_encoding(PrimaryKeyEncoding::Dense);
+ builder
+ .build()
+ .expect("region metadata should be valid for fixture table config")
+}
+
+fn encode_dense_primary_key(table: &TableConfig, values: &HashMap) -> Vec {
+ let fields = table
+ .primary_key
+ .iter()
+ .enumerate()
+ .map(|(idx, _)| {
+ (
+ idx as u32,
+ SortField::new(ConcreteDataType::string_datatype()),
+ )
+ })
+ .collect();
+ let converter = DensePrimaryKeyCodec::with_fields(fields);
+ converter
+ .encode(
+ table
+ .primary_key
+ .iter()
+ .map(|name| datatypes::value::ValueRef::String(values[name].as_str())),
+ )
+ .expect("dense primary key encoding should match fixture primary key fields")
+}
+
+fn tag_value(col: &ColumnConfig, series: usize) -> String {
+ match col
+ .distribution
+ .as_ref()
+ .expect("tag distribution is required")
+ {
+ Distribution::Cardinality { values, prefix } => {
+ format!("{}{}", prefix, series % values.get())
+ }
+ _ => panic!("tag column {} requires cardinality distribution", col.name),
+ }
+}
+
+fn series_for_row(layout: &LayoutConfig, sst_idx: usize, base_row: usize, row: usize) -> usize {
+ match layout.series_layout.as_str() {
+ "round_robin" | "timestamp_major" => (base_row + row) % layout.series_count.get(),
+ "per_sst" => sst_idx % layout.series_count.get(),
+ other => panic!("unsupported series_layout {other}"),
+ }
+}
+
+fn timestamp_for_row(layout: &LayoutConfig, base_row: usize, row: usize) -> i64 {
+ let logical_row = base_row + row;
+ let timestamp_step = if layout.series_layout == "timestamp_major" {
+ logical_row / layout.series_count.get()
+ } else {
+ logical_row
+ };
+
+ layout.start_unix_nanos + (timestamp_step as i64 * layout.step_nanos)
+}
+
+fn wave_value(min: f64, max: f64, row: usize) -> f64 {
+ let span = max - min;
+ let phase = (row % 1024) as f64 / 1023.0;
+ min + span * (0.5 - 0.5 * (std::f64::consts::TAU * phase).cos())
+}
+
+fn generate_record_batch(
+ table: &TableConfig,
+ metadata: &RegionMetadataRef,
+ layout: &LayoutConfig,
+ sst_idx: usize,
+ sequence: u64,
+) -> RecordBatch {
+ let flat_schema = to_flat_sst_arrow_schema(metadata, &FlatSchemaOptions::default());
+ let rows = layout.rows_per_sst;
+ let mut columns = Vec::new();
+ let base_row = sst_idx * rows;
+
+ for col in &table.columns {
+ match (col.semantic.as_str(), col.ty.to_ascii_uppercase().as_str()) {
+ ("tag", "STRING") => {
+ let mut b = StringDictionaryBuilder::::new();
+ for row in 0..rows {
+ let series = series_for_row(layout, sst_idx, base_row, row);
+ let value = tag_value(col, series);
+ b.append_value(value);
+ }
+ columns.push(Arc::new(b.finish()) as ArrayRef);
+ }
+ ("field", "DOUBLE") => {
+ let (min, max) = match col.distribution.as_ref() {
+ Some(Distribution::DeterministicWave { min, max }) => (*min, *max),
+ _ => (0.0, 1.0),
+ };
+ columns.push(Arc::new(Float64Array::from(
+ (0..rows)
+ .map(|r| wave_value(min, max, base_row + r))
+ .collect::>(),
+ )) as ArrayRef);
+ }
+ ("field", "UINT64") => columns.push(Arc::new(UInt64Array::from(
+ (0..rows).map(|r| (base_row + r) as u64).collect::>(),
+ )) as ArrayRef),
+ ("timestamp", "TIMESTAMP(9)") => columns.push(Arc::new(TimestampNanosecondArray::from(
+ (0..rows)
+ .map(|r| timestamp_for_row(layout, base_row, r))
+ .collect::>(),
+ )) as ArrayRef),
+ ("timestamp", "TIMESTAMP(3)") => {
+ columns.push(Arc::new(TimestampMillisecondArray::from(
+ (0..rows)
+ .map(|r| timestamp_for_row(layout, base_row, r) / 1_000_000)
+ .collect::>(),
+ )) as ArrayRef)
+ }
+ other => panic!("unsupported column combination {other:?}"),
+ }
+ }
+
+ let mut pk_builder = BinaryDictionaryBuilder::::new();
+ for row in 0..rows {
+ let series = series_for_row(layout, sst_idx, base_row, row);
+ let values = table
+ .columns
+ .iter()
+ .filter(|c| c.semantic == "tag")
+ .map(|c| (c.name.clone(), tag_value(c, series)))
+ .collect();
+ pk_builder
+ .append(encode_dense_primary_key(table, &values))
+ .expect("append generated dense primary key to Arrow dictionary builder");
+ }
+ columns.push(Arc::new(pk_builder.finish()));
+ columns.push(Arc::new(UInt64Array::from_value(sequence, rows)));
+ columns.push(Arc::new(UInt8Array::from_value(OpType::Put as u8, rows)));
+ RecordBatch::try_new(flat_schema, columns)
+ .expect("generated fixture columns should match flat SST Arrow schema")
+}
+
+fn file_meta_from_sst_info(
+ info: &SstInfo,
+ region_id: RegionId,
+ file_id: FileId,
+ sequence: u64,
+) -> FileMeta {
+ FileMeta {
+ region_id,
+ file_id,
+ time_range: info.time_range,
+ level: 0,
+ file_size: info.file_size,
+ max_row_group_uncompressed_size: info.max_row_group_uncompressed_size,
+ available_indexes: Default::default(),
+ indexes: Default::default(),
+ index_file_size: 0,
+ index_version: 0,
+ num_rows: info.num_rows as u64,
+ num_row_groups: info.num_row_groups,
+ sequence: NonZeroU64::new(sequence),
+ partition_expr: None,
+ num_series: info.num_series,
+ primary_key_min: None,
+ primary_key_max: None,
+ }
+}
+
+fn deterministic_file_id(seed: u64, index: usize) -> FileId {
+ let seed_hi = ((seed >> 16) & 0xffff) as u16;
+ let seed_lo = (seed & 0xffff) as u16;
+ FileId::parse_str(&format!(
+ "00000000-0000-{seed_hi:04x}-{seed_lo:04x}-{index:012x}"
+ ))
+ .expect("deterministic file id must be a valid UUID")
+}
+
+fn remap_sst_file(
+ object_store_dir: &Path,
+ table_dir: &str,
+ region_id: RegionId,
+ old_file_id: FileId,
+ new_file_id: FileId,
+) {
+ if old_file_id == new_file_id {
+ return;
+ }
+ let old_path = object_store_dir.join(mito2::sst::location::sst_file_path(
+ table_dir,
+ RegionFileId::new(region_id, old_file_id),
+ PathType::Bare,
+ ));
+ let new_path = object_store_dir.join(mito2::sst::location::sst_file_path(
+ table_dir,
+ RegionFileId::new(region_id, new_file_id),
+ PathType::Bare,
+ ));
+ if let Some(parent) = new_path.parent() {
+ fs::create_dir_all(parent).expect("failed to create remapped SST parent directory");
+ }
+ fs::rename(&old_path, &new_path).unwrap_or_else(|err| {
+ panic!(
+ "failed to remap SST file {} -> {}: {err}",
+ old_path.display(),
+ new_path.display()
+ )
+ });
+}
+pub(super) async fn run_direct_sst(args: DirectArgs) {
+ let case_path = args.case.as_ref().expect("--case is required");
+ let out_dir = args.out_dir.as_ref().expect("--out-dir is required");
+ let case_text = fs::read_to_string(case_path).expect("failed to read query perf case TOML");
+ let case: CaseFile = toml::from_str(&case_text).expect("failed to parse query perf case TOML");
+ let case_name = case_name_from_path(case_path);
+ let scenario = case.scenario.direct_readable_sst();
+ if scenario.tables.is_empty() || scenario.layout.regions != 1 {
+ panic!("fixture generator supports one or more tables and exactly one region per table");
+ }
+ if scenario.layout.time_range_layout != "non_overlapping_per_sst" {
+ panic!("MVP supports time_range_layout=non_overlapping_per_sst");
+ }
+ if scenario.layout.series_layout == "timestamp_major"
+ && !scenario
+ .layout
+ .rows_per_sst
+ .is_multiple_of(scenario.layout.series_count.get())
+ {
+ panic!(
+ "series_layout=timestamp_major requires rows_per_sst to be divisible by series_count"
+ );
+ }
+ if scenario.layout.sst_count > 1000 && !args.allow_large {
+ panic!("sst_count exceeds 1000; pass --allow-large");
+ }
+ let seed = scenario.seed.unwrap_or(0);
+ let table_index = match args.table.as_deref() {
+ Some(name) => scenario
+ .tables
+ .iter()
+ .position(|table| table.name == name)
+ .unwrap_or_else(|| panic!("--table {name} was not found in case {case_name}")),
+ None if scenario.tables.len() == 1 => 0,
+ None => panic!(
+ "case {} contains {} tables; pass --table to choose one",
+ case_name,
+ scenario.tables.len()
+ ),
+ };
+ let table = &scenario.tables[table_index];
+ if table.engine != "mito" {
+ panic!("MVP supports engine=mito");
+ }
+ let region_id = RegionId::from(args.region_id);
+ let table_dir = args
+ .table_dir
+ .unwrap_or_else(|| format!("data/{}/{}/", table.database, table.name));
+ if Path::new(&table_dir).is_absolute() {
+ panic!("--table-dir must be relative");
+ }
+ if table_dir.trim_end_matches('/').rsplit('/').next()
+ == Some(region_name(region_id.table_id(), region_id.region_sequence()).as_str())
+ {
+ panic!("--table-dir must be table-level directory");
+ }
+ let region_dir =
+ mito2::sst::location::region_dir_from_table_dir(&table_dir, region_id, PathType::Bare);
+ let format = match table.sst_format.as_deref().unwrap_or("flat") {
+ "flat" => FormatType::Flat,
+ "primary_key" | "primary-key" => FormatType::PrimaryKey,
+ other => panic!("unsupported sst_format {other}"),
+ };
+ println!(
+ "query_perf_fixture case={} scenario={} table={}.{} ssts={} rows_per_sst={} format={format:?}",
+ case_name,
+ case.scenario.kind(),
+ table.database,
+ table.name,
+ scenario.layout.sst_count,
+ scenario.layout.rows_per_sst
+ );
+ println!(
+ "out_dir={} table_dir={} region_dir={}",
+ out_dir.display(),
+ table_dir,
+ region_dir
+ );
+ if args.dry_run {
+ return;
+ }
+
+ let obj_store_dir = out_dir.join("object-store");
+ let manifest_dir = out_dir.join("manifest");
+ fs::create_dir_all(&obj_store_dir).expect("failed to create fixture object-store directory");
+ fs::create_dir_all(&manifest_dir).expect("failed to create fixture manifest directory");
+ let ostorage = ObjectStore::new(FsBuilder::default().root(&obj_store_dir.to_string_lossy()))
+ .expect("failed to create filesystem object store for fixture output")
+ .finish();
+ let metadata: RegionMetadataRef = Arc::new(build_region_metadata(table, region_id));
+ let mut files = HashMap::with_capacity(scenario.layout.sst_count);
+ let mut next_file_index = 1;
+ for i in 0..scenario.layout.sst_count {
+ let sequence = 1000 + i as u64;
+ let batch = generate_record_batch(table, &metadata, &scenario.layout, i, sequence);
+ let source =
+ FlatSource::new_iter(batch.schema(), Box::new(vec![batch].into_iter().map(Ok)));
+ let mut metrics = Metrics::new(WriteType::Flush);
+ let mut writer = ParquetWriter::new_with_object_store(
+ ostorage.clone(),
+ metadata.clone(),
+ IndexConfig::default(),
+ NoopIndexBuilder,
+ FixedPathProvider {
+ table_dir: table_dir.clone(),
+ },
+ &mut metrics,
+ )
+ .await;
+ let opts = WriteOptions {
+ write_buffer_size: DEFAULT_WRITE_BUFFER_SIZE,
+ row_group_size: scenario.layout.row_group_size,
+ max_file_size: None,
+ };
+ let infos = match format {
+ FormatType::Flat => writer.write_all_flat(source, Some(sequence), &opts).await,
+ FormatType::PrimaryKey => {
+ writer
+ .write_all_flat_as_primary_key(source, Some(sequence), &opts)
+ .await
+ }
+ }
+ .expect("failed to write fixture SST through Mito parquet writer");
+ for info in infos {
+ let file_id = deterministic_file_id(
+ seed.wrapping_add((table_index as u64) << 16),
+ next_file_index,
+ );
+ next_file_index += 1;
+ remap_sst_file(&obj_store_dir, &table_dir, region_id, info.file_id, file_id);
+ files.insert(
+ file_id,
+ file_meta_from_sst_info(&info, region_id, file_id, sequence),
+ );
+ }
+ }
+ let overall_seq = files
+ .values()
+ .filter_map(|m| m.sequence)
+ .map(|s| s.get())
+ .max()
+ .unwrap_or(0);
+ let manifest = RegionManifest {
+ metadata,
+ files,
+ removed_files: RemovedFilesRecord::default(),
+ flushed_entry_id: overall_seq,
+ flushed_sequence: overall_seq,
+ committed_sequence: Some(overall_seq),
+ manifest_version: args.checkpoint_version,
+ truncated_entry_id: None,
+ compaction_time_window: None,
+ sst_format: format,
+ append_mode: table.append_mode,
+ };
+ let checkpoint = RegionCheckpoint {
+ last_version: args.checkpoint_version,
+ compacted_actions: manifest.files.len(),
+ checkpoint: Some(manifest.clone()),
+ };
+ let checkpoint_bytes = checkpoint
+ .encode()
+ .expect("failed to encode fixture region checkpoint");
+ let checkpoint_path = manifest_dir.join(format!("{:020}.checkpoint", args.checkpoint_version));
+ fs::write(&checkpoint_path, &checkpoint_bytes).expect("failed to write checkpoint file");
+ fs::write(manifest_dir.join("_last_checkpoint"), serde_json::to_vec_pretty(&serde_json::json!({ "size": checkpoint_bytes.len(), "version": args.checkpoint_version, "checksum": null, "extend_metadata": {} })).expect("failed to serialize _last_checkpoint metadata")).expect("failed to write _last_checkpoint file");
+ let files_jsonl_path = out_dir.join("files.jsonl");
+ let mut jsonl = BufWriter::new(
+ fs::File::create(&files_jsonl_path).expect("failed to create fixture files.jsonl"),
+ );
+ let mut entries: Vec<_> = manifest.files.iter().collect();
+ entries.sort_by_key(|(id, _)| id.to_string());
+ for (file_id, meta) in entries {
+ writeln!(jsonl, "{}", serde_json::to_string(&serde_json::json!({ "file_id": file_id.to_string(), "region_id": meta.region_id.as_u64(), "object_path": mito2::sst::location::sst_file_path(&table_dir, RegionFileId::new(meta.region_id, *file_id), PathType::Bare), "time_range_start": meta.time_range.0.value(), "time_range_end": meta.time_range.1.value(), "num_rows": meta.num_rows, "num_row_groups": meta.num_row_groups, "file_size": meta.file_size, "num_series": meta.num_series, "sequence": meta.sequence.map(|s| s.get()) })).expect("failed to serialize fixture SST metadata JSONL entry")).expect("failed to write fixture SST metadata JSONL entry");
+ }
+ jsonl.flush().expect("failed to flush fixture files.jsonl");
+ fs::write(out_dir.join("summary.json"), serde_json::to_vec_pretty(&serde_json::json!({ "case": case_name, "seed": seed, "table_index": table_index, "table": table.name, "database": table.database, "region_id": region_id.as_u64(), "table_dir": table_dir, "region_dir": region_dir, "sst_format": format!("{format:?}"), "sst_count": scenario.layout.sst_count, "rows_per_sst": scenario.layout.rows_per_sst, "row_group_size": scenario.layout.row_group_size, "total_rows": scenario.layout.sst_count * scenario.layout.rows_per_sst, "checkpoint_path": checkpoint_path, "files_jsonl_path": files_jsonl_path, "readback_validated": false, "metadata_source": "synthetic" })).expect("failed to serialize fixture summary")).expect("failed to write fixture summary.json");
+ println!("Done. wrote {} SST file entries", manifest.files.len());
+}
diff --git a/src/cmd/src/bin/query_perf_fixture/inspect_footer.rs b/src/cmd/src/bin/query_perf_fixture/inspect_footer.rs
new file mode 100644
index 00000000000..a52005c4e30
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/inspect_footer.rs
@@ -0,0 +1,181 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+use std::collections::BTreeSet;
+use std::fs::{self, File};
+use std::path::{Path, PathBuf};
+
+use clap::Args as ClapArgs;
+use parquet::file::reader::{FileReader, SerializedFileReader};
+use serde::Serialize;
+
+#[derive(Debug, ClapArgs)]
+pub(super) struct InspectFooterArgs {
+ #[arg(long)]
+ root: PathBuf,
+ #[arg(long, default_value = "greptime_value")]
+ column: String,
+ #[arg(long)]
+ include_metadata_files: bool,
+}
+
+#[derive(Debug, Serialize)]
+struct FooterReport {
+ root: String,
+ summary: FooterSummary,
+ files: Vec,
+}
+#[derive(Debug, Default, Serialize)]
+struct FooterSummary {
+ column: String,
+ file_count: usize,
+ files_with_column: usize,
+ total_file_size: u64,
+ total_rows: i64,
+ column_compressed_size: i64,
+ column_uncompressed_size: i64,
+ unique_encodings: Vec,
+}
+#[derive(Debug, Serialize)]
+struct FooterFileReport {
+ path: String,
+ relative_path: String,
+ file_size: u64,
+ num_rows: i64,
+ num_row_groups: usize,
+ columns: Vec,
+}
+#[derive(Debug, Serialize)]
+struct FooterColumnChunkReport {
+ row_group_index: usize,
+ column_index: usize,
+ column_path: String,
+ encodings: Vec,
+ compression: String,
+ compressed_size: i64,
+ uncompressed_size: i64,
+ num_values: i64,
+}
+
+pub(super) fn run_inspect_footer(
+ args: InspectFooterArgs,
+) -> Result<(), Box> {
+ let files = collect_parquet_files(&args.root, args.include_metadata_files)?;
+ let reports = files
+ .iter()
+ .map(|p| inspect_file(&args.root, p, &args.column))
+ .collect::, _>>()?;
+ println!(
+ "{}",
+ serde_json::to_string_pretty(&FooterReport {
+ root: args.root.display().to_string(),
+ summary: summarize_footer(&args.column, &reports),
+ files: reports
+ })?
+ );
+ Ok(())
+}
+fn collect_parquet_files(
+ root: &Path,
+ include_metadata_files: bool,
+) -> Result, Box> {
+ let mut files = Vec::new();
+ collect_parquet_files_inner(root, root, include_metadata_files, &mut files)?;
+ files.sort();
+ Ok(files)
+}
+fn collect_parquet_files_inner(
+ root: &Path,
+ path: &Path,
+ include_metadata_files: bool,
+ files: &mut Vec,
+) -> Result<(), Box> {
+ if path.is_dir() {
+ for entry in fs::read_dir(path)? {
+ collect_parquet_files_inner(root, &entry?.path(), include_metadata_files, files)?;
+ }
+ } else if path.extension().is_some_and(|ext| ext == "parquet")
+ && (include_metadata_files
+ || !path
+ .strip_prefix(root)
+ .unwrap_or(path)
+ .components()
+ .any(|c| c.as_os_str() == "metadata"))
+ {
+ files.push(path.to_path_buf());
+ }
+ Ok(())
+}
+fn inspect_file(
+ root: &Path,
+ path: &Path,
+ column: &str,
+) -> Result> {
+ let file_size = fs::metadata(path)?.len();
+ let reader = SerializedFileReader::new(File::open(path)?)?;
+ let metadata = reader.metadata().file_metadata();
+ let row_groups = reader.metadata().row_groups();
+ let mut columns = Vec::new();
+ for (row_group_index, rg) in row_groups.iter().enumerate() {
+ for (column_index, chunk) in rg.columns().iter().enumerate() {
+ let column_path = chunk.column_path().string();
+ if column_path == column {
+ columns.push(FooterColumnChunkReport {
+ row_group_index,
+ column_index,
+ column_path,
+ encodings: chunk.encodings().map(|e| format!("{e:?}")).collect(),
+ compression: format!("{:?}", chunk.compression()),
+ compressed_size: chunk.compressed_size(),
+ uncompressed_size: chunk.uncompressed_size(),
+ num_values: chunk.num_values(),
+ });
+ }
+ }
+ }
+ Ok(FooterFileReport {
+ path: path.display().to_string(),
+ relative_path: path
+ .strip_prefix(root)
+ .unwrap_or(path)
+ .display()
+ .to_string(),
+ file_size,
+ num_rows: metadata.num_rows(),
+ num_row_groups: row_groups.len(),
+ columns,
+ })
+}
+fn summarize_footer(column: &str, files: &[FooterFileReport]) -> FooterSummary {
+ let mut encodings = BTreeSet::new();
+ let mut s = FooterSummary {
+ column: column.to_string(),
+ file_count: files.len(),
+ ..Default::default()
+ };
+ for file in files {
+ s.total_file_size += file.file_size;
+ s.total_rows += file.num_rows;
+ if !file.columns.is_empty() {
+ s.files_with_column += 1;
+ }
+ for c in &file.columns {
+ s.column_compressed_size += c.compressed_size;
+ s.column_uncompressed_size += c.uncompressed_size;
+ encodings.extend(c.encodings.iter().cloned());
+ }
+ }
+ s.unique_encodings = encodings.into_iter().collect();
+ s
+}
diff --git a/src/cmd/src/bin/query_perf_fixture/mod.rs b/src/cmd/src/bin/query_perf_fixture/mod.rs
new file mode 100644
index 00000000000..00cef327c78
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/mod.rs
@@ -0,0 +1,133 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+mod case;
+mod direct_sst;
+mod inspect_footer;
+mod prom_remote_write;
+mod util;
+
+use std::fs;
+use std::path::PathBuf;
+
+use case::*;
+use clap::{Args as ClapArgs, Parser, Subcommand};
+use direct_sst::run_direct_sst;
+use inspect_footer::{InspectFooterArgs, run_inspect_footer};
+use prom_remote_write::{PromRemoteWriteArgs, run_prom_remote_write};
+use serde_json::json;
+
+#[derive(Parser, Debug)]
+#[command(name = "query_perf_fixture")]
+#[command(about = "Query performance fixture helper")]
+struct Args {
+ #[command(subcommand)]
+ command: Option,
+
+ #[command(flatten)]
+ legacy: DirectArgs,
+}
+
+#[derive(Subcommand, Debug)]
+enum Command {
+ DirectSst(DirectArgs),
+ PromRemoteWrite(PromRemoteWriteArgs),
+ InspectFooter(InspectFooterArgs),
+ Plan(PlanArgs),
+}
+
+#[derive(ClapArgs, Debug, Clone)]
+struct DirectArgs {
+ /// TOML case file, for example tests/perf/query_cases/.../case.toml.
+ #[arg(long, value_name = "PATH")]
+ case: Option,
+
+ /// Output directory (creates object-store/, manifest/, files.jsonl, summary.json).
+ #[arg(long, value_name = "DIR")]
+ out_dir: Option,
+
+ /// Region ID to synthesize. Defaults to table id 1024, region 0.
+ #[arg(long, default_value = "4398046511104")]
+ region_id: u64,
+
+ /// Table directory relative to object-store root. Defaults to data/{database}/{table}/.
+ #[arg(long, value_name = "DIR")]
+ table_dir: Option,
+
+ /// Table name to generate when the case contains multiple [[tables]].
+ #[arg(long, value_name = "NAME")]
+ table: Option,
+
+ /// Manifest/checkpoint version.
+ #[arg(long, default_value = "1000000")]
+ checkpoint_version: u64,
+
+ /// Safety flag when sst_count exceeds 1000.
+ #[arg(long)]
+ allow_large: bool,
+
+ /// Print plan only.
+ #[arg(long)]
+ dry_run: bool,
+}
+
+#[derive(ClapArgs, Debug)]
+struct PlanArgs {
+ #[arg(long, value_name = "PATH")]
+ case: PathBuf,
+}
+
+pub async fn run() {
+ let args = Args::parse();
+ match args.command {
+ Some(Command::DirectSst(direct)) => run_direct_sst(direct).await,
+ Some(Command::PromRemoteWrite(rw)) => run_prom_remote_write(rw)
+ .await
+ .expect("prom remote write failed"),
+ Some(Command::InspectFooter(inspect)) => {
+ run_inspect_footer(inspect).expect("inspect footer failed")
+ }
+ Some(Command::Plan(plan)) => run_plan(plan).expect("plan failed"),
+ None => run_direct_sst(args.legacy).await,
+ }
+}
+
+fn run_plan(args: PlanArgs) -> Result<(), Box> {
+ let case_text = fs::read_to_string(&args.case)?;
+ let mut case: CaseFile = toml::from_str(&case_text)?;
+ if let Scenario::PromRemoteWriteThenQuery(s) = &mut case.scenario
+ && let Some(storage) = &mut s.remote_write.storage
+ {
+ storage.populate_planned_thresholds();
+ if storage.inspect {
+ let mut rb = s.remote_write.read_bench.clone().unwrap_or_default();
+ if rb.enabled && rb.projection.is_empty() {
+ rb.projection = vec![storage.column.clone()];
+ }
+ s.remote_write.read_bench = Some(rb);
+ } else if s
+ .remote_write
+ .read_bench
+ .as_ref()
+ .is_some_and(|rb| rb.enabled)
+ {
+ return Err("scenario.remote_write.read_bench requires scenario.remote_write.storage.inspect = true".into());
+ }
+ }
+ println!(
+ "{}",
+ serde_json::to_string_pretty(&json!({"schema_version": 1, "scenario": case.scenario}))?
+ );
+ Ok(())
+}
diff --git a/src/cmd/src/bin/query_perf_fixture/prom_remote_write.rs b/src/cmd/src/bin/query_perf_fixture/prom_remote_write.rs
new file mode 100644
index 00000000000..1f36b0c2d23
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/prom_remote_write.rs
@@ -0,0 +1,333 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+use clap::Args as ClapArgs;
+use prost::Message;
+use serde_json::json;
+use servers::prom_store::snappy_compress;
+
+use crate::query_perf_fixture::case::ValuePattern;
+
+#[derive(Debug, ClapArgs)]
+pub(super) struct PromRemoteWriteArgs {
+ #[arg(long, default_value = "http://127.0.0.1:4000/v1/prometheus/write")]
+ endpoint: String,
+ #[arg(long, default_value = "public")]
+ database: String,
+ #[arg(long)]
+ metric: String,
+ #[arg(long, default_value = "greptime_physical_table")]
+ physical_table: String,
+ #[arg(long, default_value_t = 8)]
+ series_count: u64,
+ #[arg(long, default_value_t = 30)]
+ samples_per_series: u64,
+ #[arg(long, default_value_t = 1_704_067_200_000)]
+ start_unix_millis: i64,
+ #[arg(long, default_value_t = 15_000)]
+ step_millis: i64,
+ #[arg(long, alias = "batch-size", default_value_t = 8)]
+ chunk_series_count: u64,
+ #[arg(long, default_value_t = 60)]
+ timeout_seconds: u64,
+ #[arg(long, default_value_t = ValuePattern::Linear)]
+ value_pattern: ValuePattern,
+ #[arg(long, default_value_t = 0.0)]
+ value_base: f64,
+ #[arg(long, default_value_t = 0.125)]
+ value_step: f64,
+ #[arg(long, default_value_t = 97)]
+ value_cardinality: u64,
+ #[arg(long, default_value_t = 0)]
+ value_seed: u64,
+ #[arg(long, default_value_t = 8)]
+ value_run_length: u64,
+ #[arg(long, default_value_t = 100)]
+ value_stall_every: u64,
+ #[arg(long, default_value_t = 16)]
+ value_stall_length: u64,
+ #[arg(long, default_value_t = 5)]
+ value_mixed_every: u64,
+ #[arg(long, default_value_t = 0)]
+ value_sample_offset: u64,
+ #[arg(long)]
+ value_total_samples_per_series: Option,
+}
+
+pub(super) async fn run_prom_remote_write(
+ args: PromRemoteWriteArgs,
+) -> Result<(), Box> {
+ use api::prom_store::remote::WriteRequest;
+ let started = std::time::Instant::now();
+ let client = reqwest::Client::builder()
+ .timeout(std::time::Duration::from_secs(args.timeout_seconds))
+ .build()?;
+ let mut batches = 0_u64;
+ let mut rows = 0_u64;
+ let mut http_statuses = Vec::new();
+ for first in (0..args.series_count).step_by(args.chunk_series_count.max(1) as usize) {
+ let last = (first + args.chunk_series_count.max(1)).min(args.series_count);
+ let timeseries = (first..last)
+ .map(|series_idx| make_prom_series(&args, series_idx))
+ .collect::>();
+ rows += timeseries
+ .iter()
+ .map(|ts| ts.samples.len() as u64)
+ .sum::();
+ let body = snappy_compress(
+ &WriteRequest {
+ timeseries,
+ ..Default::default()
+ }
+ .encode_to_vec(),
+ )?;
+ let response = client
+ .post(&args.endpoint)
+ .header("Content-Encoding", "snappy")
+ .body(body)
+ .send()
+ .await?;
+ let status = response.status();
+ http_statuses.push(status.as_u16());
+ if !status.is_success() {
+ return Err(format!(
+ "remote-write failed with status {status}: {}",
+ response.text().await.unwrap_or_default()
+ )
+ .into());
+ }
+ batches += 1;
+ }
+ println!(
+ "{}",
+ json!({"status":"ok","endpoint":args.endpoint,"database":args.database,"metric":args.metric,"physical_table":args.physical_table,"series_count":args.series_count,"samples_per_series":args.samples_per_series,"rows":rows,"samples_written":rows,"batches":batches,"elapsed_seconds":started.elapsed().as_secs_f64(),"http_statuses":http_statuses,"value":{"pattern":args.value_pattern.to_string(),"base":args.value_base,"step":args.value_step,"cardinality":args.value_cardinality,"seed":args.value_seed,"run_length":args.value_run_length,"stall_every":args.value_stall_every,"stall_length":args.value_stall_length,"mixed_every":args.value_mixed_every,"sample_offset":args.value_sample_offset,"total_samples_per_series":args.value_total_samples_per_series.unwrap_or(args.samples_per_series)}})
+ );
+ Ok(())
+}
+
+fn make_prom_series(
+ args: &PromRemoteWriteArgs,
+ series_idx: u64,
+) -> api::prom_store::remote::TimeSeries {
+ let mut labels = vec![
+ prom_label("__name__", &args.metric),
+ prom_label("x_greptime_database", &args.database),
+ prom_label("x_greptime_physical_table", &args.physical_table),
+ prom_label("host", &format!("host{:04}", series_idx % 1024)),
+ prom_label("instance", &format!("instance{:06}", series_idx)),
+ ];
+ labels.sort_unstable_by(|l, r| l.name.cmp(&r.name));
+ let samples = (0..args.samples_per_series)
+ .map(|sample_idx| api::prom_store::remote::Sample {
+ value: deterministic_prom_value(args, series_idx, sample_idx),
+ timestamp: args.start_unix_millis + (sample_idx as i64 * args.step_millis),
+ })
+ .collect();
+ api::prom_store::remote::TimeSeries {
+ labels,
+ samples,
+ ..Default::default()
+ }
+}
+fn prom_label(name: &str, value: &str) -> api::prom_store::remote::Label {
+ api::prom_store::remote::Label {
+ name: name.to_string(),
+ value: value.to_string(),
+ }
+}
+fn deterministic_prom_value(args: &PromRemoteWriteArgs, series_idx: u64, sample_idx: u64) -> f64 {
+ let ordinal = series_idx
+ * args
+ .value_total_samples_per_series
+ .unwrap_or(args.samples_per_series)
+ + args.value_sample_offset
+ + sample_idx;
+ let local = args.value_sample_offset + sample_idx;
+ match args.value_pattern {
+ ValuePattern::Linear => {
+ args.value_base + (series_idx % 97) as f64 + local as f64 * args.value_step
+ }
+ ValuePattern::Constant => args.value_base,
+ ValuePattern::Modulo => {
+ args.value_base + (ordinal % args.value_cardinality.max(1)) as f64 * args.value_step
+ }
+ ValuePattern::Unique => args.value_base + ordinal as f64 * args.value_step,
+ ValuePattern::SeededRandom => {
+ args.value_base
+ + (splitmix64(ordinal ^ args.value_seed) % args.value_cardinality.max(1)) as f64
+ * args.value_step
+ }
+ ValuePattern::RunLength => {
+ args.value_base
+ + ((ordinal / args.value_run_length.max(1)) % args.value_cardinality.max(1)) as f64
+ * args.value_step
+ }
+ ValuePattern::QuantizedSignal => {
+ args.value_base
+ + (((series_idx % args.value_cardinality.max(1))
+ + (local / args.value_run_length.max(1)))
+ % args.value_cardinality.max(1)) as f64
+ * args.value_step
+ }
+ ValuePattern::SignalWithSporadicStalls => {
+ let every = args.value_stall_every.max(1);
+ let phase = local % every;
+ let effective = if phase < args.value_stall_length.min(every) {
+ local - phase
+ } else {
+ local
+ };
+ args.value_base + (series_idx % 97) as f64 + effective as f64 * args.value_step
+ }
+ ValuePattern::MixedSignalRepeated => {
+ if local.is_multiple_of(args.value_mixed_every.max(1)) {
+ args.value_base
+ } else {
+ args.value_base + (series_idx % 97) as f64 + local as f64 * args.value_step
+ }
+ }
+ }
+}
+fn splitmix64(mut value: u64) -> u64 {
+ value = value.wrapping_add(0x9e3779b97f4a7c15);
+ let mut mixed = value;
+ mixed = (mixed ^ (mixed >> 30)).wrapping_mul(0xbf58476d1ce4e5b9);
+ mixed = (mixed ^ (mixed >> 27)).wrapping_mul(0x94d049bb133111eb);
+ mixed ^ (mixed >> 31)
+}
+
+#[cfg(test)]
+mod tests {
+ use std::collections::HashSet;
+
+ use super::*;
+
+ fn args(pattern: ValuePattern) -> PromRemoteWriteArgs {
+ PromRemoteWriteArgs {
+ endpoint: "http://127.0.0.1:4000/v1/prometheus/write".to_string(),
+ database: "public".to_string(),
+ metric: "test_metric".to_string(),
+ physical_table: "greptime_physical_table".to_string(),
+ series_count: 2,
+ samples_per_series: 64,
+ start_unix_millis: 1_704_067_200_000,
+ step_millis: 60_000,
+ chunk_series_count: 2,
+ timeout_seconds: 60,
+ value_pattern: pattern,
+ value_base: 0.0,
+ value_step: 1.0,
+ value_cardinality: 1_024,
+ value_seed: 8_444,
+ value_run_length: 16,
+ value_stall_every: 100,
+ value_stall_length: 16,
+ value_mixed_every: 5,
+ value_sample_offset: 0,
+ value_total_samples_per_series: None,
+ }
+ }
+
+ #[test]
+ fn seeded_random_is_deterministic_in_range_and_highly_distinct() {
+ let mut args = args(ValuePattern::SeededRandom);
+ args.samples_per_series = 4_096;
+ args.value_cardinality = 29_491_200;
+
+ let values = (0..args.samples_per_series)
+ .map(|sample_idx| deterministic_prom_value(&args, 0, sample_idx))
+ .collect::>();
+ let repeated = (0..args.samples_per_series)
+ .map(|sample_idx| deterministic_prom_value(&args, 0, sample_idx))
+ .collect::>();
+
+ assert_eq!(values, repeated);
+ assert!(values.iter().all(|value| {
+ (args.value_base..=args.value_base + (args.value_cardinality - 1) as f64)
+ .contains(value)
+ }));
+ assert!(
+ values
+ .iter()
+ .map(|value| value.to_bits())
+ .collect::>()
+ .len()
+ > 4_000
+ );
+ }
+
+ #[test]
+ fn run_length_values_have_exact_sixteen_sample_runs() {
+ let args = args(ValuePattern::RunLength);
+
+ for sample_idx in 0..64 {
+ assert_eq!(
+ deterministic_prom_value(&args, 0, sample_idx),
+ (sample_idx / 16) as f64
+ );
+ }
+ }
+
+ #[test]
+ fn mixed_every_five_repeats_only_the_expected_positions() {
+ let mut args = args(ValuePattern::MixedSignalRepeated);
+ args.value_step = 0.125;
+
+ for sample_idx in 0..20 {
+ let expected = if sample_idx % 5 == 0 {
+ 0.0
+ } else {
+ 1.0 + sample_idx as f64 * 0.125
+ };
+ assert_eq!(deterministic_prom_value(&args, 1, sample_idx), expected);
+ }
+ }
+
+ #[test]
+ fn chunked_values_match_monolithic_values_through_offsets() {
+ let mut monolithic = args(ValuePattern::SeededRandom);
+ monolithic.samples_per_series = 14_400;
+ monolithic.value_total_samples_per_series = Some(14_400);
+
+ for series_idx in 0..2 {
+ let expected = (0..monolithic.samples_per_series)
+ .map(|sample_idx| deterministic_prom_value(&monolithic, series_idx, sample_idx))
+ .collect::>();
+ for chunk_idx in 0..10 {
+ let mut chunk = args(ValuePattern::SeededRandom);
+ chunk.samples_per_series = 1_440;
+ chunk.value_sample_offset = chunk_idx * 1_440;
+ chunk.value_total_samples_per_series = Some(14_400);
+ for sample_idx in 0..chunk.samples_per_series {
+ assert_eq!(
+ deterministic_prom_value(&chunk, series_idx, sample_idx),
+ expected[(chunk.value_sample_offset + sample_idx) as usize]
+ );
+ }
+ }
+ }
+ }
+
+ #[test]
+ fn values_continue_across_series_boundaries() {
+ let mut args = args(ValuePattern::Unique);
+ args.samples_per_series = 16;
+ args.value_total_samples_per_series = Some(16);
+ args.value_base = 1.0;
+ args.value_step = 0.5;
+
+ assert_eq!(deterministic_prom_value(&args, 0, 15), 8.5);
+ assert_eq!(deterministic_prom_value(&args, 1, 0), 9.0);
+ }
+}
diff --git a/src/cmd/src/bin/query_perf_fixture/util.rs b/src/cmd/src/bin/query_perf_fixture/util.rs
new file mode 100644
index 00000000000..2c86baa6839
--- /dev/null
+++ b/src/cmd/src/bin/query_perf_fixture/util.rs
@@ -0,0 +1,23 @@
+// Copyright 2023 Greptime Team
+//
+// Licensed under the Apache License, Version 2.0 (the "License");
+// you may not use this file except in compliance with the License.
+// You may obtain a copy of the License at
+//
+// http://www.apache.org/licenses/LICENSE-2.0
+//
+// Unless required by applicable law or agreed to in writing, software
+// distributed under the License is distributed on an "AS IS" BASIS,
+// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+// See the License for the specific language governing permissions and
+// limitations under the License.
+
+use std::path::Path;
+
+pub(super) fn case_name_from_path(path: &Path) -> String {
+ path.parent()
+ .and_then(Path::file_name)
+ .and_then(|name| name.to_str())
+ .unwrap_or("query_perf_case")
+ .to_string()
+}
diff --git a/src/cmd/src/datanode.rs b/src/cmd/src/datanode.rs
index 744624a5084..c33be6c6f33 100644
--- a/src/cmd/src/datanode.rs
+++ b/src/cmd/src/datanode.rs
@@ -15,11 +15,10 @@
pub mod builder;
#[allow(clippy::print_stdout)]
pub(crate) mod objbench;
-#[cfg(feature = "dev-tools")]
#[allow(clippy::print_stdout)]
-mod parquetbench;
+pub mod parquetbench;
#[allow(clippy::print_stdout)]
-mod scanbench;
+pub mod scanbench;
use std::path::Path;
use std::time::Duration;
@@ -40,7 +39,6 @@ use tracing_appender::non_blocking::WorkerGuard;
use crate::App;
use crate::datanode::builder::InstanceBuilder;
use crate::datanode::objbench::ObjbenchCommand;
-#[cfg(feature = "dev-tools")]
use crate::datanode::parquetbench::ParquetbenchCommand;
use crate::datanode::scanbench::ScanbenchCommand;
use crate::error::{
@@ -115,7 +113,6 @@ impl Command {
SubCommand::Start(cmd) => cmd.load_options(global_options),
// Bench commands are standalone utilities and don't need to load DatanodeOptions.
SubCommand::Objbench(_) | SubCommand::Scanbench(_) => Self::default_bench_options(),
- #[cfg(feature = "dev-tools")]
SubCommand::Parquetbench(_) => Self::default_bench_options(),
}
}
@@ -141,7 +138,6 @@ pub enum SubCommand {
/// Scan benchmark tool - benchmarks scanning a region directly from storage
Scanbench(ScanbenchCommand),
/// Benchmark scanning a single parquet SST.
- #[cfg(feature = "dev-tools")]
Parquetbench(ParquetbenchCommand),
}
@@ -160,7 +156,6 @@ impl SubCommand {
cmd.run().await?;
std::process::exit(0);
}
- #[cfg(feature = "dev-tools")]
SubCommand::Parquetbench(cmd) => {
cmd.run().await?;
std::process::exit(0);
diff --git a/src/mito2/src/engine/close_test.rs b/src/mito2/src/engine/close_test.rs
index 4c06583b0b8..0092634ec74 100644
--- a/src/mito2/src/engine/close_test.rs
+++ b/src/mito2/src/engine/close_test.rs
@@ -12,11 +12,17 @@
// See the License for the specific language governing permissions and
// limitations under the License.
+use std::sync::Arc;
+use std::sync::atomic::Ordering;
+
+use common_base::Plugins;
use store_api::region_engine::RegionEngine;
use store_api::region_request::{RegionCloseRequest, RegionRequest};
use store_api::storage::RegionId;
use crate::config::MitoConfig;
+use crate::engine::flush_test::MockRegionHook;
+use crate::engine::region_hook::RegionHookRef;
use crate::test_util::{CreateRequestBuilder, TestEnv};
#[tokio::test]
@@ -60,3 +66,40 @@ async fn test_engine_close_region_with_format(flat_format: bool) {
.await
.unwrap();
}
+
+#[tokio::test]
+async fn test_region_hook_on_close() {
+ common_telemetry::init_default_ut_logging();
+ let mut env = TestEnv::new().await;
+
+ let hook = Arc::new(MockRegionHook::new());
+ let plugins = Plugins::new();
+ plugins.insert(hook.clone() as RegionHookRef);
+
+ let engine = env
+ .create_engine_with_plugins(MitoConfig::default(), plugins)
+ .await;
+
+ let region_id = RegionId::new(1, 1);
+ let request = CreateRequestBuilder::new().build();
+ engine
+ .handle_request(region_id, RegionRequest::Create(request))
+ .await
+ .unwrap();
+
+ // Sanity: no lifecycle events before closing besides the create open.
+ assert_eq!(hook.opened_count.load(Ordering::Relaxed), 1);
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 0);
+ assert_eq!(hook.dropped_count.load(Ordering::Relaxed), 0);
+
+ engine
+ .handle_request(region_id, RegionRequest::Close(RegionCloseRequest {}))
+ .await
+ .unwrap();
+
+ // Closing fires on_region_closed exactly once.
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 1);
+ // Close must not be confused with drop.
+ assert_eq!(hook.dropped_count.load(Ordering::Relaxed), 0);
+ assert_eq!(hook.files_removed_count.load(Ordering::Relaxed), 0);
+}
diff --git a/src/mito2/src/engine/drop_test.rs b/src/mito2/src/engine/drop_test.rs
index a34a5d11727..90afd66ba32 100644
--- a/src/mito2/src/engine/drop_test.rs
+++ b/src/mito2/src/engine/drop_test.rs
@@ -13,9 +13,11 @@
// limitations under the License.
use std::sync::Arc;
+use std::sync::atomic::Ordering;
use std::time::Duration;
use api::v1::Rows;
+use common_base::Plugins;
use common_meta::key::SchemaMetadataManager;
use common_meta::kv_backend::KvBackendRef;
use object_store::util::join_path;
@@ -25,7 +27,9 @@ use store_api::storage::RegionId;
use crate::config::MitoConfig;
use crate::engine::MitoEngine;
+use crate::engine::flush_test::MockRegionHook;
use crate::engine::listener::DropListener;
+use crate::engine::region_hook::RegionHookRef;
use crate::test_util::{
CreateRequestBuilder, TestEnv, build_rows_for_key, flush_region, put_rows, rows_schema,
};
@@ -302,3 +306,75 @@ async fn test_engine_drop_region_for_custom_store_with_format(flat_format: bool)
.unwrap()
);
}
+
+#[tokio::test]
+async fn test_region_hook_on_drop() {
+ common_telemetry::init_default_ut_logging();
+ let mut env = TestEnv::with_prefix("drop_hook").await;
+
+ let hook = Arc::new(MockRegionHook::new());
+ let plugins = Plugins::new();
+ plugins.insert(hook.clone() as RegionHookRef);
+
+ let engine = env
+ .create_engine_with_plugins(MitoConfig::default(), plugins)
+ .await;
+
+ let region_id = RegionId::new(1, 1);
+ env.get_schema_metadata_manager()
+ .register_region_table_info(
+ region_id.table_id(),
+ "test_table",
+ "test_catalog",
+ "test_schema",
+ None,
+ env.get_kv_backend(),
+ )
+ .await;
+
+ let request = CreateRequestBuilder::new().build();
+ let column_schemas = rows_schema(&request);
+ engine
+ .handle_request(region_id, RegionRequest::Create(request))
+ .await
+ .unwrap();
+
+ // Put some rows so the region has active data (kept in memtable; we
+ // intentionally do not flush so the drop GC worker finds no parquet files
+ // and removes the directory immediately, avoiding the multi-minute GC wait).
+ let rows = Rows {
+ schema: column_schemas,
+ rows: build_rows_for_key("a", 0, 2, 0),
+ };
+ put_rows(&engine, region_id, rows).await;
+
+ // Sanity: nothing fired yet besides the open from create.
+ assert_eq!(hook.opened_count.load(Ordering::Relaxed), 1);
+ assert_eq!(hook.dropped_count.load(Ordering::Relaxed), 0);
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 0);
+
+ // full drop (partial_drop = false) so the GC worker physically deletes the
+ // directory and fires on_region_files_removed.
+ engine
+ .handle_request(
+ region_id,
+ RegionRequest::Drop(RegionDropRequest {
+ fast_path: false,
+ force: false,
+ partial_drop: false,
+ }),
+ )
+ .await
+ .unwrap();
+
+ // on_region_dropped fires inline while handling the drop request.
+ hook.wait_for_dropped().await;
+ assert_eq!(hook.dropped_count.load(Ordering::Relaxed), 1);
+ // Drop must not be confused with close.
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 0);
+
+ // on_region_files_removed fires from the background GC worker once the
+ // directory is physically deleted.
+ hook.wait_for_files_removed().await;
+ assert_eq!(hook.files_removed_count.load(Ordering::Relaxed), 1);
+}
diff --git a/src/mito2/src/engine/flush_test.rs b/src/mito2/src/engine/flush_test.rs
index 4870e8c2bbe..dc0063a7e63 100644
--- a/src/mito2/src/engine/flush_test.rs
+++ b/src/mito2/src/engine/flush_test.rs
@@ -895,24 +895,46 @@ async fn test_update_topic_latest_entry_id(factory: Option) {
}
#[derive(Debug)]
-struct MockRegionHook {
- sst_written_count: AtomicUsize,
- manifest_updated_count: AtomicUsize,
+pub(super) struct MockRegionHook {
+ pub(super) sst_written_count: AtomicUsize,
+ pub(super) manifest_updated_count: AtomicUsize,
+ pub(super) opened_count: AtomicUsize,
+ pub(super) closed_count: AtomicUsize,
+ pub(super) dropped_count: AtomicUsize,
+ pub(super) files_removed_count: AtomicUsize,
notify: Notify,
+ dropped_notify: Notify,
+ files_removed_notify: Notify,
}
impl MockRegionHook {
- fn new() -> Self {
+ pub(super) fn new() -> Self {
Self {
sst_written_count: AtomicUsize::new(0),
manifest_updated_count: AtomicUsize::new(0),
+ opened_count: AtomicUsize::new(0),
+ closed_count: AtomicUsize::new(0),
+ dropped_count: AtomicUsize::new(0),
+ files_removed_count: AtomicUsize::new(0),
notify: Notify::new(),
+ dropped_notify: Notify::new(),
+ files_removed_notify: Notify::new(),
}
}
async fn wait_for_manifest_update(&self) {
self.notify.notified().await;
}
+
+ /// Waits until `on_region_dropped` has fired at least once.
+ pub(super) async fn wait_for_dropped(&self) {
+ self.dropped_notify.notified().await;
+ }
+
+ /// Waits until `on_region_files_removed` has fired at least once.
+ pub(super) async fn wait_for_files_removed(&self) {
+ self.files_removed_notify.notified().await;
+ }
}
#[async_trait]
@@ -966,6 +988,35 @@ impl RegionHook for MockRegionHook {
);
self.notify.notify_one();
}
+
+ async fn on_region_opened(&self, region_id: RegionId, _region_metadata: &RegionMetadataRef) {
+ self.opened_count.fetch_add(1, Ordering::Relaxed);
+ common_telemetry::info!("MockRegionHook::on_region_opened: region={}", region_id);
+ }
+
+ async fn on_region_closed(&self, region_id: RegionId, _region_metadata: &RegionMetadataRef) {
+ self.closed_count.fetch_add(1, Ordering::Relaxed);
+ common_telemetry::info!("MockRegionHook::on_region_closed: region={}", region_id);
+ }
+
+ async fn on_region_dropped(&self, region_id: RegionId, _region_metadata: &RegionMetadataRef) {
+ self.dropped_count.fetch_add(1, Ordering::Relaxed);
+ common_telemetry::info!("MockRegionHook::on_region_dropped: region={}", region_id);
+ self.dropped_notify.notify_one();
+ }
+
+ async fn on_region_files_removed(
+ &self,
+ region_id: RegionId,
+ _region_metadata: &RegionMetadataRef,
+ ) {
+ self.files_removed_count.fetch_add(1, Ordering::Relaxed);
+ common_telemetry::info!(
+ "MockRegionHook::on_region_files_removed: region={}",
+ region_id
+ );
+ self.files_removed_notify.notify_one();
+ }
}
#[tokio::test]
diff --git a/src/mito2/src/engine/open_test.rs b/src/mito2/src/engine/open_test.rs
index cf4bfb1ff1d..ee0d9560093 100644
--- a/src/mito2/src/engine/open_test.rs
+++ b/src/mito2/src/engine/open_test.rs
@@ -32,6 +32,8 @@ use tokio::sync::oneshot;
use crate::compaction::compactor::{OpenCompactionRegionRequest, open_compaction_region};
use crate::config::MitoConfig;
+use crate::engine::flush_test::MockRegionHook;
+use crate::engine::region_hook::RegionHookRef;
use crate::error;
use crate::region::opener::{PartitionExprFetcher, PartitionExprFetcherRef};
use crate::region::options::RegionOptions;
@@ -805,3 +807,36 @@ async fn test_open_keeps_none_without_fetcher() {
let meta = engine.get_region(region_id).unwrap().metadata();
assert!(meta.partition_expr.is_none());
}
+
+#[tokio::test]
+async fn test_region_hook_on_open() {
+ common_telemetry::init_default_ut_logging();
+ let mut env = TestEnv::with_prefix("open_hook").await;
+
+ let hook = Arc::new(MockRegionHook::new());
+ let plugins = Plugins::new();
+ plugins.insert(hook.clone() as RegionHookRef);
+
+ let engine = env
+ .create_engine_with_plugins(MitoConfig::default(), plugins)
+ .await;
+
+ let region_id = RegionId::new(1, 1);
+ let request = CreateRequestBuilder::new().build();
+ let table_dir = request.table_dir.clone();
+ engine
+ .handle_request(region_id, RegionRequest::Create(request))
+ .await
+ .unwrap();
+
+ // Creating a region fires on_region_opened exactly once.
+ assert_eq!(hook.opened_count.load(Ordering::Relaxed), 1);
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 0);
+
+ // `reopen_region` closes then opens; the open must fire the hook again.
+ reopen_region(&engine, region_id, table_dir, false, Default::default()).await;
+
+ assert_eq!(hook.opened_count.load(Ordering::Relaxed), 2);
+ assert_eq!(hook.closed_count.load(Ordering::Relaxed), 1);
+ assert_eq!(hook.dropped_count.load(Ordering::Relaxed), 0);
+}
diff --git a/src/mito2/src/engine/region_hook.rs b/src/mito2/src/engine/region_hook.rs
index d1b28f6ebae..9c5a7dfc95d 100644
--- a/src/mito2/src/engine/region_hook.rs
+++ b/src/mito2/src/engine/region_hook.rs
@@ -16,15 +16,24 @@
//!
//! ## Design
//!
-//! The [`RegionHook`] trait provides two methods with clear separation of concerns:
+//! The [`RegionHook`] trait observes region activity through two categories of
+//! callbacks — manifest/file observation and region lifecycle:
//!
//! - [`on_sst_files_written`]: Fires when mito2 physically writes SST **data files**.
//! Provides per-file [`SstInfo`] + [`FileMeta`]; metadata richness varies by path
//! (see [`SstFileInfo`] and the coverage footnote).
//!
-//! - [`on_manifest_updated`]: Fires after **any** manifest write is successfully committed.
-//! Receives the full [`RegionMetaActionList`] so consumers can inspect what changed
-//! (file additions/removals, schema changes, truncation, partition expression changes, etc.).
+//! - [`on_manifest_updated`]: Fires after a manifest write is committed to the **live**
+//! (normal) manifest directory. Writes to the staging directory (enter staging,
+//! operations during staging, the intermediate apply-staging edit) are suppressed —
+//! their effects are accumulated and delivered in a single notification when the
+//! staged actions are promoted to the live manifest. Receives the full
+//! [`RegionMetaActionList`] so consumers can inspect what changed (file additions/
+//! removals, schema changes, truncation, partition expression changes, etc.).
+//!
+//! - [`on_region_opened`] / [`on_region_closed`] / [`on_region_dropped`] / [`on_region_files_removed`]:
+//! Region **lifecycle** callbacks for open, close, logical drop, and physical file removal.
+//! See [Region lifecycle](#region-lifecycle) below.
//!
//! Hook implementations are registered via the [`Plugins`](common_base::Plugins) system:
//! ```ignore
@@ -33,6 +42,12 @@
//!
//! ## Coverage
//!
+//! Only manifest writes to the **normal** (live) manifest directory trigger
+//! `on_manifest_updated`. Writes to the staging manifest directory (operations
+//! that happen while the region is in staging mode) are intentionally suppressed:
+//! their effects are accumulated and delivered in a single notification when
+//! the staged actions are promoted to the live manifest via `exit_staging_on_success`.
+//!
//! | Scenario | `on_sst_files_written` | `on_manifest_updated` |
//! |------------------------------|:----------------------:|:---------------------:|
//! | Flush (memtable → SST) | ✅ Yes | ✅ Yes |
@@ -40,23 +55,57 @@
//! | Remote compaction | ✅ (compactor node) ¹ | ✅ (compactor node) ¹ |
//! | RegionEdit / bulk ingestion | ❌ (files pre-written) | ✅ Yes |
//! | Copy region | ❌ (object-store copy) | ✅ Yes |
-//! | Apply staging | ❌ (delegates to edit) | ✅ Yes ² |
+//! | Apply staging (promote) | ❌ (delegates to edit) | ✅ Yes ² |
//! | Alter (schema change) | ❌ (no SST files) | ✅ Yes |
//! | Truncate | ❌ (removes files) | ✅ Yes |
-//! | Enter staging | ❌ (no SST files) | ✅ Yes |
+//! | Enter staging | ❌ (no SST files) | ❌ (staging dir) |
+//! | Operations during staging | N/A | ❌ (staging dir) |
//! | Async index build | ❌ (index files only) | ✅ Yes |
//!
//! ¹ Remote compaction runs on a dedicated compactor node via `open_compaction_region()`;
//! pass plugins via `OpenCompactionRegionRequest` to enable hooks there. `sst_infos` is
//! `#[serde(skip)]` over the wire, so each [`SstInfo`] is rebuilt from [`FileMeta`] with
//! empty footer/index — see [`SstFileInfo`] for field-level detail.
-//! ² Apply staging fires `on_manifest_updated` twice: once when the staging SST files are
-//! committed via `RegionEdit`, and once when `exit_staging_on_success` merges all staged
-//! manifest actions into the live manifest.
+//! ² Apply staging fires `on_manifest_updated` once when `exit_staging_on_success` promotes
+//! all staged manifest actions (including the SST file additions) into the live manifest.
+//! The intermediate staging `RegionEdit` is written to the staging directory and does not
+//! fire the hook — its file list is included in the promote notification.
//!
//! The following paths do **not** trigger any hook:
//! - Follower region sync / catchup (manifest read-only; followers don't author changes)
-//! - GC / checkpoint / drop / remap (internal bookkeeping, not logical state changes)
+//! - GC / checkpoint / remap (internal bookkeeping, not logical state changes)
+//!
+//! An explicit region **drop** does fire lifecycle hooks — see
+//! [Region lifecycle](#region-lifecycle).
+//!
+//! ## Region lifecycle
+//!
+//! Beyond manifest/SST observation, the hook observes the high-level lifecycle of an
+//! active region:
+//!
+//! | Event | Method | When |
+//! |-------|--------|------|
+//! | Open | [`on_region_opened`] | A create or open request registers the region as active (the counterpart to close/drop). Does not fire for the compactor's transient regions or the catch-up reopen. |
+//! | Close | [`on_region_closed`] | A close request (or a close-after-flush) removes the region from the active set. Data files, manifest and WAL state are **preserved**; the region may be reopened. |
+//! | Logical drop | [`on_region_dropped`] | A drop request has been handled: the region leaves the active set and its WAL entries are marked obsolete. Data files are **not yet deleted**. |
+//! | Physical file removal | [`on_region_files_removed`] | The drop GC worker has deleted the region directory. Terminal file-lifecycle event. |
+//!
+//! Notes:
+//! - `on_region_closed` / `on_region_dropped` run **inline in the region worker loop**,
+//! so implementations must be fast (same contract as `on_manifest_updated`).
+//! - `on_region_opened` runs inline in the worker loop on the **create** path, but on the
+//! **open** path it fires inside the spawned open task (`common_runtime::spawn_global`),
+//! i.e. concurrently with the worker loop — after WAL replay, before the region is
+//! registered and its open request is acknowledged. Implementations must still be fast
+//! and must not assume worker-loop-thread affinity or strict ordering against concurrent
+//! requests to other regions.
+//! - `on_region_files_removed` runs on the background drop GC task, outside the worker loop.
+//! - When global GC is enabled and a normal table region is dropped with `partial_drop`, its
+//! directory is left for global reclamation and `on_region_files_removed` is **not** fired
+//! by the drop worker (observe it via the global GC path instead).
+//! - Logical file removal (compaction, region edit, truncate) is already observable via
+//! [`on_manifest_updated`] (`Edit.files_to_remove` / `Truncate` action); only the drop
+//! worker's physical directory deletion needs a dedicated file hook.
//!
//! ## Invocation points
//!
@@ -77,11 +126,18 @@
//!
//! ## Future work
//!
-//! A future `on_files_removed` hook may be added to observe file lifecycle end
-//! (GC, drop, truncate, compaction removal). This is not yet implemented.
+//! `on_region_files_removed` currently covers only the **drop** GC worker's physical
+//! directory removal. A broader per-file `on_files_removed` hook covering compaction
+//! removal, truncate, and the global GC reclamation path is not yet implemented
+//! (though logical file removal is already observable via `on_manifest_updated`).
+//! Role/leadership transitions (`on_region_role_changed`) are also not hooked.
//!
//! [`on_sst_files_written`]: RegionHook::on_sst_files_written
//! [`on_manifest_updated`]: RegionHook::on_manifest_updated
+//! [`on_region_opened`]: RegionHook::on_region_opened
+//! [`on_region_closed`]: RegionHook::on_region_closed
+//! [`on_region_dropped`]: RegionHook::on_region_dropped
+//! [`on_region_files_removed`]: RegionHook::on_region_files_removed
//! [`RegionManifestManager::update`]: crate::manifest::manager::RegionManifestManager::update
//! [`ManifestContext::update_locked`]: crate::region::ManifestContext::update_locked
//! [`ManifestContext::update_manifest`]: crate::region::ManifestContext::update_manifest
@@ -103,6 +159,13 @@ use crate::sst::parquet::SstInfo;
///
/// Must be [`fire`](Self::fire)d **after** the manifest write lock is released
/// (the hook may read the manifest). `#[must_use]` so a forgotten receipt warns.
+///
+/// ## Staging suppression
+///
+/// When `is_staging` is `true`, [`fire`](Self::fire) is a no-op — the write went to
+/// the staging manifest directory. The hook only observes writes to the live (normal)
+/// manifest directory. Staging actions are accumulated and delivered in a single
+/// notification when `exit_staging_on_success` promotes them (`is_staging = false`).
#[must_use = "the region hook must be fired after releasing the manifest write lock"]
pub(crate) struct PendingManifestHook {
region_id: RegionId,
@@ -110,6 +173,9 @@ pub(crate) struct PendingManifestHook {
action_list: Option,
version: ManifestVersion,
hook: Option,
+ /// Whether the manifest write went to the staging directory.
+ /// When `true`, `fire()` is suppressed — the hook only observes live manifest writes.
+ is_staging: bool,
}
impl PendingManifestHook {
@@ -118,12 +184,14 @@ impl PendingManifestHook {
action_list: Option,
version: ManifestVersion,
hook: Option,
+ is_staging: bool,
) -> Self {
Self {
region_id,
action_list,
version,
hook,
+ is_staging,
}
}
@@ -132,9 +200,13 @@ impl PendingManifestHook {
self.version
}
- /// Fires the hook if one is registered. Safe to call unconditionally: it is
- /// a no-op when no hook is registered.
+ /// Fires the hook if one is registered, **unless** the write went to the staging
+ /// manifest directory (`is_staging = true`). Safe to call unconditionally:
+ /// it is a no-op when no hook is registered or when the write is staging-only.
pub(crate) async fn fire(self) {
+ if self.is_staging {
+ return;
+ }
if let (Some(hook), Some(action_list)) = (self.hook, self.action_list) {
hook.on_manifest_updated(self.region_id, &action_list, self.version)
.await;
@@ -146,6 +218,9 @@ impl PendingManifestHook {
/// keeps `self`'s actions followed by `other`'s, and the *later* manifest
/// version wins. Used when a sequence of writes (e.g. staging-exit followed
/// by metadata backfill) should notify the hook exactly once.
+ ///
+ /// `is_staging` is `true` only if **both** sides are staging; if either side
+ /// is a live write, the merged result is also live.
pub(crate) fn merge(self, other: PendingManifestHook) -> PendingManifestHook {
debug_assert_eq!(
self.region_id, other.region_id,
@@ -164,6 +239,7 @@ impl PendingManifestHook {
},
version: self.version.max(other.version),
hook: self.hook.or(other.hook),
+ is_staging: self.is_staging && other.is_staging,
}
}
}
@@ -211,10 +287,14 @@ pub trait RegionHook: Send + Sync + Debug {
let _ = (region_id, region_metadata, files);
}
- /// Called after the region manifest is successfully committed.
+ /// Called after the region manifest is successfully committed to the **live**
+ /// (normal) manifest directory.
///
- /// Fires for **all** manifest write paths: flush, compaction, region edit,
- /// copy region, alter, truncate, enter staging, index build, etc.
+ /// Fires for: flush, compaction, region edit, copy region, alter, truncate,
+ /// async index build, and apply-staging promote. Does **not** fire for writes
+ /// to the staging manifest directory (enter staging, operations during staging,
+ /// the intermediate apply-staging edit) — those are suppressed because their
+ /// effects are accumulated and delivered in a single promote notification.
///
/// Does **not** fire for:
/// - Manifest reads / follower sync (no write)
@@ -228,6 +308,80 @@ pub trait RegionHook: Send + Sync + Debug {
) {
let _ = (region_id, action_list, manifest_version);
}
+
+ /// Called once a region **open** or **create** succeeds, but **before** the
+ /// region is registered in the engine's active set (`insert_region` runs
+ /// immediately afterwards).
+ ///
+ /// Fires once when a region becomes active via a create or open request —
+ /// the natural counterpart to [`on_region_closed`] / [`on_region_dropped`].
+ /// It does **not** fire for the compactor's transient compaction regions
+ /// (`open_compaction_region`), nor for the internal reopen performed during
+ /// follower catch-up / leadership promotion.
+ ///
+ /// On the **create** path it runs inline in the region worker loop; on the
+ /// **open** path it runs inside the spawned open task
+ /// (`common_runtime::spawn_global`), concurrently with the worker loop
+ /// (after WAL replay, before the region is registered/acknowledged).
+ /// Implementations must be fast and must **not** assume worker-loop-thread
+ /// affinity or strict ordering against concurrent requests to other regions.
+ ///
+ /// [`on_region_closed`]: RegionHook::on_region_closed
+ /// [`on_region_dropped`]: RegionHook::on_region_dropped
+ async fn on_region_opened(&self, region_id: RegionId, region_metadata: &RegionMetadataRef) {
+ let _ = (region_id, region_metadata);
+ }
+
+ /// Called after a region is **closed** via a close request.
+ ///
+ /// The region is removed from the engine's active set, but its data files,
+ /// manifest, and WAL state are **preserved**; the region may be reopened
+ /// later. Fires once per successful close, after the region's background
+ /// tasks (flush/compaction) have been stopped.
+ ///
+ /// Fires for a region of **any** role (leader or follower) that is closed.
+ /// Does **not** fire when a region is dropped (see [`on_region_dropped`]).
+ ///
+ /// Runs inline in the region worker loop; implementations should be fast.
+ ///
+ /// [`on_region_dropped`]: RegionHook::on_region_dropped
+ async fn on_region_closed(&self, region_id: RegionId, region_metadata: &RegionMetadataRef) {
+ let _ = (region_id, region_metadata);
+ }
+
+ /// Called after a region is **logically dropped** (a drop request has been
+ /// handled).
+ ///
+ /// The region is removed from the active set and its WAL entries are marked
+ /// obsolete. Its data files are **not yet deleted** — they are scheduled for
+ /// asynchronous removal by the GC worker. Observe physical deletion via
+ /// [`on_region_files_removed`].
+ ///
+ /// Runs inline in the region worker loop; implementations should be fast.
+ ///
+ /// [`on_region_files_removed`]: RegionHook::on_region_files_removed
+ async fn on_region_dropped(&self, region_id: RegionId, region_metadata: &RegionMetadataRef) {
+ let _ = (region_id, region_metadata);
+ }
+
+ /// Called after a dropped region's data files are **physically removed** by
+ /// the drop GC worker (the region directory has been deleted).
+ ///
+ /// This is the terminal event in a region's file lifecycle; no further
+ /// callbacks fire for this region id afterwards. Fires only when the drop
+ /// worker itself deletes the directory. When global GC is enabled and the
+ /// region is a normal table region dropped with `partial_drop`, the
+ /// directory is left for global reclamation and this hook is **not** fired
+ /// by the drop worker.
+ ///
+ /// Runs on a background task, outside the region worker loop.
+ async fn on_region_files_removed(
+ &self,
+ region_id: RegionId,
+ region_metadata: &RegionMetadataRef,
+ ) {
+ let _ = (region_id, region_metadata);
+ }
}
pub type RegionHookRef = Arc;
diff --git a/src/mito2/src/region.rs b/src/mito2/src/region.rs
index 1e173ab62d2..c566dd47c04 100644
--- a/src/mito2/src/region.rs
+++ b/src/mito2/src/region.rs
@@ -1236,6 +1236,7 @@ impl ManifestContext {
action_list_for_hook,
version,
self.hook.clone(),
+ is_staging,
))
}
diff --git a/src/mito2/src/worker/handle_close.rs b/src/mito2/src/worker/handle_close.rs
index a616a0e32dc..b582c276927 100644
--- a/src/mito2/src/worker/handle_close.rs
+++ b/src/mito2/src/worker/handle_close.rs
@@ -89,5 +89,13 @@ impl RegionWorkerLoop
{
// clean index build status.
self.index_build_scheduler.on_region_closed(region_id).await;
self.region_count.dec();
+
+ // Notify the region hook that the region has been closed. The region is
+ // fully stopped and unregistered, but its files/manifest are preserved.
+ // Runs inline; the hook contract requires it to be fast.
+ if let Some(hook) = region.manifest_ctx.hook() {
+ let metadata = region.metadata();
+ hook.on_region_closed(region_id, &metadata).await;
+ }
}
}
diff --git a/src/mito2/src/worker/handle_create.rs b/src/mito2/src/worker/handle_create.rs
index 6e43e74a0e4..bf254dc1e6b 100644
--- a/src/mito2/src/worker/handle_create.rs
+++ b/src/mito2/src/worker/handle_create.rs
@@ -86,6 +86,12 @@ impl RegionWorkerLoop {
self.region_count.inc();
+ // Notify the region hook that the region has been opened (created).
+ // Fires before registration; allocates nothing when no hook is registered.
+ if let Some(hook) = region.manifest_ctx.hook() {
+ hook.on_region_opened(region_id, ®ion.metadata()).await;
+ }
+
// Insert the MitoRegion into the RegionMap.
self.regions.insert_region(region);
diff --git a/src/mito2/src/worker/handle_drop.rs b/src/mito2/src/worker/handle_drop.rs
index 00a96b0d166..3d111776b82 100644
--- a/src/mito2/src/worker/handle_drop.rs
+++ b/src/mito2/src/worker/handle_drop.rs
@@ -23,10 +23,12 @@ use object_store::util::join_path;
use object_store::{EntryMode, ObjectStore};
use snafu::ResultExt;
use store_api::logstore::LogStore;
+use store_api::metadata::RegionMetadataRef;
use store_api::region_request::{AffectedRows, PathType};
use store_api::storage::RegionId;
use tokio::time::sleep;
+use crate::engine::region_hook::RegionHookRef;
use crate::error::{OpenDalSnafu, Result};
use crate::region::{RegionLeaderState, RegionMapRef};
use crate::worker::{DROPPING_MARKER_FILE, RegionWorkerLoop};
@@ -106,6 +108,22 @@ where
self.region_count.dec();
+ // Notify registered hooks that the region has been logically dropped, and
+ // prepare a payload for the background GC task to fire the terminal
+ // `on_region_files_removed`. When no hook is registered this allocates
+ // nothing — no metadata snapshot is taken and no payload is built.
+ let hook_payload = match region.manifest_ctx.hook() {
+ Some(hook) => {
+ let region_metadata = region.metadata();
+ hook.on_region_dropped(region_id, ®ion_metadata).await;
+ Some(DropHookPayload {
+ hook,
+ metadata: region_metadata,
+ })
+ }
+ None => None,
+ };
+
let object_store = region.access_layer.object_store().clone();
let dropping_regions = self.dropping_regions.clone();
let listener = self.listener.clone();
@@ -122,6 +140,7 @@ where
object_store,
dropping_regions,
partial_drop,
+ hook_payload.as_ref(),
)
.await
} else {
@@ -135,6 +154,7 @@ where
object_store,
dropping_regions,
gc_duration,
+ hook_payload.as_ref(),
)
.await
};
@@ -156,6 +176,19 @@ where
}
}
+/// Carries the region hook and region metadata into the background GC task so
+/// it can fire [`RegionHook::on_region_files_removed`] once the dropped region's
+/// directory is physically deleted.
+///
+/// Only constructed when a hook is registered; the task receives it as
+/// `Option<&DropHookPayload>` so the no-hook path allocates nothing.
+///
+/// [`RegionHook::on_region_files_removed`]: crate::engine::region_hook::RegionHook::on_region_files_removed
+struct DropHookPayload {
+ hook: RegionHookRef,
+ metadata: RegionMetadataRef,
+}
+
/// Background GC task to remove the entire region path once one of the following
/// conditions is true:
/// - It finds there is no parquet file left.
@@ -172,6 +205,7 @@ async fn later_drop_task_without_global_gc(
object_store: ObjectStore,
dropping_regions: RegionMapRef,
gc_duration: Duration,
+ hook_payload: Option<&DropHookPayload>,
) -> bool {
remove_region_with_retry(
region_id,
@@ -180,6 +214,7 @@ async fn later_drop_task_without_global_gc(
dropping_regions,
Some(gc_duration),
false,
+ hook_payload,
)
.await
}
@@ -191,6 +226,7 @@ async fn remove_region_with_retry(
dropping_regions: std::sync::Arc,
gc_duration: Option,
mut force: bool,
+ hook_payload: Option<&DropHookPayload>,
) -> bool {
for _ in 0..MAX_RETRY_TIMES {
let result = remove_region_dir_once(®ion_path, &object_store, force).await;
@@ -204,6 +240,15 @@ async fn remove_region_with_retry(
Ok(true) => {
dropping_regions.remove_region(region_id);
info!("Region {} is dropped, force: {}", region_path, force);
+ // The region directory has been physically deleted; fire the
+ // terminal file-lifecycle event. The partial-drop/global-GC path
+ // never reaches here (it does not delete the directory itself).
+ if let Some(hook_payload) = hook_payload {
+ hook_payload
+ .hook
+ .on_region_files_removed(region_id, &hook_payload.metadata)
+ .await;
+ }
return true;
}
Ok(false) => (),
@@ -230,6 +275,7 @@ async fn later_drop_task_with_global_gc(
object_store: ObjectStore,
dropping_regions: RegionMapRef,
partial_drop: bool,
+ hook_payload: Option<&DropHookPayload>,
) -> bool {
// For metadata regions or regions marked for full deletion (such as when dropping a table)
// the region directory is forcefully removed immediately.
@@ -243,6 +289,7 @@ async fn later_drop_task_with_global_gc(
dropping_regions,
None,
true,
+ hook_payload,
)
.await
} else {
diff --git a/src/mito2/src/worker/handle_open.rs b/src/mito2/src/worker/handle_open.rs
index 3d3520b0cc8..48fef5ddd6f 100644
--- a/src/mito2/src/worker/handle_open.rs
+++ b/src/mito2/src/worker/handle_open.rs
@@ -149,6 +149,13 @@ impl RegionWorkerLoop {
);
region_count.inc();
+ // Notify the region hook that the region has been opened.
+ // Fires before registration; allocates nothing when no hook
+ // is registered.
+ if let Some(hook) = region.manifest_ctx.hook() {
+ hook.on_region_opened(region_id, ®ion.metadata()).await;
+ }
+
// Insert the Region into the RegionMap.
regions.insert_region(region);
diff --git a/src/query/src/parser.rs b/src/query/src/parser.rs
index 53f24557c73..87b827e0cc1 100644
--- a/src/query/src/parser.rs
+++ b/src/query/src/parser.rs
@@ -52,45 +52,37 @@ pub enum QueryStatement {
}
impl QueryStatement {
- pub fn post_process(&self, params: HashMap) -> Result {
+ pub fn post_process(self, params: HashMap) -> Result {
match self {
QueryStatement::Sql(_) => UnimplementedSnafu {
operation: "sql post process",
}
.fail(),
- QueryStatement::Promql(eval_stmt, alias) => {
+ QueryStatement::Promql(mut eval_stmt, alias) => {
let node_name = match params.get("name") {
Some(name) => name.as_str(),
None => "",
};
- let extension_node = Self::create_extension_node(node_name, &eval_stmt.expr);
- Ok(QueryStatement::Promql(
- EvalStmt {
- expr: Extension(extension_node.unwrap()),
- start: eval_stmt.start,
- end: eval_stmt.end,
- interval: eval_stmt.interval,
- lookback_delta: eval_stmt.lookback_delta,
- },
- alias.clone(),
- ))
+ let extension_node = Self::create_extension_node(node_name, eval_stmt.expr);
+ eval_stmt.expr = Extension(extension_node.unwrap());
+ Ok(QueryStatement::Promql(eval_stmt, alias))
}
}
}
- fn create_extension_node(node_name: &str, expr: &Expr) -> Option {
+ fn create_extension_node(node_name: &str, expr: Expr) -> Option {
match node_name {
ANALYZE_NODE_NAME => Some(NodeExtension {
- expr: Arc::new(AnalyzeExpr { expr: expr.clone() }),
+ expr: Arc::new(AnalyzeExpr { expr }),
}),
ANALYZE_VERBOSE_NODE_NAME => Some(NodeExtension {
- expr: Arc::new(AnalyzeVerboseExpr { expr: expr.clone() }),
+ expr: Arc::new(AnalyzeVerboseExpr { expr }),
}),
EXPLAIN_NODE_NAME => Some(NodeExtension {
- expr: Arc::new(ExplainExpr { expr: expr.clone() }),
+ expr: Arc::new(ExplainExpr { expr }),
}),
EXPLAIN_VERBOSE_NODE_NAME => Some(NodeExtension {
- expr: Arc::new(ExplainVerboseExpr { expr: expr.clone() }),
+ expr: Arc::new(ExplainVerboseExpr { expr }),
}),
_ => None,
}
@@ -204,9 +196,10 @@ impl QueryLanguageParser {
}
pub(crate) fn apply_alias_extension(mut eval_stmt: EvalStmt, alias: &str) -> EvalStmt {
+ let expr = eval_stmt.expr;
eval_stmt.expr = Extension(NodeExtension {
expr: Arc::new(AliasExpr {
- expr: eval_stmt.expr.clone(),
+ expr,
alias: alias.to_string(),
}),
});
@@ -263,6 +256,14 @@ macro_rules! define_node_ast_extension {
fn children(&self) -> &[Expr] {
std::slice::from_ref(&self.expr)
}
+
+ fn with_new_children(&self, children: Vec) -> Arc {
+ let mut iter = children.into_iter();
+ match (iter.next(), iter.next()) {
+ (Some(expr), None) => Arc::new($name_expr { expr }),
+ _ => Arc::new(self.clone()),
+ }
+ }
}
#[allow(rustdoc::broken_intra_doc_links)]
@@ -313,6 +314,16 @@ impl ExtensionExpr for AliasExpr {
fn children(&self) -> &[Expr] {
std::slice::from_ref(&self.expr)
}
+ fn with_new_children(&self, children: Vec) -> Arc {
+ let mut iter = children.into_iter();
+ match (iter.next(), iter.next()) {
+ (Some(expr), None) => Arc::new(Self {
+ expr,
+ alias: self.alias.clone(),
+ }),
+ _ => Arc::new(self.clone()),
+ }
+ }
}
#[derive(Debug, Clone)]
pub struct Alias {
diff --git a/src/query/src/promql/planner.rs b/src/query/src/promql/planner.rs
index c2cd6316ada..61913156cf8 100644
--- a/src/query/src/promql/planner.rs
+++ b/src/query/src/promql/planner.rs
@@ -229,6 +229,8 @@ impl IslandExpr {
!modifier.return_bool
&& modifier.matching.is_none()
&& matches!(modifier.card, VectorMatchCardinality::OneToOne)
+ && modifier.fill_values.lhs.is_none()
+ && modifier.fill_values.rhs.is_none()
}) =>
{
let lhs = Self::try_new(lhs, env)?;
@@ -1093,6 +1095,18 @@ impl PromPlanner {
query_engine_state: &QueryEngineState,
binary_expr: &PromBinaryExpr,
) -> Result {
+ // promql-parser accepts fill modifiers, but Greptime does not implement the
+ // required outer joins and missing-value substitution. Reject them before the
+ // binary-island fast path so they cannot silently behave like normal inner joins.
+ if let Some(modifier) = &binary_expr.modifier {
+ ensure!(
+ modifier.fill_values.lhs.is_none() && modifier.fill_values.rhs.is_none(),
+ UnsupportedExprSnafu {
+ name: "PromQL fill modifiers"
+ }
+ );
+ }
+
if let Some(plan) = self.try_plan_binary_island(binary_expr).await? {
return Ok(plan);
}
@@ -5542,6 +5556,33 @@ mod test {
);
}
+ #[tokio::test]
+ async fn reject_binary_fill_modifiers() {
+ let state = build_query_engine_state();
+
+ for query in [
+ "some_metric + fill(0) some_alt_metric",
+ "some_metric + fill_left(0) some_alt_metric",
+ "some_metric + fill_right(0) some_alt_metric",
+ "(some_metric + fill(0) some_alt_metric) + some_metric",
+ ] {
+ let eval_stmt = build_eval_stmt(query);
+ let table_provider = build_test_table_provider(&[], 0, 0).await;
+ let err = PromPlanner::stmt_to_plan(table_provider, &eval_stmt, &state)
+ .await
+ .unwrap_err();
+
+ assert!(
+ matches!(
+ &err,
+ crate::promql::error::Error::UnsupportedExpr { name, .. }
+ if name == "PromQL fill modifiers"
+ ),
+ "{err}"
+ );
+ }
+ }
+
#[tokio::test]
async fn timestamp_binary_join_falls_back_when_tsid_is_projected_out() {
for query in [
diff --git a/tests-integration/src/tests/instance_test.rs b/tests-integration/src/tests/instance_test.rs
index 628f97de96a..8572e9ce5b2 100644
--- a/tests-integration/src/tests/instance_test.rs
+++ b/tests-integration/src/tests/instance_test.rs
@@ -1098,6 +1098,10 @@ async fn test_execute_copy_from_csv_strict_headers(instance: Arcv1.1.1"]
+features = ["json", "json2", "table", "read"]
+owner = "query"
diff --git a/tests/compatibility/cases/legacy_json2_variant_payload/setup.sql b/tests/compatibility/cases/legacy_json2_variant_payload/setup.sql
new file mode 100644
index 00000000000..cef3a913c93
--- /dev/null
+++ b/tests/compatibility/cases/legacy_json2_variant_payload/setup.sql
@@ -0,0 +1,29 @@
+CREATE TABLE t_legacy_json2_variant_payload (
+ ts TIMESTAMP TIME INDEX,
+ j JSON2
+) WITH (
+ 'append_mode' = 'true'
+);
+
+INSERT INTO t_legacy_json2_variant_payload (ts, j) VALUES
+ ('2026-07-08 00:00:00+0000', '{"a": {"b": 1}, "c": "s1", "d": [{"e": {"f": 0.1}}]}'),
+ ('2026-07-08 00:01:00+0000', '{"a": {"b": -2}, "c": [1], "d": [{"e": {"f": 0.2}}]}'),
+ ('2026-07-08 00:02:00+0000', '{"a": {"b": "s3"}, "c": "s3", "d": [{"e": {"g": -0.3}}]}'),
+ ('2026-07-08 00:03:00+0000', '{"a": {"b": null}, "c": null}'),
+ ('2026-07-08 00:04:00+0000', '{"c": "s5", "d": {"e": true}}'),
+ ('2026-07-08 00:05:00+0000', '{"a": {"b": 6}}');
+
+ADMIN FLUSH_TABLE('t_legacy_json2_variant_payload');
+
+CREATE TABLE t_legacy_json2_variant_payload_object_d (
+ ts TIMESTAMP TIME INDEX,
+ j JSON2
+) WITH (
+ 'append_mode' = 'true'
+);
+
+INSERT INTO t_legacy_json2_variant_payload_object_d (ts, j) VALUES
+ ('2026-07-08 01:00:00+0000', '{"d": {"e": true}}'),
+ ('2026-07-08 01:01:00+0000', '{"d": {"e": false}}');
+
+ADMIN FLUSH_TABLE('t_legacy_json2_variant_payload_object_d');
diff --git a/tests/compatibility/cases/legacy_json2_variant_payload/verify.result b/tests/compatibility/cases/legacy_json2_variant_payload/verify.result
new file mode 100644
index 00000000000..a474cc84345
--- /dev/null
+++ b/tests/compatibility/cases/legacy_json2_variant_payload/verify.result
@@ -0,0 +1,60 @@
+SELECT ts, j.a.b AS a_b, j.c AS c
+FROM t_legacy_json2_variant_payload
+ORDER BY ts;
+
++---------------------+-----+-----+
+| ts | a_b | c |
++---------------------+-----+-----+
+| 2026-07-08T00:00:00 | 1 | s1 |
+| 2026-07-08T00:01:00 | -2 | [1] |
+| 2026-07-08T00:02:00 | s3 | s3 |
+| 2026-07-08T00:03:00 | | |
+| 2026-07-08T00:04:00 | | s5 |
+| 2026-07-08T00:05:00 | 6 | |
++---------------------+-----+-----+
+
+SELECT
+ ts,
+ j.d.e AS d_e
+FROM t_legacy_json2_variant_payload_object_d
+ORDER BY ts;
+
++---------------------+-------+
+| ts | d_e |
++---------------------+-------+
+| 2026-07-08T01:00:00 | true |
+| 2026-07-08T01:01:00 | false |
++---------------------+-------+
+
+-- JSON2 projection rendering is a user-visible compatibility contract.
+SELECT ts, j.d AS d
+FROM t_legacy_json2_variant_payload
+ORDER BY ts;
+
++---------------------+--------------------+
+| ts | d |
++---------------------+--------------------+
+| 2026-07-08T00:00:00 | [{"e":{"f":0.1}}] |
+| 2026-07-08T00:01:00 | [{"e":{"f":0.2}}] |
+| 2026-07-08T00:02:00 | [{"e":{"g":-0.3}}] |
+| 2026-07-08T00:03:00 | |
+| 2026-07-08T00:04:00 | {"e":true} |
+| 2026-07-08T00:05:00 | |
++---------------------+--------------------+
+
+SHOW CREATE TABLE t_legacy_json2_variant_payload;
+
++--------------------------------+---------------------------------------------------------------+
+| Table | Create Table |
++--------------------------------+---------------------------------------------------------------+
+| t_legacy_json2_variant_payload | CREATE TABLE IF NOT EXISTS "t_legacy_json2_variant_payload" ( |
+| | "ts" TIMESTAMP(3) NOT NULL, |
+| | "j" JSON2 NULL, |
+| | TIME INDEX ("ts") |
+| | ) |
+| | |
+| | ENGINE=mito |
+| | WITH( |
+| | append_mode = 'true' |
+| | ) |
++--------------------------------+---------------------------------------------------------------+
diff --git a/tests/compatibility/cases/legacy_json2_variant_payload/verify.sql b/tests/compatibility/cases/legacy_json2_variant_payload/verify.sql
new file mode 100644
index 00000000000..a3c2cab1b92
--- /dev/null
+++ b/tests/compatibility/cases/legacy_json2_variant_payload/verify.sql
@@ -0,0 +1,16 @@
+SELECT ts, j.a.b AS a_b, j.c AS c
+FROM t_legacy_json2_variant_payload
+ORDER BY ts;
+
+SELECT
+ ts,
+ j.d.e AS d_e
+FROM t_legacy_json2_variant_payload_object_d
+ORDER BY ts;
+
+-- JSON2 projection rendering is a user-visible compatibility contract.
+SELECT ts, j.d AS d
+FROM t_legacy_json2_variant_payload
+ORDER BY ts;
+
+SHOW CREATE TABLE t_legacy_json2_variant_payload;
diff --git a/tests/perf/AGENTS.md b/tests/perf/AGENTS.md
index eb95544d22d..7f64b283bdc 100644
--- a/tests/perf/AGENTS.md
+++ b/tests/perf/AGENTS.md
@@ -11,14 +11,14 @@
docs together.
- `[case]` is report metadata only. `[scenario]` is the executable regression
configuration and must include `kind`, data layout, tables, queries, and
- thresholds. Keep scenario parsing explicit in both
- `tests/perf/query_regression_runner.py` and
- `src/cmd/src/bin/query_perf_fixture.rs`.
+ thresholds. Rust owns case schema, defaults, validation, and normalized plan
+ output through `query_perf_fixture plan`; `tests/perf/query_regression_runner.py`
+ should only orchestrate from that normalized JSON.
- Keep the direct-SST generator generic. Issue-specific behavior belongs in case
files and thresholds, not in Rust generator logic.
- Before pushing perf harness changes, run at least:
- `uv run --no-project python -m py_compile .github/scripts/query-regression-run.py .github/scripts/query-regression-summary.py .github/scripts/query-regression-pr-metadata.py tests/perf/query_regression_runner.py`
- `cargo fmt --all -- --check`
- - `cargo build -p cmd --bin query_perf_fixture`
+ - `cargo build -p cmd --bin query_perf_fixture --features dev-tools`
- dry-run the Python runner and Rust fixture generator against all built-in
cases when the DSL or workflow case selection changes.
diff --git a/tests/perf/README.md b/tests/perf/README.md
index a59081b5681..91bc6c1637e 100644
--- a/tests/perf/README.md
+++ b/tests/perf/README.md
@@ -4,6 +4,11 @@ This directory is for query performance cases that compare a base build with a
candidate build. It is not a replacement for sqlness: the goal is to measure the
effect of optimizer/query-engine changes on realistic scan work.
+The Prometheus remote-write cases are end-to-end regression coverage for the
+automatic write, flush, SST, and query path. They do not replace controlled
+encoding experiments that explicitly compare `plain`/dictionary,
+`no_dictionary`, BYTE_STREAM_SPLIT, or Auto policies.
+
## Phase 1: direct readable SST fixtures
Phase 1 should generate data by writing readable Mito SST files and matching
@@ -40,8 +45,10 @@ The runner also supports `scenario.kind = "prom_remote_write_then_query"` for a
bounded write-path smoke/regression flow. This path is explicit and separate from
the direct-SST fixture path: it starts the base and candidate distributed clusters,
writes deterministic Prometheus remote-write v1 samples through
-`/v1/prometheus/write`, flushes the configured physical metric table, then runs
-the configured SQL/TQL queries against the logical metric table.
+`/v1/prometheus/write`, flushes the configured physical metric table, checks
+visibility, runs the configured SQL/TQL queries, stops and awaits the datanode,
+then optionally inspects the landed SST/Parquet footer, encoding, and size and
+runs the read-bench against the quiescent data directory.
Remote-write cases configure one database, one logical metric, and one physical
table under `[scenario.remote_write]`:
@@ -52,34 +59,121 @@ kind = "prom_remote_write_then_query"
[scenario.remote_write]
database = "public"
-metric = "prom_remote_write_smoke"
+metric = "prom_remote_write_seeded_random"
physical_table = "greptime_physical_table"
-series_count = 8
-samples_per_series = 30
+series_count = 512
+samples_per_series = 1440
+sample_chunk_size = 480
+flush_every_sample_chunks = 1
start_unix_millis = 1_704_067_200_000
-step_millis = 15_000
-chunk_series_count = 4
-visibility_timeout_seconds = 30
+step_millis = 60_000
+chunk_series_count = 128
+timeout_seconds = 180
+visibility_timeout_seconds = 120
# Optional: split by time so each helper invocation writes only this many samples
# per series, then periodically flush the physical metric table to produce
# multiple time-interval SSTs.
-# sample_chunk_size = 300
-# flush_every_sample_chunks = 1
[scenario.remote_write.prom_store]
pending_rows_flush_interval = "1s"
+max_batch_rows = 100000
```
+Cases can optionally add `[scenario.remote_write.value]` to control the generated
+sample values without changing label cardinality or the runner lifecycle:
+
+```toml
+[scenario.remote_write.value]
+pattern = "quantized_signal" # linear, constant, modulo, unique, seeded_random,
+ # run_length, quantized_signal,
+ # signal_with_sporadic_stalls, mixed_signal_repeated
+base = 0.0
+step = 0.125
+cardinality = 4096 # buckets for modulo/seeded_random/quantized_signal/run_length
+seed = 12345 # deterministic seeded_random input
+run_length = 8 # adjacent samples per bucket for run_length/quantized_signal
+stall_every = 100 # interval for signal_with_sporadic_stalls
+stall_length = 16 # held samples inside each stall interval
+mixed_every = 5 # every Nth sample becomes the repeated base value
+```
+
+The default `linear` pattern preserves the helper's historical formula. Use
+`constant` or low-cardinality `modulo`/`seeded_random` values for repeated-value
+data shapes, `run_length` for run-heavy low-cardinality series, `quantized_signal`
+for signal-like values collapsed into a finite bucket set, `signal_with_sporadic_stalls`
+for mostly continuous signals with periodic flat spots, and `mixed_signal_repeated`
+for signal-plus-periodic-default mixtures. `unique` or high-cardinality buckets
+still work for broad sample-value distributions. This is a generic sample-value
+control for query/ingestion cases; it does not inspect or assert storage
+encoding, Parquet footers, or storage policy choices. For chunked remote-write
+ingestion, the runner passes the sample offset and total sample count to the
+helper so non-linear value patterns use a stable global/per-series ordinal across
+chunks.
+
+Case schema, value distribution defaults, storage defaults, and read-bench
+defaults are owned by Rust. The Python runner calls
+`query_perf_fixture plan --case ` and orchestrates the normalized JSON.
+The same helper exposes `direct-sst`, `prom-remote-write`, and `inspect-footer`
+subcommands; the old direct invocation (`query_perf_fixture --case ... --out-dir
+...`) remains compatible.
+
+Remote-write cases that need to validate storage output can add
+`[scenario.remote_write.storage]`. When present, the scenario body becomes:
+remote-write → flush → visibility check → query measurement → stop and await
+datanode → Parquet footer/size/encoding inspection → optional read-bench. Footer
+inspection is handled by `query_perf_fixture inspect-footer`, which reads local
+Parquet footers directly; it does not require Python `pyarrow`.
+
+```toml
+[scenario.remote_write.storage]
+inspect = true
+column = "greptime_value"
+include_metadata_files = false
+# Optional: inspect below datanode data home instead of the whole fresh data dir.
+# root_suffix = "greptime/public/"
+min_files = 1
+min_files_with_column = 1
+require_encodings = ["BYTE_STREAM_SPLIT"]
+forbid_encodings = ["PLAIN_DICTIONARY"]
+max_total_file_size_bytes = 104857600
+max_column_compressed_size_bytes = 52428800
+max_column_uncompressed_size_bytes = 209715200
+max_candidate_total_file_size_regression_pct = 10.0
+max_candidate_column_compressed_size_regression_pct = 10.0
+max_candidate_column_uncompressed_size_regression_pct = 10.0
+```
+
+The `*_pct` storage thresholds are percent regression limits comparing candidate
+against base; `pct` means percent, not percentile. Per-target storage checks
+(`min_files`, `min_files_with_column`, required/forbidden encodings, and absolute
+`max_*_bytes`) run for both base and candidate. Comparative
+`max_candidate_*_regression_pct` checks remain base-vs-candidate. These checks
+are generic footer and byte-size assertions and do not encode product-specific
+heuristics. When storage inspection is enabled, `min_files` and
+`min_files_with_column` default to `1` even if omitted, so dry-runs show these
+planned checks and an empty flush or missing target column fails the scenario.
+By default the inspector root is the target datanode data home, which is suitable
+for a fresh single-case data directory. For reused or more complex data homes, set
+`root_suffix` to a path relative to the datanode data home to narrow inspection.
+
+When storage inspection is enabled, `[scenario.remote_write.read_bench]` defaults
+to enabled with both datanode `parquetbench` and `scanbench`. Disable it with
+`enabled = false`. `parquetbench` measures per-SST reader cost, `scanbench`
+measures region scan cost, and query measurements still exercise the SQL/TQL
+frontend path. Treat all performance conclusions as release-only; debug builds
+are suitable only for command wiring and correctness checks.
+
The runner creates the configured database if needed, writes a per-target
frontend config enabling `[prom_store]` with metric engine storage and a non-zero
`pending_rows_flush_interval`, and validates that the logical metric table reaches
`series_count * samples_per_series` rows before trusting the query measurements.
-Use `--remote-write-generator /path/to/prom_remote_write_fixture` to provide the
-Rust payload helper. `--fixture-only` is rejected for remote-write cases; use
-`--dry-run` for planning.
+Use `--fixture-generator /path/to/query_perf_fixture` to provide the Rust helper.
+Deprecated `--remote-write-generator` and `--storage-inspector` options are kept
+only for CLI compatibility. `--fixture-only` is rejected for remote-write cases;
+use `--dry-run` for planning.
Large manual remote-write cases can set `sample_chunk_size` to split ingestion by
-time. For each chunk, the runner invokes `prom_remote_write_fixture` with the
+time. For each chunk, the runner invokes `query_perf_fixture prom-remote-write` with the
same series cardinality but a shorter `--samples-per-series` and an advanced
`--start-unix-millis`. `flush_every_sample_chunks` controls periodic
`ADMIN FLUSH_TABLE('')` calls; with `flush_every_sample_chunks = 1`,
@@ -89,6 +183,25 @@ need multi-window file distribution should span multiple compaction windows. If
`sample_chunk_size` is omitted, the runner keeps the older single-helper-invocation
behavior and flushes once at the end.
+The default remote-write coverage set contains four cases with the same 2048
+series × 14,400 samples (29,491,200 rows per target) shape. Each writes ten
+one-day chunks, flushes every chunk, requires at least two visible SSTs with the
+value column, runs seven read-bench iterations with `parquetbench` capped at
+four SSTs while `scanbench` covers the landed region, and measures one ten-day
+TQL selector with two warmups and 15 iterations:
+
+- `prom_remote_write_seeded_random`: high-distinct seeded-random values with
+ cardinality 29,491,200 and seed 8444.
+- `prom_remote_write_run_heavy`: low-cardinality values in exact 16-sample runs.
+- `prom_remote_write_mixed_every`: continuous signal values with every fifth
+ sample repeated at the base value.
+- `prom_remote_write_integer_counter`: strictly increasing integer counter
+ values, with disjoint ranges for each series.
+
+These cases record normal storage/footer and read-bench results but do not gate
+specific value encodings or storage-size outcomes. Use the controlled encoding
+experiment matrix for those policy comparisons.
+
`tests/perf/query_cases/prom_remote_write_7913/case.toml` is a larger manual
case for issue #7913. It writes 8192 series × 20160 samples through remote-write
in 1440-sample daily time chunks, flushing after each chunk before running 1d/7d/14d
@@ -246,7 +359,8 @@ as a fallback. Manifest files are reflinked or copied, not hardlinked.
Fixture generator smoke test:
```bash
-cargo run -p cmd --bin query_perf_fixture -- \
+cargo run -p cmd --bin query_perf_fixture --features dev-tools -- \
+ direct-sst \
--case tests/perf/query_cases/smoke_direct_sst/case.toml \
--out-dir /tmp/query-perf-smoke
```
@@ -271,10 +385,10 @@ Remote-write runner dry-run:
```bash
uv run --no-project python tests/perf/query_regression_runner.py \
- --case tests/perf/query_cases/prom_remote_write_smoke/case.toml \
+ --case tests/perf/query_cases/prom_remote_write_seeded_random/case.toml \
--base-bin /path/to/base/greptime \
--candidate-bin /path/to/candidate/greptime \
- --remote-write-generator /path/to/prom_remote_write_fixture \
+ --fixture-generator /path/to/query_perf_fixture \
--work-dir /tmp/query-perf-remote-write \
--dry-run
```
@@ -289,14 +403,22 @@ query regression runs. It builds its own binaries for now:
candidate checkout
- runner and summary formatter from the candidate checkout
-The workflow runs automatically only for non-draft PRs labeled
-`query-regression` (on label/ready-for-review/reopen events, not every push).
+The workflow builds base and candidate `greptime` as normal release-equivalent
+binaries. Candidate `query_perf_fixture` is the extra head-side helper binary;
+the runner uses candidate `greptime datanode parquetbench/scanbench` as the
+read-bench tool against each target's data directory.
+
+The workflow runs automatically only when `query-regression` is added to a
+non-draft PR; it does not rerun on pushes, ready-for-review, or reopen events.
PR runs build base/candidate once and then run the default case set with
`--allow-large-fixture`. Manual `workflow_dispatch` runs can pass `all`, one case
path, or a comma/whitespace-separated list of case paths, and can override refs.
-It always uploads `query-regression-work/**` and `query-regression-summary.md`,
-writes the Markdown summary to the workflow step summary, and updates a sticky PR
-comment through the trusted follow-up workflow.
+The main report artifact uploads only aggregate/per-target JSON reports,
+component logs, and `query-regression-summary.md` with seven-day retention;
+fixture data, SSTs, and cluster state are excluded. PR runs also upload a
+separate trusted-comment artifact containing PR metadata and aggregate reports.
+The workflow writes the Markdown summary to the workflow step summary and
+updates a sticky PR comment through the trusted follow-up workflow.
## Built-in cases
diff --git a/tests/perf/query_cases/prom_remote_write_integer_counter/case.toml b/tests/perf/query_cases/prom_remote_write_integer_counter/case.toml
new file mode 100644
index 00000000000..3ac64a94b9d
--- /dev/null
+++ b/tests/perf/query_cases/prom_remote_write_integer_counter/case.toml
@@ -0,0 +1,48 @@
+[case]
+name = "prom_remote_write_integer_counter"
+description = "End-to-end Prometheus remote-write regression with strictly increasing integer counter values"
+
+[scenario]
+kind = "prom_remote_write_then_query"
+
+[scenario.remote_write]
+database = "public"
+metric = "prom_remote_write_integer_counter"
+physical_table = "greptime_physical_table"
+series_count = 2048
+samples_per_series = 14400
+sample_chunk_size = 1440
+flush_every_sample_chunks = 1
+start_unix_millis = 1704067200000
+step_millis = 60000
+chunk_series_count = 256
+timeout_seconds = 600
+visibility_timeout_seconds = 300
+
+[scenario.remote_write.value]
+pattern = "unique"
+base = 0
+step = 1
+
+[scenario.remote_write.prom_store]
+pending_rows_flush_interval = "1s"
+max_batch_rows = 100000
+
+[scenario.remote_write.storage]
+column = "greptime_value"
+min_files = 2
+min_files_with_column = 2
+
+[scenario.remote_write.read_bench]
+iterations = 7
+max_files = 4
+
+[[scenario.queries]]
+name = "selector_10d_integer_counter"
+kind = "tql"
+query = "TQL ANALYZE VERBOSE (1704067200, 1704931200, '1h') prom_remote_write_integer_counter{host=~'host.*'}"
+warmup = 2
+iterations = 15
+
+[scenario.queries.thresholds]
+max_candidate_latency_regression_pct = 75
diff --git a/tests/perf/query_cases/prom_remote_write_mixed_every/case.toml b/tests/perf/query_cases/prom_remote_write_mixed_every/case.toml
new file mode 100644
index 00000000000..9ba39f2fbed
--- /dev/null
+++ b/tests/perf/query_cases/prom_remote_write_mixed_every/case.toml
@@ -0,0 +1,49 @@
+[case]
+name = "prom_remote_write_mixed_every"
+description = "End-to-end Prometheus remote-write regression with periodic repeated signal values"
+
+[scenario]
+kind = "prom_remote_write_then_query"
+
+[scenario.remote_write]
+database = "public"
+metric = "prom_remote_write_mixed_every"
+physical_table = "greptime_physical_table"
+series_count = 2048
+samples_per_series = 14400
+sample_chunk_size = 1440
+flush_every_sample_chunks = 1
+start_unix_millis = 1704067200000
+step_millis = 60000
+chunk_series_count = 256
+timeout_seconds = 600
+visibility_timeout_seconds = 300
+
+[scenario.remote_write.value]
+pattern = "mixed_signal_repeated"
+base = 0
+step = 0.125
+mixed_every = 5
+
+[scenario.remote_write.prom_store]
+pending_rows_flush_interval = "1s"
+max_batch_rows = 100000
+
+[scenario.remote_write.storage]
+column = "greptime_value"
+min_files = 2
+min_files_with_column = 2
+
+[scenario.remote_write.read_bench]
+iterations = 7
+max_files = 4
+
+[[scenario.queries]]
+name = "selector_10d_mixed_every"
+kind = "tql"
+query = "TQL ANALYZE VERBOSE (1704067200, 1704931200, '1h') prom_remote_write_mixed_every{host=~'host.*'}"
+warmup = 2
+iterations = 15
+
+[scenario.queries.thresholds]
+max_candidate_latency_regression_pct = 75
diff --git a/tests/perf/query_cases/prom_remote_write_run_heavy/case.toml b/tests/perf/query_cases/prom_remote_write_run_heavy/case.toml
new file mode 100644
index 00000000000..243892e42b1
--- /dev/null
+++ b/tests/perf/query_cases/prom_remote_write_run_heavy/case.toml
@@ -0,0 +1,50 @@
+[case]
+name = "prom_remote_write_run_heavy"
+description = "End-to-end Prometheus remote-write regression with repeated 16-sample value runs"
+
+[scenario]
+kind = "prom_remote_write_then_query"
+
+[scenario.remote_write]
+database = "public"
+metric = "prom_remote_write_run_heavy"
+physical_table = "greptime_physical_table"
+series_count = 2048
+samples_per_series = 14400
+sample_chunk_size = 1440
+flush_every_sample_chunks = 1
+start_unix_millis = 1704067200000
+step_millis = 60000
+chunk_series_count = 256
+timeout_seconds = 600
+visibility_timeout_seconds = 300
+
+[scenario.remote_write.value]
+pattern = "run_length"
+base = 0
+step = 1
+cardinality = 1024
+run_length = 16
+
+[scenario.remote_write.prom_store]
+pending_rows_flush_interval = "1s"
+max_batch_rows = 100000
+
+[scenario.remote_write.storage]
+column = "greptime_value"
+min_files = 2
+min_files_with_column = 2
+
+[scenario.remote_write.read_bench]
+iterations = 7
+max_files = 4
+
+[[scenario.queries]]
+name = "selector_10d_run_heavy"
+kind = "tql"
+query = "TQL ANALYZE VERBOSE (1704067200, 1704931200, '1h') prom_remote_write_run_heavy{host=~'host.*'}"
+warmup = 2
+iterations = 15
+
+[scenario.queries.thresholds]
+max_candidate_latency_regression_pct = 75
diff --git a/tests/perf/query_cases/prom_remote_write_seeded_random/case.toml b/tests/perf/query_cases/prom_remote_write_seeded_random/case.toml
new file mode 100644
index 00000000000..6a63edbcbbf
--- /dev/null
+++ b/tests/perf/query_cases/prom_remote_write_seeded_random/case.toml
@@ -0,0 +1,48 @@
+[case]
+name = "prom_remote_write_seeded_random"
+description = "End-to-end Prometheus remote-write regression with high-distinct seeded-random values"
+
+[scenario]
+kind = "prom_remote_write_then_query"
+
+[scenario.remote_write]
+database = "public"
+metric = "prom_remote_write_seeded_random"
+physical_table = "greptime_physical_table"
+series_count = 2048
+samples_per_series = 14400
+sample_chunk_size = 1440
+flush_every_sample_chunks = 1
+start_unix_millis = 1704067200000
+step_millis = 60000
+chunk_series_count = 256
+timeout_seconds = 600
+visibility_timeout_seconds = 300
+
+[scenario.remote_write.value]
+pattern = "seeded_random"
+cardinality = 29_491_200
+seed = 8444
+
+[scenario.remote_write.prom_store]
+pending_rows_flush_interval = "1s"
+max_batch_rows = 100000
+
+[scenario.remote_write.storage]
+column = "greptime_value"
+min_files = 2
+min_files_with_column = 2
+
+[scenario.remote_write.read_bench]
+iterations = 7
+max_files = 4
+
+[[scenario.queries]]
+name = "selector_10d_seeded_random"
+kind = "tql"
+query = "TQL ANALYZE VERBOSE (1704067200, 1704931200, '1h') prom_remote_write_seeded_random{host=~'host.*'}"
+warmup = 2
+iterations = 15
+
+[scenario.queries.thresholds]
+max_candidate_latency_regression_pct = 75
diff --git a/tests/perf/query_cases/prom_remote_write_smoke/case.toml b/tests/perf/query_cases/prom_remote_write_smoke/case.toml
deleted file mode 100644
index b946fbc8f51..00000000000
--- a/tests/perf/query_cases/prom_remote_write_smoke/case.toml
+++ /dev/null
@@ -1,31 +0,0 @@
-[case]
-name = "prom_remote_write_smoke"
-description = "Tiny Prometheus remote-write ingestion then TQL query smoke case"
-
-[scenario]
-kind = "prom_remote_write_then_query"
-
-[scenario.remote_write]
-database = "public"
-metric = "prom_remote_write_smoke"
-physical_table = "greptime_physical_table"
-series_count = 8
-samples_per_series = 30
-start_unix_millis = 1_704_067_200_000
-step_millis = 15_000
-chunk_series_count = 4
-timeout_seconds = 30
-
-[scenario.remote_write.prom_store]
-pending_rows_flush_interval = "1s"
-max_batch_rows = 10000
-
-[[scenario.queries]]
-name = "selector_5m_smoke"
-kind = "tql"
-query = "TQL ANALYZE VERBOSE (1704067200, 1704067650, '15s') prom_remote_write_smoke{host=~'host.*'}"
-warmup = 0
-iterations = 2
-
-[scenario.queries.thresholds]
-max_candidate_latency_regression_pct = 100
diff --git a/tests/perf/query_regression_runner.py b/tests/perf/query_regression_runner.py
index a7f2646ea8b..f5c9628b83d 100644
--- a/tests/perf/query_regression_runner.py
+++ b/tests/perf/query_regression_runner.py
@@ -66,7 +66,8 @@ def parse_args() -> argparse.Namespace:
p.add_argument("--base-bin", required=True, type=Path)
p.add_argument("--candidate-bin", required=True, type=Path)
p.add_argument("--fixture-generator", type=Path)
- p.add_argument("--remote-write-generator", type=Path, help="prom_remote_write_fixture helper binary")
+ p.add_argument("--remote-write-generator", type=Path, help="deprecated: use --fixture-generator query_perf_fixture")
+ p.add_argument("--storage-inspector", type=Path, help="deprecated: use --fixture-generator query_perf_fixture")
p.add_argument("--work-dir", required=True, type=Path)
p.add_argument("--fixture-cache-dir", type=Path, help="persistent directory for generated fixtures, keyed by case content")
p.add_argument("--reuse-fixture", action="store_true")
@@ -83,6 +84,16 @@ def load_case(path: Path) -> dict[str, Any]:
return tomllib.load(f)
+def load_normalized_case(case_path: Path, fixture_generator: Path | None) -> dict[str, Any]:
+ if fixture_generator is None:
+ raise ValueError("--fixture-generator query_perf_fixture is required for Rust-owned case planning")
+ result = run_command([str(fixture_generator), "plan", "--case", str(case_path)])
+ if result["returncode"] != 0:
+ raise RuntimeError(f"query_perf_fixture plan failed: {result['stderr'][:2000]}")
+ plan = json.loads(result["stdout"])
+ return {"case": load_case(case_path).get("case", {}), "scenario": plan["scenario"], "schema_version": plan.get("schema_version")}
+
+
def require_binary(path: Path, name: str, *, dry_run: bool) -> None:
if dry_run:
return
@@ -157,11 +168,9 @@ def scenario(case: dict[str, Any]) -> dict[str, Any]:
def case_tables(case: dict[str, Any]) -> list[dict[str, Any]]:
value = scenario(case)
if value.get("kind") == "prom_remote_write_then_query":
- remote = value.get("remote_write") or {}
- metric = remote.get("metric") or remote.get("metric_name")
- database = remote.get("database", "public")
- if not metric:
- raise ValueError("remote-write scenario requires scenario.remote_write.metric")
+ remote = value["remote_write"]
+ metric = remote["metric"]
+ database = remote["database"]
return [{"database": database, "name": metric, "engine": "metric", "validate_show_create_engine": False}]
tables = value.get("tables") or []
if not tables or value.get("layout", {}).get("regions") != 1:
@@ -548,7 +557,7 @@ def generate_fixture(generator: Path | None, case_path: Path, fixture_dir: Path,
if fixture_dir.exists() and not reuse_fixture:
shutil.rmtree(fixture_dir)
fixture_dir.mkdir(parents=True, exist_ok=True)
- cmd = [str(generator), "--case", str(case_path), "--out-dir", str(fixture_dir)]
+ cmd = [str(generator), "direct-sst", "--case", str(case_path), "--out-dir", str(fixture_dir)]
if table_name is not None:
cmd += ["--table", table_name]
if region_id is not None:
@@ -777,6 +786,243 @@ def enforce_thresholds(case: dict[str, Any], base: dict[str, Any], candidate: di
return results
+def storage_config(remote: dict[str, Any]) -> dict[str, Any] | None:
+ value = remote["storage"]
+ if not isinstance(value, dict):
+ return None
+ if value["inspect"] is False:
+ return None
+ return value
+
+
+def run_storage_inspection(helper: Path | None, target: RunTarget, storage: dict[str, Any], *, dry_run: bool) -> dict[str, Any]:
+ if helper is None:
+ if not dry_run:
+ raise ValueError("--fixture-generator query_perf_fixture is required when storage inspection is enabled")
+ helper = Path("query_perf_fixture")
+ root = target.datanode_data_dir
+ if storage.get("root_suffix"):
+ root = root / str(storage["root_suffix"])
+ cmd = [
+ str(helper),
+ "inspect-footer",
+ "--root", str(root),
+ "--column", str(storage["column"]),
+ ]
+ if storage["include_metadata_files"]:
+ cmd.append("--include-metadata-files")
+ if dry_run:
+ return {"status": "dry-run", "cmd": cmd, "root": str(root)}
+ result = run_command(cmd)
+ result["status"] = "ok" if result["returncode"] == 0 else "failed"
+ if result["returncode"] != 0:
+ raise RuntimeError(f"storage inspector failed for {target.name}: {result['stderr'][:2000]}")
+ try:
+ result["summary"] = json.loads(result["stdout"])
+ except json.JSONDecodeError:
+ result["summary_parse_error"] = result["stdout"]
+ result["status"] = "failed"
+ return result
+
+
+def storage_summary(inspection: dict[str, Any]) -> dict[str, Any]:
+ summary = inspection.get("summary")
+ if isinstance(summary, dict):
+ nested = summary.get("summary")
+ if isinstance(nested, dict):
+ return nested
+ return {}
+
+
+def enforce_storage_thresholds(storage: dict[str, Any] | None, base: dict[str, Any] | None, candidate: dict[str, Any] | None) -> list[dict[str, Any]]:
+ if not storage:
+ return []
+ results: list[dict[str, Any]] = []
+ target_summaries = [("base", storage_summary(base or {})), ("candidate", storage_summary(candidate or {}))]
+ cand = target_summaries[1][1]
+ base_summary = storage_summary(base or {})
+
+ def add_abs(name: str, field: str) -> None:
+ limit = storage.get(name)
+ if limit is None:
+ return
+ for target_name, summary in target_summaries:
+ actual = summary.get(field)
+ ok = actual is not None and float(actual) <= float(limit)
+ results.append({"target": target_name, "threshold": name, "status": "passed" if ok else "failed", "actual": actual, "limit": limit})
+
+ def add_min(name: str, field: str) -> None:
+ limit = storage[name]
+ if limit is None:
+ return
+ for target_name, summary in target_summaries:
+ actual = summary.get(field)
+ ok = actual is not None and int(actual) >= int(limit)
+ results.append({"target": target_name, "threshold": name, "status": "passed" if ok else "failed", "actual": actual, "limit": limit})
+
+ def add_cmp(name: str, field: str) -> None:
+ limit = storage.get(name)
+ if limit is None:
+ return
+ base_value = base_summary.get(field)
+ candidate_value = cand.get(field)
+ if base_value in (None, 0) or candidate_value is None:
+ results.append({"threshold": name, "status": "failed", "reason": "missing or zero base/candidate value", "base": base_value, "candidate": candidate_value})
+ return
+ actual = (float(candidate_value) - float(base_value)) / float(base_value) * 100.0
+ results.append({"threshold": name, "status": "passed" if actual <= float(limit) else "failed", "actual_pct": actual, "limit_pct": limit, "base": base_value, "candidate": candidate_value})
+
+ add_min("min_files", "file_count")
+ add_min("min_files_with_column", "files_with_column")
+ add_abs("max_total_file_size_bytes", "total_file_size")
+ add_abs("max_column_compressed_size_bytes", "column_compressed_size")
+ add_abs("max_column_uncompressed_size_bytes", "column_uncompressed_size")
+ for target_name, summary in target_summaries:
+ encodings = set(summary.get("unique_encodings") or [])
+ for required in storage["require_encodings"]:
+ results.append({"target": target_name, "threshold": "require_encodings", "encoding": required, "status": "passed" if required in encodings else "failed"})
+ for forbidden in storage["forbid_encodings"]:
+ results.append({"target": target_name, "threshold": "forbid_encodings", "encoding": forbidden, "status": "passed" if forbidden not in encodings else "failed"})
+ add_cmp("max_candidate_total_file_size_regression_pct", "total_file_size")
+ add_cmp("max_candidate_column_compressed_size_regression_pct", "column_compressed_size")
+ add_cmp("max_candidate_column_uncompressed_size_regression_pct", "column_uncompressed_size")
+ return results
+
+
+def planned_storage_thresholds(storage: dict[str, Any] | None) -> list[dict[str, Any]]:
+ if not storage:
+ return []
+ return list(storage["planned_thresholds"])
+
+
+REGION_DIR_RE = re.compile(r"^(\d+)_(\d{10})$")
+
+
+def inspection_report(inspection: dict[str, Any] | None) -> dict[str, Any]:
+ if not inspection:
+ return {}
+ report = inspection.get("summary")
+ return report if isinstance(report, dict) else {}
+
+
+def inspected_relative_path(target: RunTarget, inspection: dict[str, Any], relative_path: str) -> Path:
+ report = inspection_report(inspection)
+ root_text = report.get("root") or inspection.get("root")
+ if not root_text:
+ return Path(relative_path)
+ root = Path(root_text).resolve(strict=False)
+ data_home = target.datanode_data_dir.resolve(strict=False)
+ try:
+ root_suffix = root.relative_to(data_home)
+ except ValueError as e:
+ raise RuntimeError(f"storage inspection root {root} is not under datanode data home {data_home}") from e
+ return root_suffix / relative_path
+
+
+def parse_sst_bench_target(target: RunTarget, inspection: dict[str, Any], file: dict[str, Any], *, dry_run: bool) -> dict[str, str] | None:
+ relative_path = str(file.get("relative_path") or "")
+ if dry_run and (not relative_path or "<" in relative_path):
+ return {
+ "relative_path": relative_path or "/_/data/.parquet",
+ "table_dir": "/",
+ "region_id": ":",
+ "path_type": "data",
+ "file_id": "",
+ }
+ if not relative_path:
+ return None
+ full_relative = inspected_relative_path(target, inspection, relative_path)
+ parts = full_relative.parts
+ if not parts or not parts[-1].endswith(".parquet"):
+ return None
+ region_index = next((idx for idx, part in enumerate(parts) if REGION_DIR_RE.match(part)), None)
+ if region_index is None or region_index == 0:
+ if dry_run:
+ return {
+ "relative_path": relative_path,
+ "table_dir": "/",
+ "region_id": ":",
+ "path_type": "data",
+ "file_id": Path(parts[-1]).stem,
+ }
+ return None
+ region_match = REGION_DIR_RE.match(parts[region_index])
+ assert region_match is not None
+ file_index = len(parts) - 1
+ path_type = "bare"
+ if region_index + 1 < file_index and parts[region_index + 1] in ("data", "metadata"):
+ path_type = parts[region_index + 1]
+ if path_type == "metadata":
+ return None
+ table_dir = "/".join(parts[:region_index]).rstrip("/") + "/"
+ return {
+ "relative_path": str(full_relative),
+ "table_dir": table_dir,
+ "region_id": f"{int(region_match.group(1))}:{int(region_match.group(2))}",
+ "path_type": path_type,
+ "file_id": Path(parts[-1]).stem,
+ }
+
+
+def run_read_bench(bench_binary: Path, target: RunTarget, read_bench: dict[str, Any] | None, storage_inspection: dict[str, Any] | None, *, dry_run: bool) -> dict[str, Any]:
+ if not read_bench or read_bench["enabled"] is False:
+ return {"status": "skipped", "reason": "read_bench disabled"}
+ run_parquetbench = read_bench["parquetbench"]
+ run_scanbench = read_bench["scanbench"]
+ if not run_parquetbench and not run_scanbench:
+ return {"status": "skipped", "reason": "parquetbench and scanbench disabled"}
+ if storage_inspection is None:
+ raise ValueError("read_bench requires storage inspection")
+ bench_dir = target.work_dir / "read_bench"
+ config_toml = bench_dir / "bench.toml"
+ scan_json = bench_dir / "scan.json"
+ files = inspection_report(storage_inspection).get("files") or []
+ ssts = [f for f in files if f.get("relative_path", "").endswith(".parquet") and f.get("columns")]
+ if dry_run and not ssts:
+ ssts = [{"relative_path": ".parquet"}]
+ if read_bench["max_files"] is not None:
+ ssts = ssts[: int(read_bench["max_files"])]
+ bench_targets = [parsed for f in ssts if (parsed := parse_sst_bench_target(target, storage_inspection, f, dry_run=dry_run)) is not None]
+ if not bench_targets:
+ return {"status": "failed", "reason": "no inspected data SST files available for read_bench"}
+ config_text = f'[storage]\ndata_home = "{target.datanode_data_dir}"\ntype = "File"\n\n[[region_engine]]\n[region_engine.mito]\n'
+ commands = []
+ parquet_runs = []
+ scan_runs = []
+ iterations = str(int(read_bench["iterations"]))
+ if run_parquetbench:
+ for bench_target in bench_targets:
+ cmd = [str(bench_binary), "datanode", "parquetbench", "--config", str(config_toml), "--region-id", bench_target["region_id"], "--table-dir", bench_target["table_dir"], "--file-id", bench_target["file_id"], "--scan-config", str(scan_json), "--path-type", bench_target["path_type"], "--iterations", iterations, "--reader", str(read_bench["parquet_reader"])]
+ commands.append(cmd)
+ parquet_runs.append({**bench_target, "cmd": cmd, "status": "dry-run" if dry_run else "planned"})
+ regions: dict[tuple[str, str, str], list[str]] = {}
+ if run_scanbench:
+ for bench_target in bench_targets:
+ regions.setdefault((bench_target["table_dir"], bench_target["region_id"], bench_target["path_type"]), []).append(bench_target["relative_path"])
+ for (table_dir, region_id, path_type), region_files in regions.items():
+ cmd = [str(bench_binary), "datanode", "scanbench", "--config", str(config_toml), "--region-id", region_id, "--table-dir", table_dir, "--scan-config", str(scan_json), "--path-type", path_type, "--scanner", str(read_bench["scan_scanner"]), "--parallelism", str(int(read_bench["parallelism"])), "--iterations", iterations]
+ commands.append(cmd)
+ scan_runs.append({"table_dir": table_dir, "region_id": region_id, "path_type": path_type, "files": region_files, "cmd": cmd, "status": "dry-run" if dry_run else "planned"})
+ if dry_run:
+ return {"status": "dry-run", "config_path": str(config_toml), "scan_config_path": str(scan_json), "commands": commands, "parquetbench": parquet_runs, "scanbench": scan_runs}
+ bench_dir.mkdir(parents=True, exist_ok=True)
+ config_toml.write_text(config_text)
+ scan_json.write_text(json.dumps({"projection_names": read_bench["projection"]}, indent=2) + "\n")
+ avg_re = re.compile(r"Average duration[^0-9]*([0-9.]+)\s*ms", re.I)
+ for runs in (parquet_runs, scan_runs):
+ for run in runs:
+ result = run_command(run["cmd"])
+ run.update(result)
+ run["status"] = "ok" if result["returncode"] == 0 else "failed"
+ m = avg_re.search(result.get("stdout", ""))
+ if m:
+ run["average_ms"] = float(m.group(1))
+ def median(runs: list[dict[str, Any]]) -> float | None:
+ vals = [r["average_ms"] for r in runs if "average_ms" in r]
+ return statistics.median(vals) if vals else None
+ return {"status": "ok" if all(r.get("status") == "ok" for r in parquet_runs + scan_runs) else "failed", "config_path": str(config_toml), "scan_config_path": str(scan_json), "parquetbench": parquet_runs, "scanbench": scan_runs, "aggregate": {"parquetbench_median_average_ms": median(parquet_runs), "scanbench_median_average_ms": median(scan_runs)}}
+
+
def write_json(path: Path, payload: dict[str, Any]) -> None:
path.parent.mkdir(parents=True, exist_ok=True)
path.write_text(json.dumps(payload, indent=2, sort_keys=True) + "\n")
@@ -791,18 +1037,18 @@ def require_fresh_work_dirs(targets: list[RunTarget], *, reuse_work_dir: bool, d
def write_frontend_prom_config(target: RunTarget, remote: dict[str, Any]) -> Path:
- prom = remote.get("prom_store") or {}
+ prom = remote["prom_store"]
path = target.work_dir / "frontend-prom-store.toml"
path.parent.mkdir(parents=True, exist_ok=True)
path.write_text(
"[prom_store]\n"
"enable = true\n"
"with_metric_engine = true\n"
- f"pending_rows_flush_interval = {json.dumps(str(prom.get('pending_rows_flush_interval', '1s')))}\n"
- f"max_batch_rows = {int(prom.get('max_batch_rows', 100000))}\n"
- f"max_concurrent_flushes = {int(prom.get('max_concurrent_flushes', 256))}\n"
- f"worker_channel_capacity = {int(prom.get('worker_channel_capacity', 65526))}\n"
- f"max_inflight_requests = {int(prom.get('max_inflight_requests', 3000))}\n"
+ f"pending_rows_flush_interval = {json.dumps(str(prom['pending_rows_flush_interval']))}\n"
+ f"max_batch_rows = {int(prom['max_batch_rows'])}\n"
+ f"max_concurrent_flushes = {int(prom['max_concurrent_flushes'])}\n"
+ f"worker_channel_capacity = {int(prom['worker_channel_capacity'])}\n"
+ f"max_inflight_requests = {int(prom['max_inflight_requests'])}\n"
)
return path
@@ -810,23 +1056,38 @@ def write_frontend_prom_config(target: RunTarget, remote: dict[str, Any]) -> Pat
def run_remote_write(generator: Path | None, target: RunTarget, remote: dict[str, Any], *, dry_run: bool) -> dict[str, Any]:
if generator is None:
if not dry_run:
- raise ValueError("--remote-write-generator is required for prom_remote_write_then_query unless --dry-run is set")
- generator = Path("prom_remote_write_fixture")
- metric = remote.get("metric") or remote.get("metric_name")
- physical_table = remote.get("physical_table", "greptime_physical_table")
+ raise ValueError("--fixture-generator query_perf_fixture is required for prom_remote_write_then_query")
+ generator = Path("query_perf_fixture")
+ metric = remote["metric"]
+ physical_table = remote["physical_table"]
cmd = [
str(generator),
+ "prom-remote-write",
"--endpoint", f"http://127.0.0.1:{target.http_port}/v1/prometheus/write",
- "--database", remote.get("database", "public"),
+ "--database", remote["database"],
"--metric", metric,
"--physical-table", physical_table,
- "--series-count", str(int(remote.get("series_count", 8))),
- "--samples-per-series", str(int(remote.get("samples_per_series", 30))),
- "--start-unix-millis", str(int(remote.get("start_unix_millis", 1_704_067_200_000))),
- "--step-millis", str(int(remote.get("step_millis", 15_000))),
- "--chunk-series-count", str(int(remote.get("chunk_series_count", remote.get("batch_size", 8)))),
- "--timeout-seconds", str(int(remote.get("timeout_seconds", 60))),
+ "--series-count", str(int(remote["series_count"])),
+ "--samples-per-series", str(int(remote["samples_per_series"])),
+ "--start-unix-millis", str(int(remote["start_unix_millis"])),
+ "--step-millis", str(int(remote["step_millis"])),
+ "--chunk-series-count", str(int(remote["chunk_series_count"])),
+ "--timeout-seconds", str(int(remote["timeout_seconds"])),
]
+ value = remote["value"]
+ cmd.extend(["--value-pattern", str(value["pattern"])])
+ cmd.extend(["--value-base", str(value["base"])])
+ cmd.extend(["--value-step", str(value["step"])])
+ cmd.extend(["--value-cardinality", str(int(value["cardinality"]))])
+ cmd.extend(["--value-seed", str(int(value["seed"]))])
+ cmd.extend(["--value-run-length", str(int(value["run_length"]))])
+ cmd.extend(["--value-stall-every", str(int(value["stall_every"]))])
+ cmd.extend(["--value-stall-length", str(int(value["stall_length"]))])
+ cmd.extend(["--value-mixed-every", str(int(value["mixed_every"]))])
+ if "sample_offset" in remote:
+ cmd.extend(["--value-sample-offset", str(int(remote["sample_offset"]))])
+ if "total_samples_per_series" in remote:
+ cmd.extend(["--value-total-samples-per-series", str(int(remote["total_samples_per_series"]))])
if dry_run:
return {"status": "dry-run", "cmd": cmd}
result = run_command(cmd)
@@ -862,23 +1123,23 @@ def flush_remote_physical_table(target: RunTarget, db: str, physical_table: str,
def run_remote_write_ingestion(generator: Path | None, target: RunTarget, remote: dict[str, Any], args: argparse.Namespace, *, dry_run: bool) -> tuple[dict[str, Any], list[dict[str, Any]]]:
- sample_chunk_size = remote.get("sample_chunk_size")
- db = remote.get("database", "public")
- physical_table = remote.get("physical_table", "greptime_physical_table")
+ sample_chunk_size = remote["sample_chunk_size"]
+ db = remote["database"]
+ physical_table = remote["physical_table"]
if sample_chunk_size is None:
rw = run_remote_write(generator, target, remote, dry_run=dry_run)
flush = flush_remote_physical_table(target, db, physical_table, args, dry_run=dry_run, reason="final")
return rw, [flush]
- total_samples = int(remote.get("samples_per_series", 30))
+ total_samples = int(remote["samples_per_series"])
chunk_samples = int(sample_chunk_size)
if chunk_samples <= 0:
raise ValueError("scenario.remote_write.sample_chunk_size must be positive")
- flush_every = int(remote.get("flush_every_sample_chunks", 1))
+ flush_every = int(remote["flush_every_sample_chunks"])
if flush_every <= 0:
raise ValueError("scenario.remote_write.flush_every_sample_chunks must be positive")
- start = int(remote.get("start_unix_millis", 1_704_067_200_000))
- step = int(remote.get("step_millis", 15_000))
+ start = int(remote["start_unix_millis"])
+ step = int(remote["step_millis"])
chunks: list[dict[str, Any]] = []
flushes: list[dict[str, Any]] = []
chunk_index = 0
@@ -889,6 +1150,8 @@ def run_remote_write_ingestion(generator: Path | None, target: RunTarget, remote
chunk_remote = dict(remote)
chunk_remote["samples_per_series"] = current
chunk_remote["start_unix_millis"] = start + offset * step
+ chunk_remote["sample_offset"] = offset
+ chunk_remote["total_samples_per_series"] = total_samples
result = run_remote_write(generator, target, chunk_remote, dry_run=dry_run)
result["sample_offset"] = offset
result["samples_per_series"] = current
@@ -901,8 +1164,8 @@ def run_remote_write_ingestion(generator: Path | None, target: RunTarget, remote
flushes.append(flush_remote_physical_table(target, db, physical_table, args, dry_run=dry_run, reason="final", chunk_index=chunk_index))
aggregate = summarize_remote_write_chunks(chunks)
if dry_run:
- series_count = int(remote.get("series_count", 8))
- chunk_series_count = int(remote.get("chunk_series_count", remote.get("batch_size", 8)))
+ series_count = int(remote["series_count"])
+ chunk_series_count = int(remote["chunk_series_count"])
aggregate["rows"] = series_count * total_samples
aggregate["samples_written"] = aggregate["rows"]
aggregate["batches"] = chunk_index * ((series_count + chunk_series_count - 1) // chunk_series_count)
@@ -917,7 +1180,7 @@ def run_remote_write_ingestion(generator: Path | None, target: RunTarget, remote
def expected_remote_write_rows(remote: dict[str, Any]) -> int:
- return int(remote.get("series_count", 8)) * int(remote.get("samples_per_series", 30))
+ return int(remote["series_count"]) * int(remote["samples_per_series"])
def extract_count_value(result: dict[str, Any]) -> int | None:
@@ -966,16 +1229,21 @@ def poll_expected_count(target: RunTarget, table_name: str, db: str, expected_ro
def run_remote_write_scenario(args: argparse.Namespace, case: dict[str, Any], case_path: Path, targets: list[RunTarget], report: dict[str, Any]) -> None:
- remote = scenario(case).get("remote_write") or {}
+ remote = scenario(case)["remote_write"]
tables = case_tables(case)
if args.fixture_only:
raise ValueError("--fixture-only is not supported for prom_remote_write_then_query; use --dry-run for planning")
- if args.remote_write_generator is not None:
- require_binary(args.remote_write_generator, "remote-write generator", dry_run=args.dry_run)
+ helper = args.fixture_generator or args.remote_write_generator
+ if helper is not None:
+ require_binary(helper, "query_perf_fixture", dry_run=args.dry_run)
elif not args.dry_run:
- raise ValueError("--remote-write-generator is required for prom_remote_write_then_query")
+ raise ValueError("--fixture-generator is required for prom_remote_write_then_query")
+ storage = storage_config(remote)
+ if storage and helper is None and not args.dry_run:
+ raise ValueError("--fixture-generator is required when scenario.remote_write.storage.inspect is enabled")
clusters: list[DistributedCluster] = []
target_results = []
+ storage_results = []
try:
for target in targets:
target.work_dir.mkdir(parents=True, exist_ok=True)
@@ -984,28 +1252,40 @@ def run_remote_write_scenario(args: argparse.Namespace, case: dict[str, Any], ca
clusters.append(cluster)
if not args.dry_run:
cluster.start_all(config_path)
- db = remote.get("database", "public")
+ db = remote["database"]
create_database = {"status": "dry-run", "database": db}
if not args.dry_run:
create_database = http_post_sql(target.http_port, f"CREATE DATABASE IF NOT EXISTS {sql_ident(db)}", "public", args.http_timeout)
- rw, flushes = run_remote_write_ingestion(args.remote_write_generator, target, remote, args, dry_run=args.dry_run)
- physical = remote.get("physical_table", "greptime_physical_table")
+ rw, flushes = run_remote_write_ingestion(helper, target, remote, args, dry_run=args.dry_run)
visibility = {"status": "dry-run"}
query_result = {"validation": [], "validation_errors": [], "measurements": [], "status": "planned"}
if not args.dry_run:
- visibility = poll_expected_count(target, tables[0]["name"], db, expected_remote_write_rows(remote), float(remote.get("visibility_timeout_seconds", 30)), args.http_timeout)
+ visibility = poll_expected_count(target, tables[0]["name"], db, expected_remote_write_rows(remote), float(remote["visibility_timeout_seconds"]), args.http_timeout)
query_result = run_queries(target, case, tables, args.http_timeout)
+ cluster.stop_component("datanode")
+ storage_inspection = None
+ if storage:
+ storage_inspection = run_storage_inspection(helper or args.storage_inspector, target, storage, dry_run=args.dry_run)
+ storage_results.append(storage_inspection)
+ read_bench_result = run_read_bench(args.candidate_bin, target, remote["read_bench"], storage_inspection, dry_run=args.dry_run)
tr = {"name": target.name, "binary": str(target.binary), "work_dir": str(target.work_dir), "components": cluster.component_report(), "frontend_config": str(config_path), "create_database": create_database, "remote_write": rw, "flushes": flushes, "flush": flushes[-1] if flushes else None, "visibility": visibility, **query_result}
+ if storage_inspection is not None:
+ tr["storage_inspection"] = storage_inspection
+ tr["read_bench"] = read_bench_result
flushes_ok = all(flush.get("ok") for flush in flushes)
- remote_checks_ok = args.dry_run or (create_database.get("ok") and flushes_ok and visibility.get("ok") and visibility.get("row_count_ok"))
+ storage_ok = storage_inspection is None or args.dry_run or storage_inspection.get("status") == "ok"
+ read_bench_ok = args.dry_run or read_bench_result.get("status") in ("ok", "skipped")
+ remote_checks_ok = args.dry_run or (create_database.get("ok") and flushes_ok and visibility.get("ok") and visibility.get("row_count_ok") and storage_ok and read_bench_ok)
if not remote_checks_ok:
- tr.setdefault("validation_errors", []).append({"phase": "remote_write_visibility", "create_database_ok": create_database.get("ok"), "flushes_ok": flushes_ok, "visibility_ok": visibility.get("ok"), "row_count_ok": visibility.get("row_count_ok"), "create_database": create_database, "flushes": flushes, "visibility": visibility})
+ tr.setdefault("validation_errors", []).append({"phase": "remote_write_visibility_storage", "create_database_ok": create_database.get("ok"), "flushes_ok": flushes_ok, "visibility_ok": visibility.get("ok"), "row_count_ok": visibility.get("row_count_ok"), "storage_ok": storage_ok, "read_bench_ok": read_bench_ok, "create_database": create_database, "flushes": flushes, "visibility": visibility, "read_bench": read_bench_result})
tr["status"] = "planned" if args.dry_run else ("measured" if remote_checks_ok and query_result["status"] == "ok" else "failed")
write_json(target.report_path, tr)
report["targets"].append(tr)
target_results.append(query_result)
if not args.dry_run:
- report["thresholds"] = enforce_thresholds(case, target_results[0], target_results[1])
+ report["thresholds"] = enforce_thresholds(case, target_results[0], target_results[1]) + enforce_storage_thresholds(storage, storage_results[0] if storage_results else None, storage_results[1] if len(storage_results) > 1 else None)
+ elif storage:
+ report["thresholds"] = planned_storage_thresholds(storage)
report["status"] = "planned" if args.dry_run else ("failed" if any(t["status"] == "failed" for t in report["thresholds"]) or any(t.get("status") == "failed" for t in report["targets"]) else "ok")
finally:
for cluster in reversed(clusters):
@@ -1015,7 +1295,9 @@ def run_remote_write_scenario(args: argparse.Namespace, case: dict[str, Any], ca
def main() -> int:
args = parse_args()
case_path = args.case.resolve()
- case = load_case(case_path)
+ if args.fixture_generator is not None:
+ require_binary(args.fixture_generator, "fixture generator", dry_run=False)
+ case = load_normalized_case(case_path, args.fixture_generator)
scenario_config = scenario(case)
scenario_kind = scenario_config.get("kind")
tables = case_tables(case)
@@ -1025,9 +1307,6 @@ def main() -> int:
require_binary(args.candidate_bin, "candidate", dry_run=args.dry_run or args.fixture_only)
if scenario_kind == "direct_readable_sst" and not args.dry_run and args.fixture_generator is None:
raise ValueError("--fixture-generator is required unless --dry-run is set")
- if args.fixture_generator is not None:
- require_binary(args.fixture_generator, "fixture generator", dry_run=args.dry_run)
-
ports = allocate_ports(16)
targets = [make_target("base", args.base_bin.resolve(), work_root, ports[:8]), make_target("candidate", args.candidate_bin.resolve(), work_root, ports[8:])]
require_fresh_work_dirs(targets, reuse_work_dir=args.reuse_work_dir, dry_run=args.dry_run, fixture_only=args.fixture_only)
diff --git a/tests/perf/test_query_regression_runner_compaction_toctou.py b/tests/perf/test_query_regression_runner_compaction_toctou.py
new file mode 100644
index 00000000000..675f451a10e
--- /dev/null
+++ b/tests/perf/test_query_regression_runner_compaction_toctou.py
@@ -0,0 +1,158 @@
+#!/usr/bin/env python3
+# Copyright 2023 Greptime Team
+#
+# Licensed under the Apache License, Version 2.0 (the "License");
+# you may not use this file except in compliance with the License.
+# You may obtain a copy of the License at
+#
+# http://www.apache.org/licenses/LICENSE-2.0
+#
+# Unless required by applicable law or agreed to in writing, software
+# distributed under the License is distributed on an "AS IS" BASIS,
+# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+# See the License for the specific language governing permissions and
+# limitations under the License.
+
+"""Regression coverage for quiescing remote-write storage before read benches."""
+
+import argparse
+import importlib.util
+import sys
+import tempfile
+import unittest
+from pathlib import Path
+from unittest.mock import patch
+
+
+RUNNER_PATH = Path(__file__).with_name("query_regression_runner.py")
+SPEC = importlib.util.spec_from_file_location("query_regression_runner_under_test", RUNNER_PATH)
+assert SPEC is not None and SPEC.loader is not None
+runner = importlib.util.module_from_spec(SPEC)
+sys.modules[SPEC.name] = runner
+SPEC.loader.exec_module(runner)
+
+
+class RemoteWriteCompactionToctouTest(unittest.TestCase):
+ def test_quiesces_each_target_before_storage_inspection_and_read_bench(self) -> None:
+ lifecycle: dict[str, list[str]] = {"base": [], "candidate": []}
+ clusters = []
+
+ class RecordingCluster:
+ def __init__(self, target):
+ self.target = target
+ self.active = set()
+ self.stop_all_calls = 0
+ clusters.append(self)
+
+ def start_all(self, _config_path):
+ self.active.update(("metasrv", "datanode", "frontend"))
+
+ def stop_component(self, name):
+ if name in self.active:
+ lifecycle[self.target.name].append(f'cluster.stop_component("{name}")')
+ self.active.remove(name)
+
+ def stop_all(self):
+ self.stop_all_calls += 1
+ for name in ("frontend", "datanode", "metasrv"):
+ self.stop_component(name)
+
+ def component_report(self):
+ return {}
+
+ def run_queries(target, _case, _tables, _http_timeout):
+ lifecycle[target.name].append("query measurement completes")
+ return {"validation": [], "validation_errors": [], "measurements": [], "status": "ok"}
+
+ def inspect_storage(_helper, target, _storage, *, dry_run):
+ self.assertFalse(dry_run)
+ lifecycle[target.name].append("storage inspection")
+ return {"status": "ok", "summary": {"summary": {}}}
+
+ def read_bench(_binary, target, _read_bench, _inspection, *, dry_run):
+ self.assertFalse(dry_run)
+ lifecycle[target.name].append("read bench")
+ return {"status": "ok"}
+
+ remote_write = {
+ "database": "public",
+ "metric": "cpu_usage",
+ "physical_table": "cpu_usage_physical",
+ "series_count": 1,
+ "samples_per_series": 1,
+ "visibility_timeout_seconds": 1,
+ "storage": {
+ "inspect": True,
+ "min_files": None,
+ "min_files_with_column": None,
+ "max_total_file_size_bytes": None,
+ "max_column_compressed_size_bytes": None,
+ "max_column_uncompressed_size_bytes": None,
+ "require_encodings": [],
+ "forbid_encodings": [],
+ },
+ "read_bench": {"enabled": True},
+ "prom_store": {
+ "pending_rows_flush_interval": "1s",
+ "max_batch_rows": 1,
+ "max_concurrent_flushes": 1,
+ "worker_channel_capacity": 1,
+ "max_inflight_requests": 1,
+ },
+ }
+ case = {
+ "scenario": {
+ "kind": "prom_remote_write_then_query",
+ "remote_write": remote_write,
+ "queries": [],
+ }
+ }
+ args = argparse.Namespace(
+ fixture_only=False,
+ fixture_generator=Path("/bin/true"),
+ remote_write_generator=None,
+ storage_inspector=None,
+ candidate_bin=Path("/bin/true"),
+ dry_run=False,
+ http_timeout=1.0,
+ )
+
+ with tempfile.TemporaryDirectory() as tmpdir:
+ root = Path(tmpdir)
+ targets = [
+ runner.make_target("base", Path("/bin/true"), root, list(range(10000, 10008))),
+ runner.make_target("candidate", Path("/bin/true"), root, list(range(10008, 10016))),
+ ]
+ report = {"targets": [], "thresholds": []}
+ with (
+ patch.object(runner, "DistributedCluster", RecordingCluster),
+ patch.object(runner, "run_remote_write_ingestion", return_value=({"status": "ok"}, [{"ok": True}])),
+ patch.object(runner, "http_post_sql", return_value={"ok": True}),
+ patch.object(runner, "poll_expected_count", return_value={"ok": True, "row_count_ok": True}),
+ patch.object(runner, "run_queries", side_effect=run_queries),
+ patch.object(runner, "run_storage_inspection", side_effect=inspect_storage),
+ patch.object(runner, "run_read_bench", side_effect=read_bench),
+ ):
+ runner.run_remote_write_scenario(args, case, root / "case.toml", targets, report)
+
+ for cluster in clusters:
+ self.assertEqual(cluster.stop_all_calls, 1)
+ self.assertEqual(cluster.active, set())
+ cluster.stop_all()
+ self.assertEqual(cluster.stop_all_calls, 2)
+ self.assertEqual(cluster.active, set())
+
+ expected = [
+ "query measurement completes",
+ 'cluster.stop_component("datanode")',
+ "storage inspection",
+ "read bench",
+ ]
+ relevant = {name: [event for event in events if event in expected] for name, events in lifecycle.items()}
+ for target_name in ("base", "candidate"):
+ with self.subTest(target=target_name):
+ self.assertEqual(relevant[target_name], expected)
+
+
+if __name__ == "__main__":
+ unittest.main()